Which GPU should you actually use for embedding workloads?
Selecting the right serving engine for your embedding model can dramatically outperform hardware upgrades, yielding up to an 11x throughput increase on the same GPU.
All
 Skip to main content
Blog
Deploy any Hugging Face large language model using Runpod's configurable templates. Customize your endpoint with ease and launch scalable LLM deployments.


Runpod introduces Configurable Templates, a powerful feature that allows users to easily deploy and run any large language model.
With this feature, users can provide the Hugging Face model name and customize various template parameters to create tailored endpoints for their specific needs.
Configurable Templates offer several benefits to users:
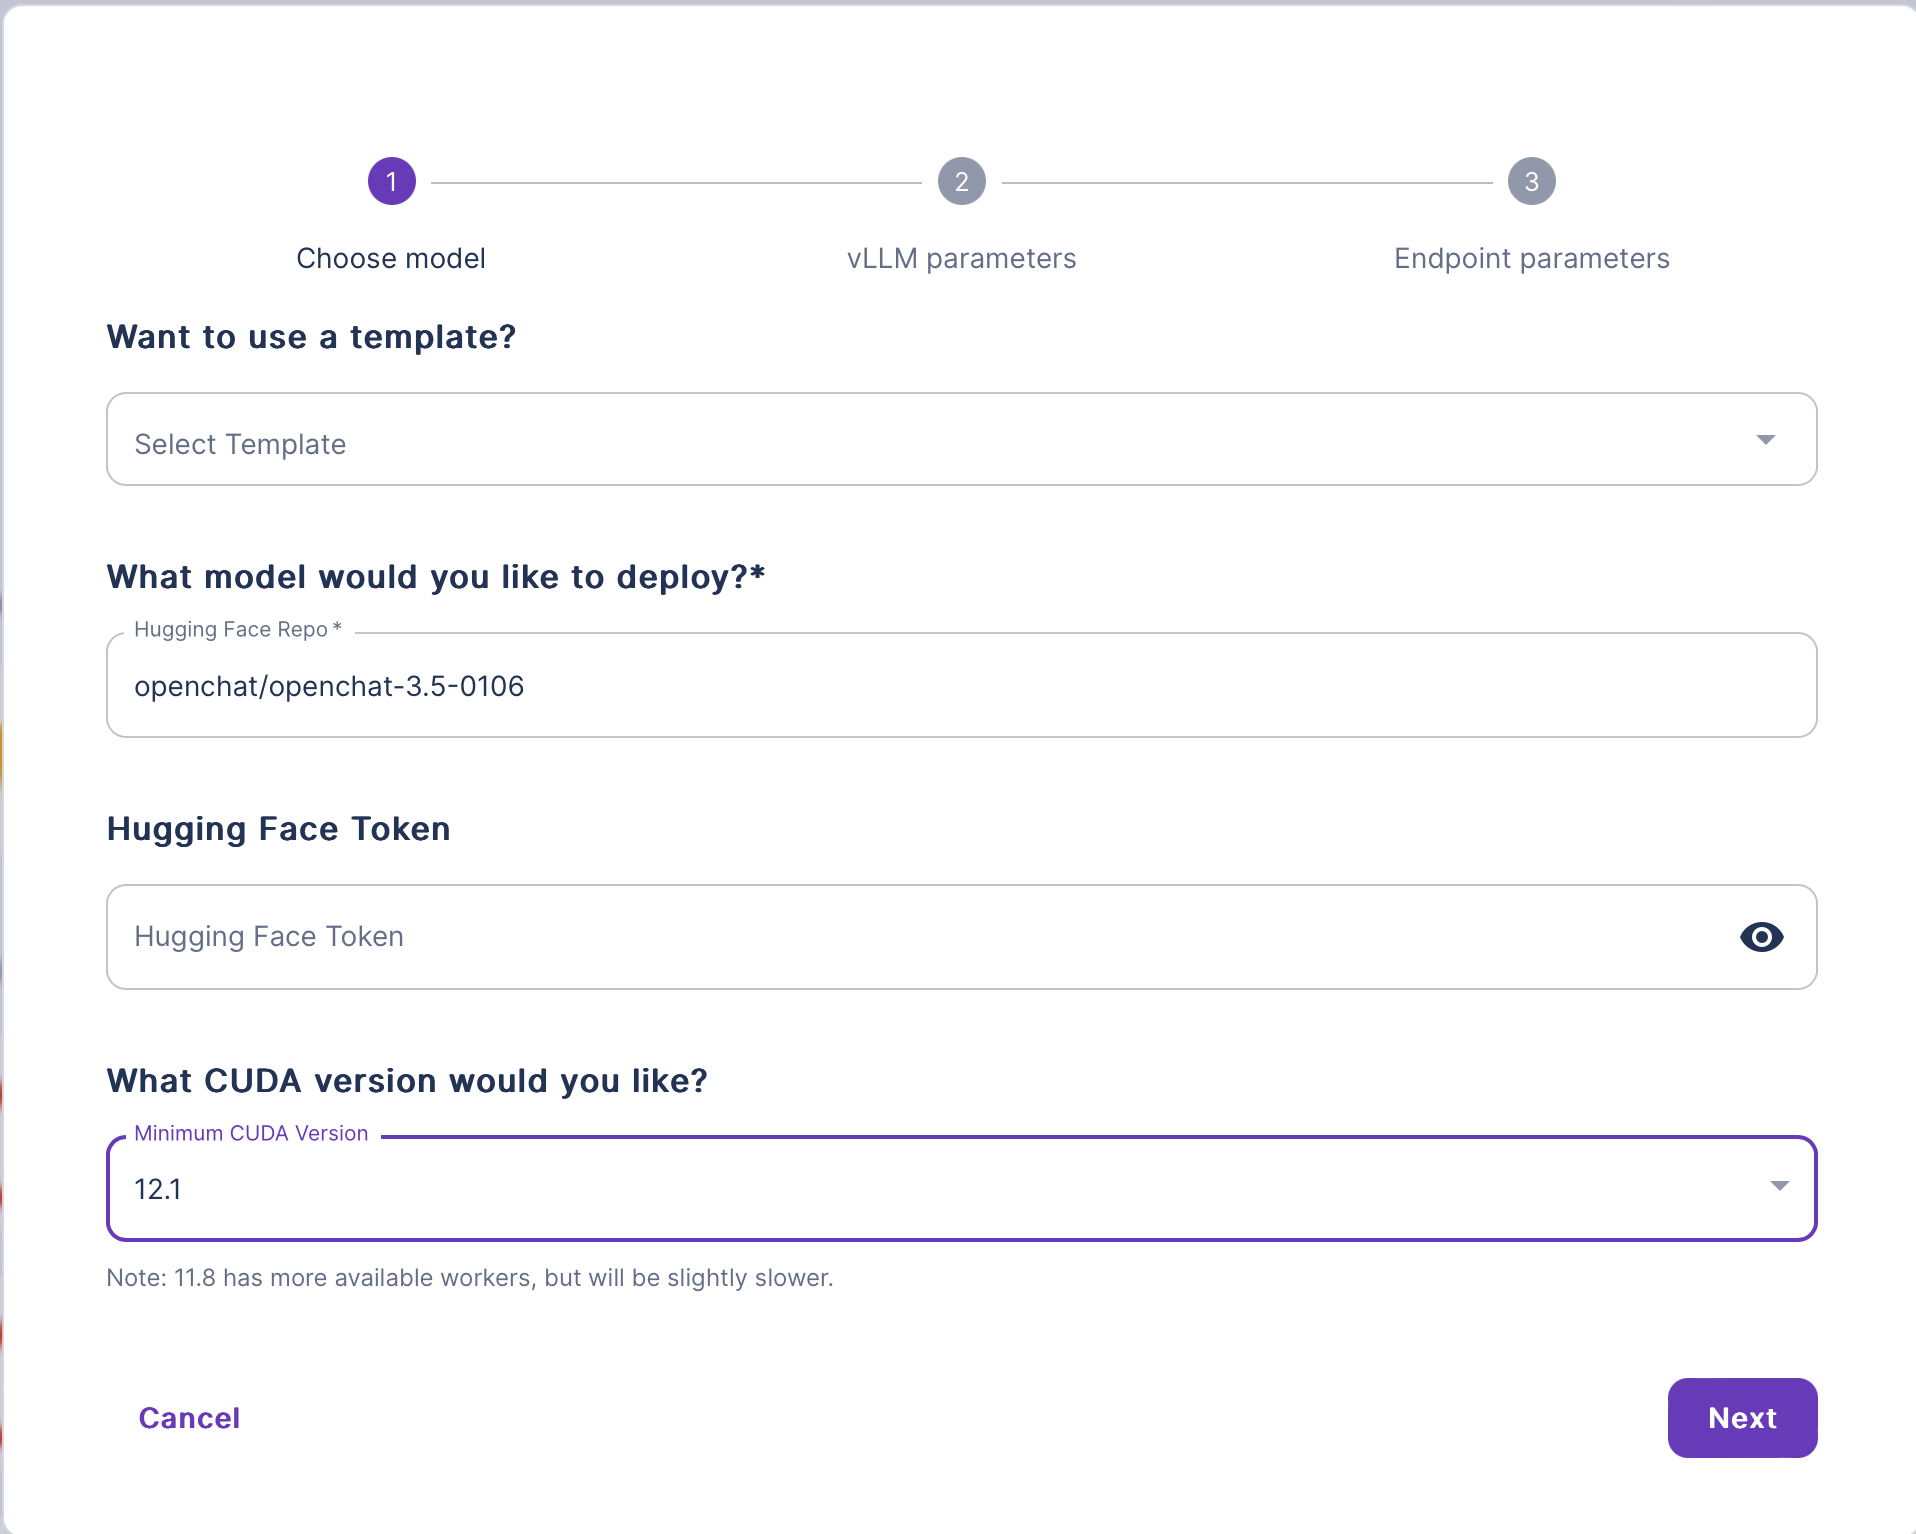
Follow these steps to deploy a large language model using Configurable Templates:
Once the deployment is complete, your LLM will be accessible via an Endpoint. You can interact with your model using the provided API.
💡
Runpod supports any model architecture that can run on vLLM with configurable templates.
By integrating vLLM into the Configurable Templates feature, Runpod simplifies the process of deploying and running large language models. Users can focus on selecting their desired model and customizing the template parameters, while vLLM takes care of the low-level details of model loading, hardware configuration, and execution.
Author profile: Brendan McKeag
Blog Posts