


"We didn't seriously evaluate other alternatives before committing to Runpod. We found their approach interesting from the beginning, particularly the ease of integration, and we haven't had a reason to switch since."

"AWS is very reliable and has everything we need, but it is way more expensive than Runpod. With Runpod, we can choose the right card for the job."
"Runpod is easily one of the most scalable tools that we use in our infrastructure."
"What's happened is, moving to Runpod, Botto has a better GPU, better graphic models and better resources, but it also costs less. That's something I didn't expect we were going to have."


"You guys have genuinely changed the scope of what we've been able to attempt."
"All of these projects, the renders for AMD, the Coca-Cola builds, that has to do with scalability. If we can't scale, we can't deliver. Runpod makes that possible."
"Runpod has changed the way we ship because we no longer have to wonder if we have access to GPUs. We've saved probably 90% on our infrastructure bill, mainly because we can use bursty compute whenever we need it."

"Runpod has allowed the team to focus more on the features that are core to our product and that are within our skill set, rather than spending time focusing on infrastructure, which can sometimes be a bit of a distraction.”

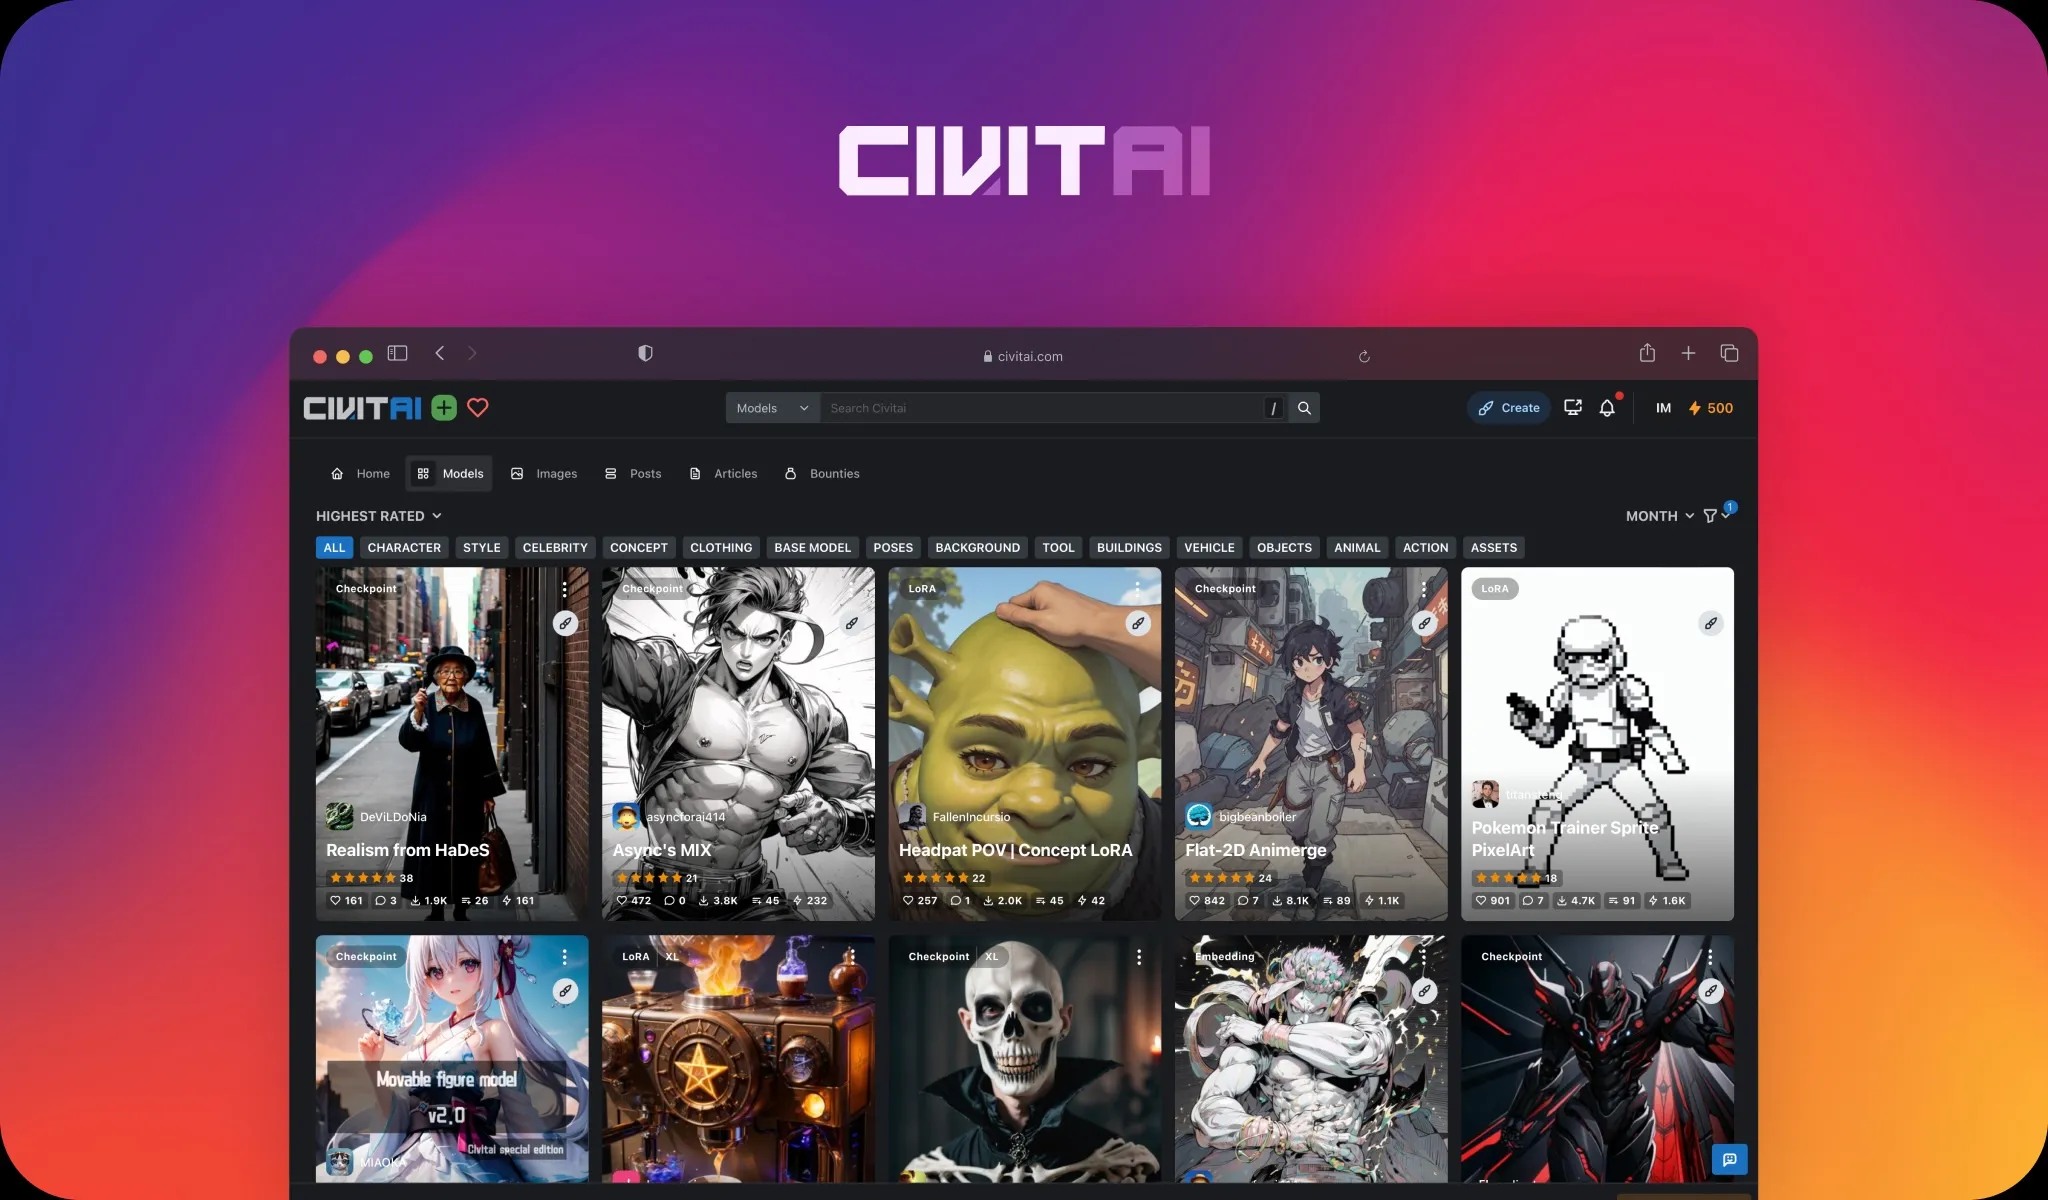
"Runpod helped us scale the part of our platform that drives creation. That’s what fuels the rest, image generation, sharing, remixing. It starts with training."

"Runpod allowed us to reliably handle scaling from zero to over 1,000 requests per second in our live application."

"Runpod has allowed us to focus entirely on growth and product development without us having to worry about the GPU infrastructure at all."

"We could stop worrying about infrastructure and go back to building. That’s the real win.”

“The main value proposition for us was the flexibility Runpod offered. We were able to scale up effortlessly to meet the demand at launch.”

"After migration, we were able to cut down our server costs from thousands of dollars per day to only hundreds."
Runpod’s scalable GPU infrastructure gave us the flexibility we needed to match customer traffic and model complexity, without overpaying for idle resources.