Quick answer
To run Wan 2.2 in ComfyUI on Runpod, deploy the official ComfyUI template on a Secure Cloud pod, download the Wan 2.2 files to /workspace/runpod-slim/ComfyUI/models and open the Wan 2.2 template in ComfyUI. The 14B models need 24 GB of VRAM at 640x640 with fp8 weights. With the Lightning LoRA, a 5-second clip takes about 71 seconds instead of about 513.
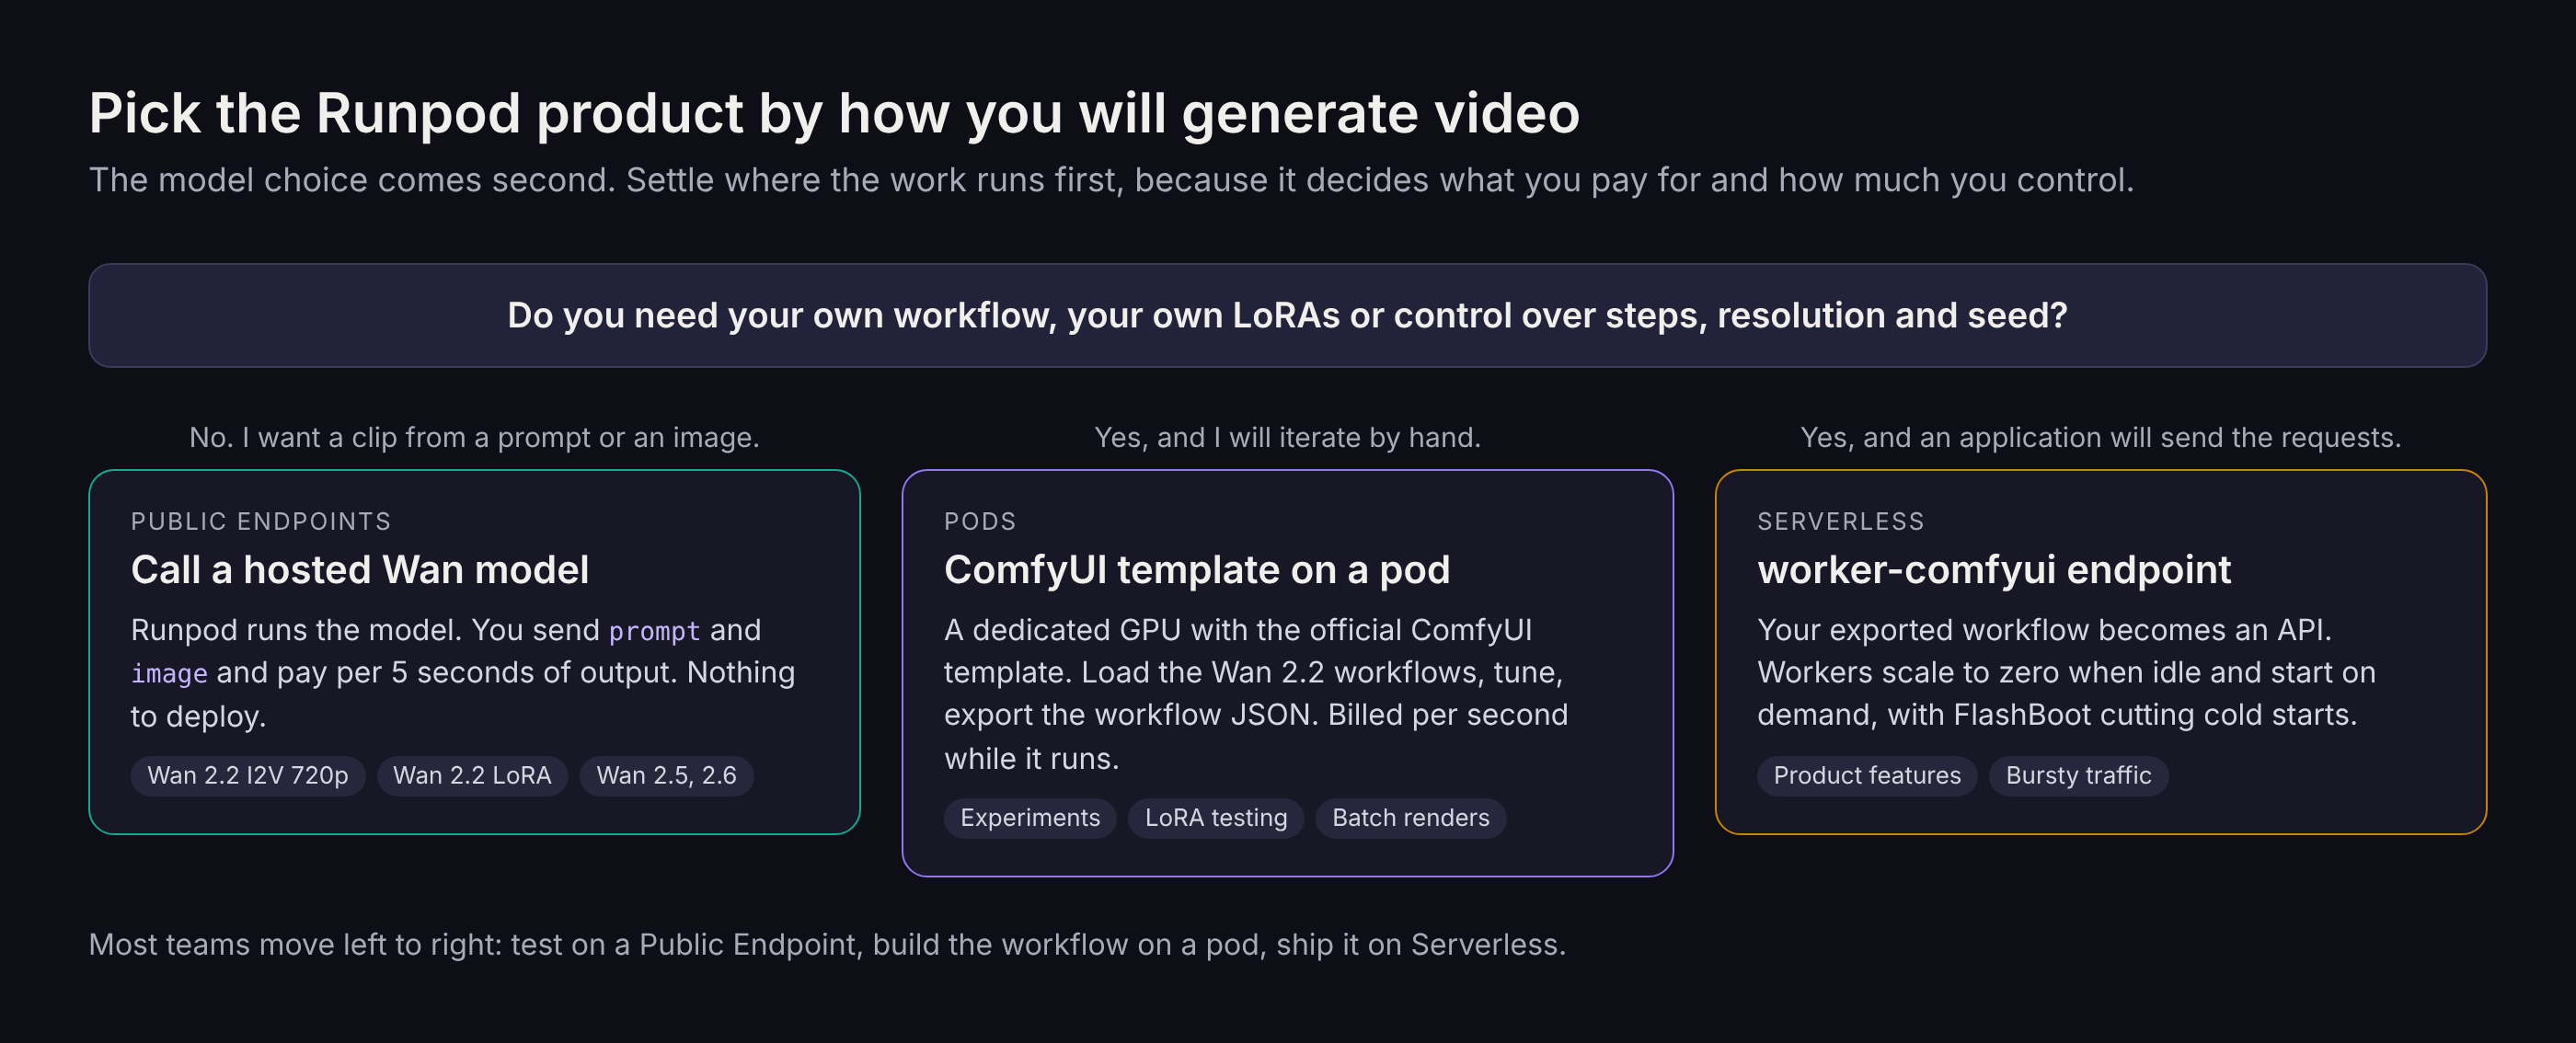
Runpod, the AI developer cloud, gives you three ways to run Wan 2.2. A Public Endpoint returns a clip from a prompt and an image with nothing to deploy. A pod running ComfyUI gives you full control of the workflow. A Serverless endpoint running worker-comfyui turns that workflow into an API that scales to zero. This guide covers all three, starting with the pod, because that is where you build and tune the workflow. A 24 GB RTX A5000 pod costs $0.27/hr on Secure Cloud, billed per second, and current rates for every card are on the Runpod pricing page.
Key facts
| Item | Current state (October 2026) | Source |
|---|---|---|
| Open-weight Wan 2.2 models | T2V-A14B, I2V-A14B, TI2V-5B, S2V-14B, Animate-14B and Animate-2-14B | Wan2.2 repository |
| License | Apache 2.0 | Wan2.2 repository |
| 14B architecture | Mixture of experts: two 14B experts, 27B parameters total, 14B active per step | Wan2.2 repository |
| Native frame rate | 16 fps for the 14B models, 24 fps for TI2V-5B | Wan2.2 configs |
| Default clip length | 81 frames (about 5 seconds) for 14B, 121 frames for TI2V-5B; frame counts follow 4n+1 | generate.py |
| ComfyUI default for 14B | 20 steps at CFG 3.5, with an optional 4-step Lightning LoRA path at CFG 1 | ComfyUI workflow templates |
| Wan 2.2 Animate in ComfyUI | One 14B model (18.4 GB in fp8), Move and Mix modes, 77-frame segments at 16 fps | ComfyUI Animate docs |
| Smallest practical GPU | 24 GB for 14B with fp8 weights at 640x640; TI2V-5B fits 8 GB with ComfyUI offloading | ComfyUI docs, template notes |
| Official Runpod ComfyUI template | ComfyUI with CUDA 12.8, ComfyUI-Manager, ComfyUI-KJNodes, Civicomfy and ComfyUI-RunpodDirect; installs to /workspace/runpod-slim/ComfyUI | comfyui-base |
| Pod billing | Per second while the pod runs | Pod pricing docs |
| Wan 2.2 I2V 720p Public Endpoint | $0.30 per 5 seconds of output as of October 2026 | Endpoint docs |
| Newer Wan versions | Wan 2.5, 2.6 and 2.7 are API-only, with no open weights | Alibaba Cloud Model Studio |
Choose how you will run Wan 2.2
Pick the Runpod product before you pick a model variant, because the product decides what you pay for and how much of the pipeline you control.
What Wan 2.2 is
Wan 2.2 is Alibaba's open-weight video generation family, released on July 28, 2025 under the Apache 2.0 license. It generates video from text, from a start image, from speech and from a reference performance. ComfyUI supported it natively on release day, and its official templates are the most direct way to run it.
| Model | Task | Native output | Released |
|---|---|---|---|
| T2V-A14B | Text to video | 480p or 720p, 16 fps | July 28, 2025 |
| I2V-A14B | Image to video | 480p or 720p, 16 fps | July 28, 2025 |
| TI2V-5B | Text or image to video in one model | 1280x704 or 704x1280, 24 fps | July 28, 2025 |
| S2V-14B | Speech to video | 480p or 720p | August 26, 2025 |
| Animate-14B | Character animation and replacement from a reference video | 720p | September 19, 2025 |
| Animate-2-14B | End-to-end character animation with text-driven viewpoint control | See model card | August 7, 2026 |
Two corrections to what circulates about Wan 2.2. First, Wan 2.5, 2.6 and 2.7 are not newer open models you can download into ComfyUI. Alibaba serves them through its Model Studio API, and as of October 2026 none has public weights, so Wan 2.2 remains the newest Wan family you can run on your own GPU. Second, Wan 2.2 14B is not a single 14B network. It is two.
The 14B models are two experts that take turns
The A14B models use a mixture-of-experts (MoE) design with two experts of about 14B parameters each, 27B in total. The high-noise expert handles the early denoising steps, where the latent is mostly noise and the model is deciding layout and motion. The low-noise expert takes over for the later steps and refines texture and detail. Only one expert runs at each step, so compute per step stays at 14B parameters.
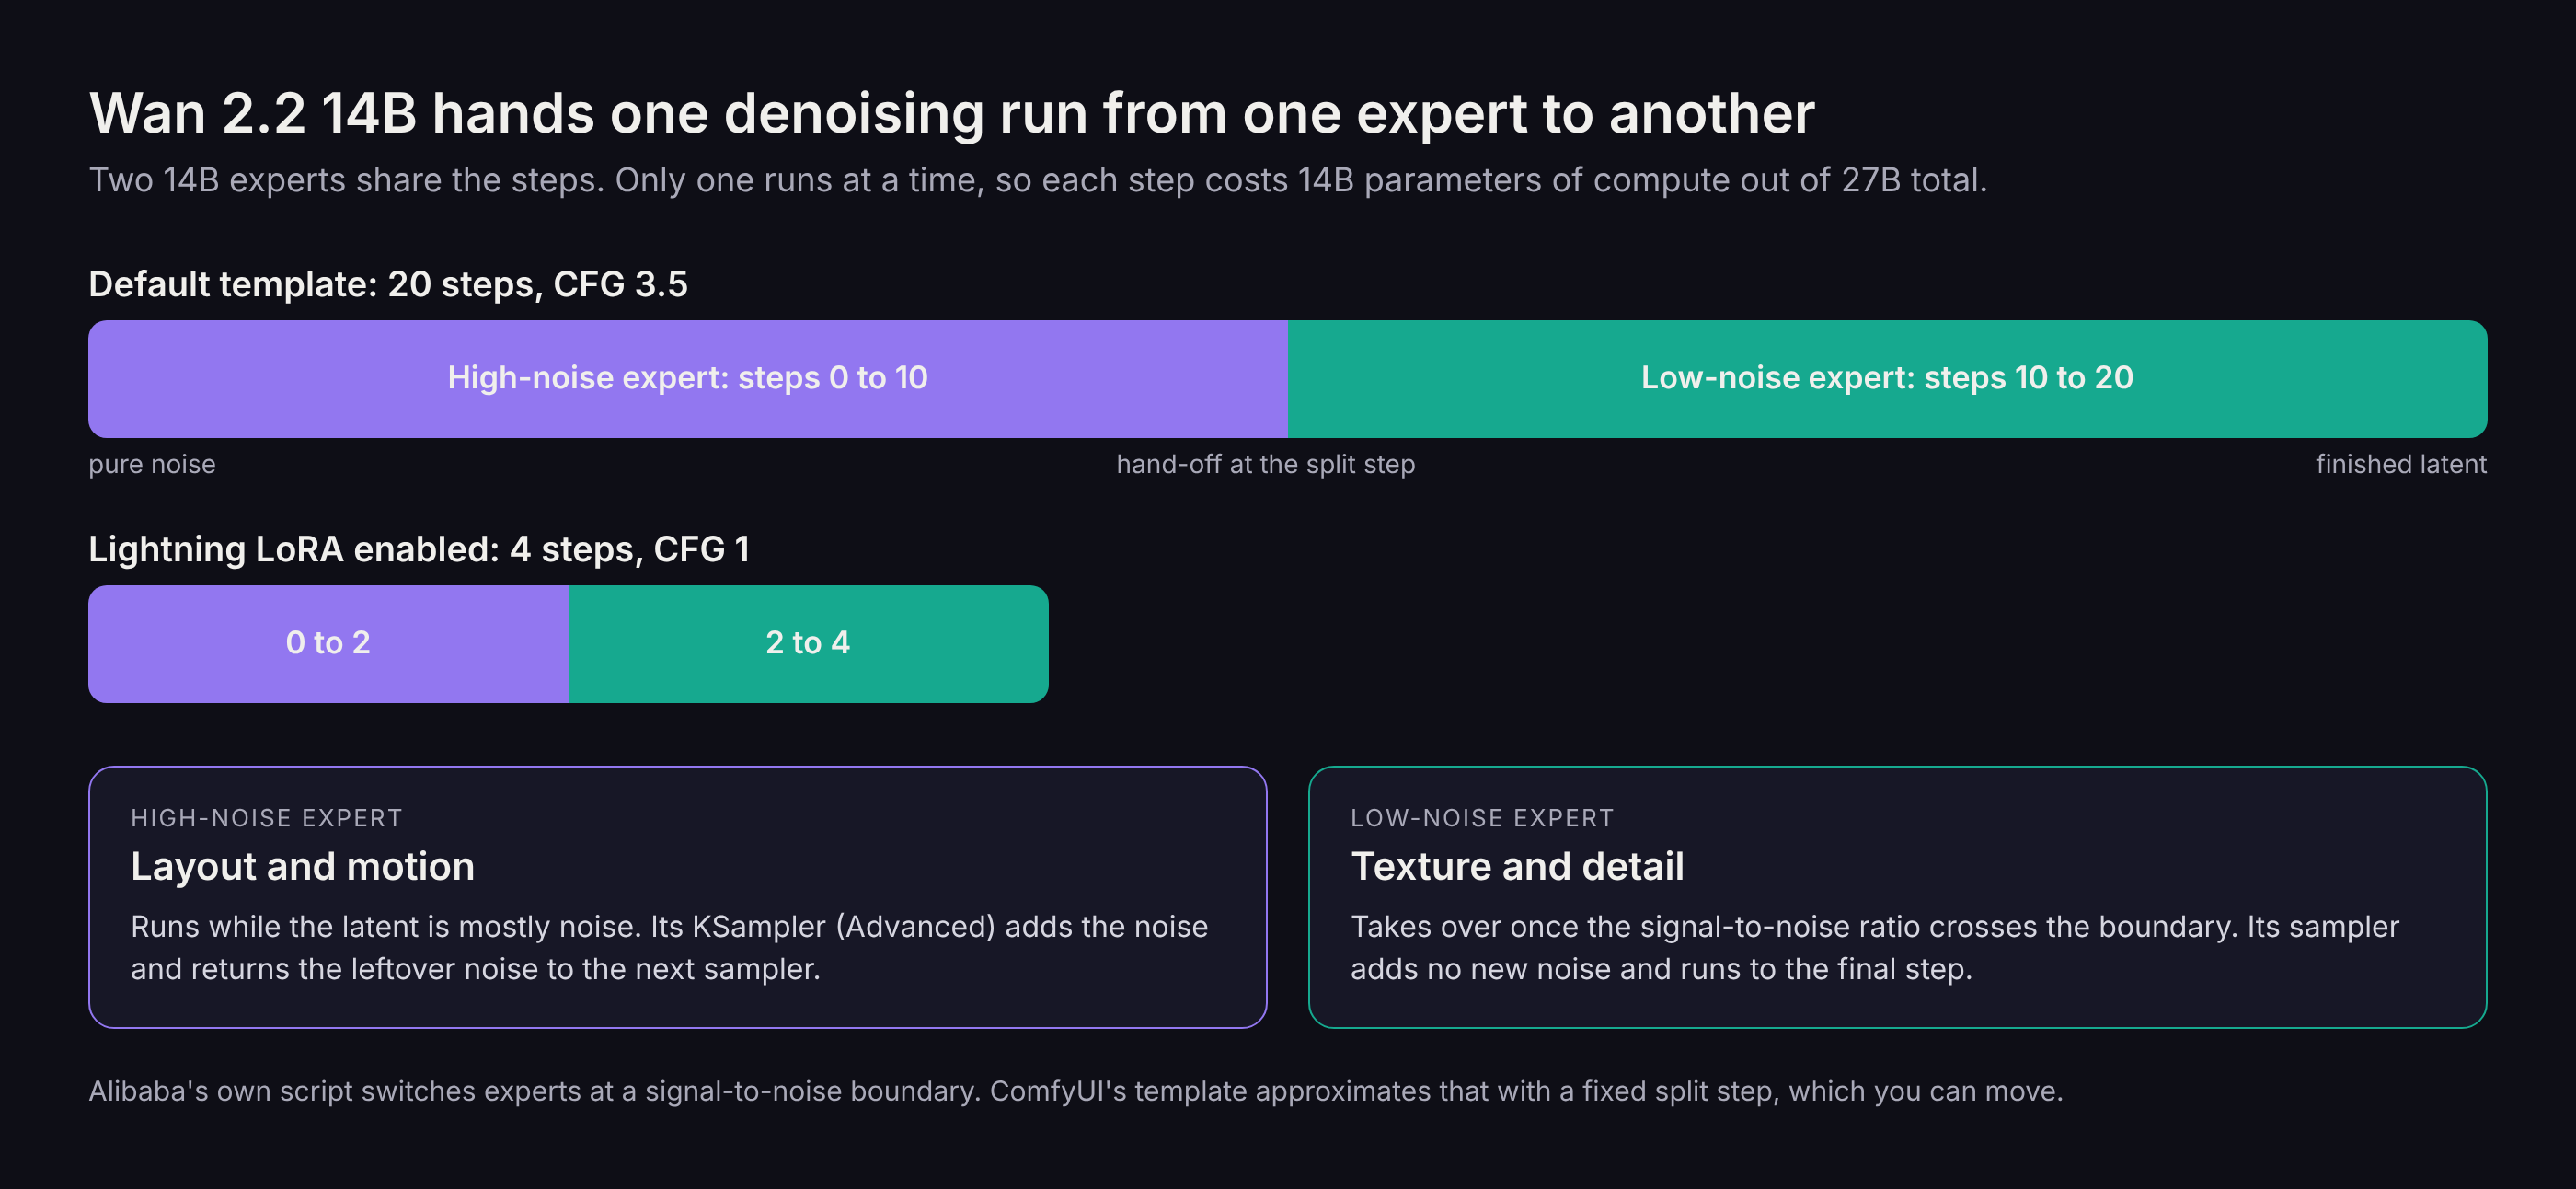
This design has three practical consequences. You download two diffusion model files for every 14B task, and the text-to-video pair does not work for image-to-video. The ComfyUI workflow needs two model loaders and two KSampler (Advanced) nodes, one per expert. And memory planning works per expert: ComfyUI's model manager can keep the active expert on the GPU and move the idle one to system RAM, so a card that holds one expert can run the pair, at the cost of a transfer at the hand-off.
Alibaba's reference script switches experts at a signal-to-noise ratio (SNR) boundary, which falls at a timestep of 0.875 for text-to-video and 0.900 for image-to-video. ComfyUI's template approximates the boundary with a fixed split at the midpoint of the step count. If clips come out with good motion but soft detail, move the split one or two steps earlier so the low-noise expert gets more steps.
TI2V-5B trades quality for a much smaller footprint
TI2V-5B is a single dense 5B model that handles both text-to-video and image-to-video. It pairs with a new Wan 2.2 VAE (variational autoencoder) that compresses 4x16x16 across time, height and width, and with its patchify layer the total compression reaches 4x32x32. That compression is how it produces 720p at 24 fps from a 10 GB checkpoint. It is the right model for fast iteration on a small card. The 14B pair produces stronger motion and detail, and it is the model to use for final renders.
Wan 2.2 GPU requirements
VRAM decides the card. The weights of the expert that is running must fit in GPU memory alongside the activations for every frame in the clip, and activations grow with both resolution and frame count. Figure 3 shows the weights alone.
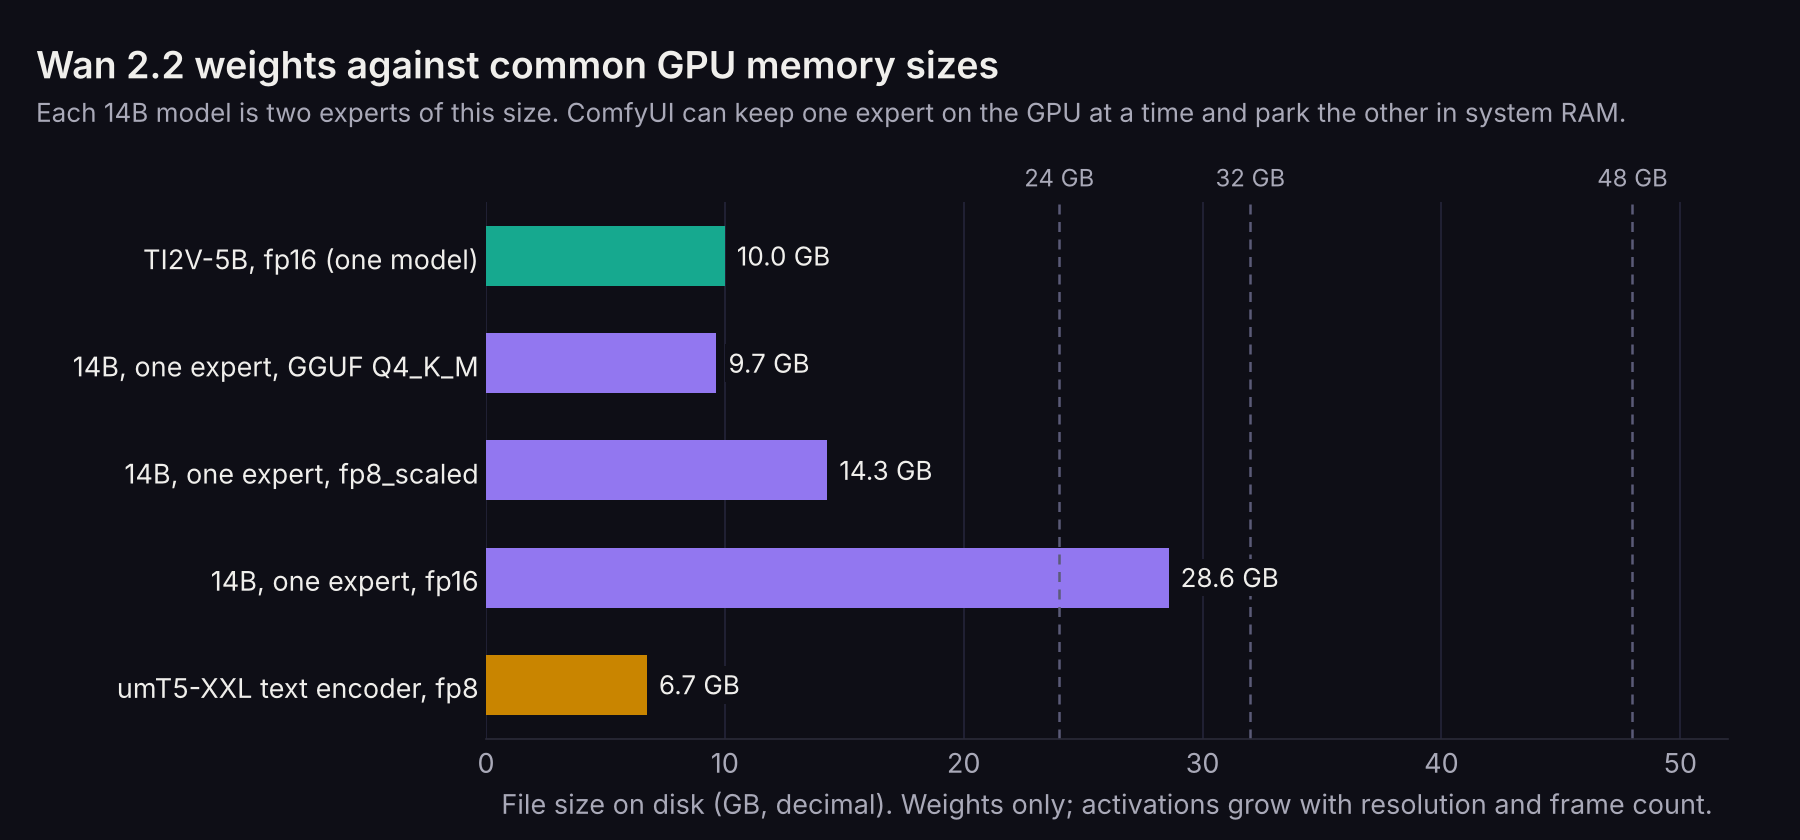
The arithmetic follows from the file sizes. One 14B expert in fp8 is 14.3 GB, so it fits on a 24 GB card with about 10 GB left for activations at 640x640, which is the configuration ComfyUI's template authors measured at 83% to 89% VRAM use on a 24 GB GPU. The same expert in fp16 is 28.6 GB, so fp16 weights need a 48 GB card at 640x640 or 480p. A 1280x720 frame has 2.3 times the pixels of an 832x480 frame, and Alibaba's own script peaked at 59.8 GB on a single GPU at 720p versus 41.3 GB at 480p. That 59.8 GB peak is why 720p without offloading belongs on an 80 GB card. These GPU recommendations are derived from those figures rather than measured on each card, so treat the boundaries as starting points.
| Workload | VRAM guidance | Suggested GPU | Secure Cloud rate |
|---|---|---|---|
| TI2V-5B at 1280x704 | 24 GB (8 GB with ComfyUI offloading) | RTX A5000 (24 GB) | $0.27/hr |
| TI2V-5B on an inference-focused card | 24 GB | L4 (24 GB) | $0.69/hr |
| 14B fp8 at 640x640 or 480p, 20 steps or Lightning | 24 GB | RTX A5000 (24 GB) | $0.27/hr |
| 14B fp8 with headroom for longer clips or LoRAs | 48 GB | RTX A6000 (48 GB) | $0.69/hr |
| 14B fp8 at 720p | 48 GB | L40S (48 GB) | $1.09/hr |
| 14B fp16 weights at 640x640 or 480p | 48 GB | L40S (48 GB) | $1.09/hr |
| 14B at 720p without offloading (59.8 GB peak in Alibaba's script) | 80 GB | H100 SXM (80 GB) or RTX PRO 6000 (96 GB) | $4.39/hr or $2.69/hr |
Speed is the second axis. Alibaba's published benchmark for the 14B text-to-video model shows the H100 finishing a clip 2.4x faster than the A100 at 480p and 2.6x faster at 720p. Because pods bill per second, a faster card can cost less per clip even at a higher hourly rate, so compare cards on cost per finished clip, not on rate per hour.

The two figures are not interchangeable with ComfyUI timings. Alibaba's script runs 40 steps by default and the ComfyUI template runs 20, so expect ComfyUI to finish faster on the same card. Use Figure 4 for the ratio between GPUs, not for an absolute time.
Run Wan 2.2 in ComfyUI on a Runpod pod
A pod is a container running on a dedicated GPU that you rent by the second and reach through your browser. The setup takes six steps.
1. Create an account and add credits
Sign up at runpod.io and add credits. Deploying a pod requires at least one hour of credit for the GPU you choose, and the pod bills per second from then on, as the pod pricing docs explain.
2. Create a network volume
A network volume is persistent storage that exists independently of any pod. Wan 2.2 makes it close to mandatory, because the 14B text-to-video files alone total 38 GB, and downloading them again every session wastes both time and GPU billing. Network volumes are available on Secure Cloud, and you attach one when you create the pod. It cannot be attached later. The network volume docs cover the details.
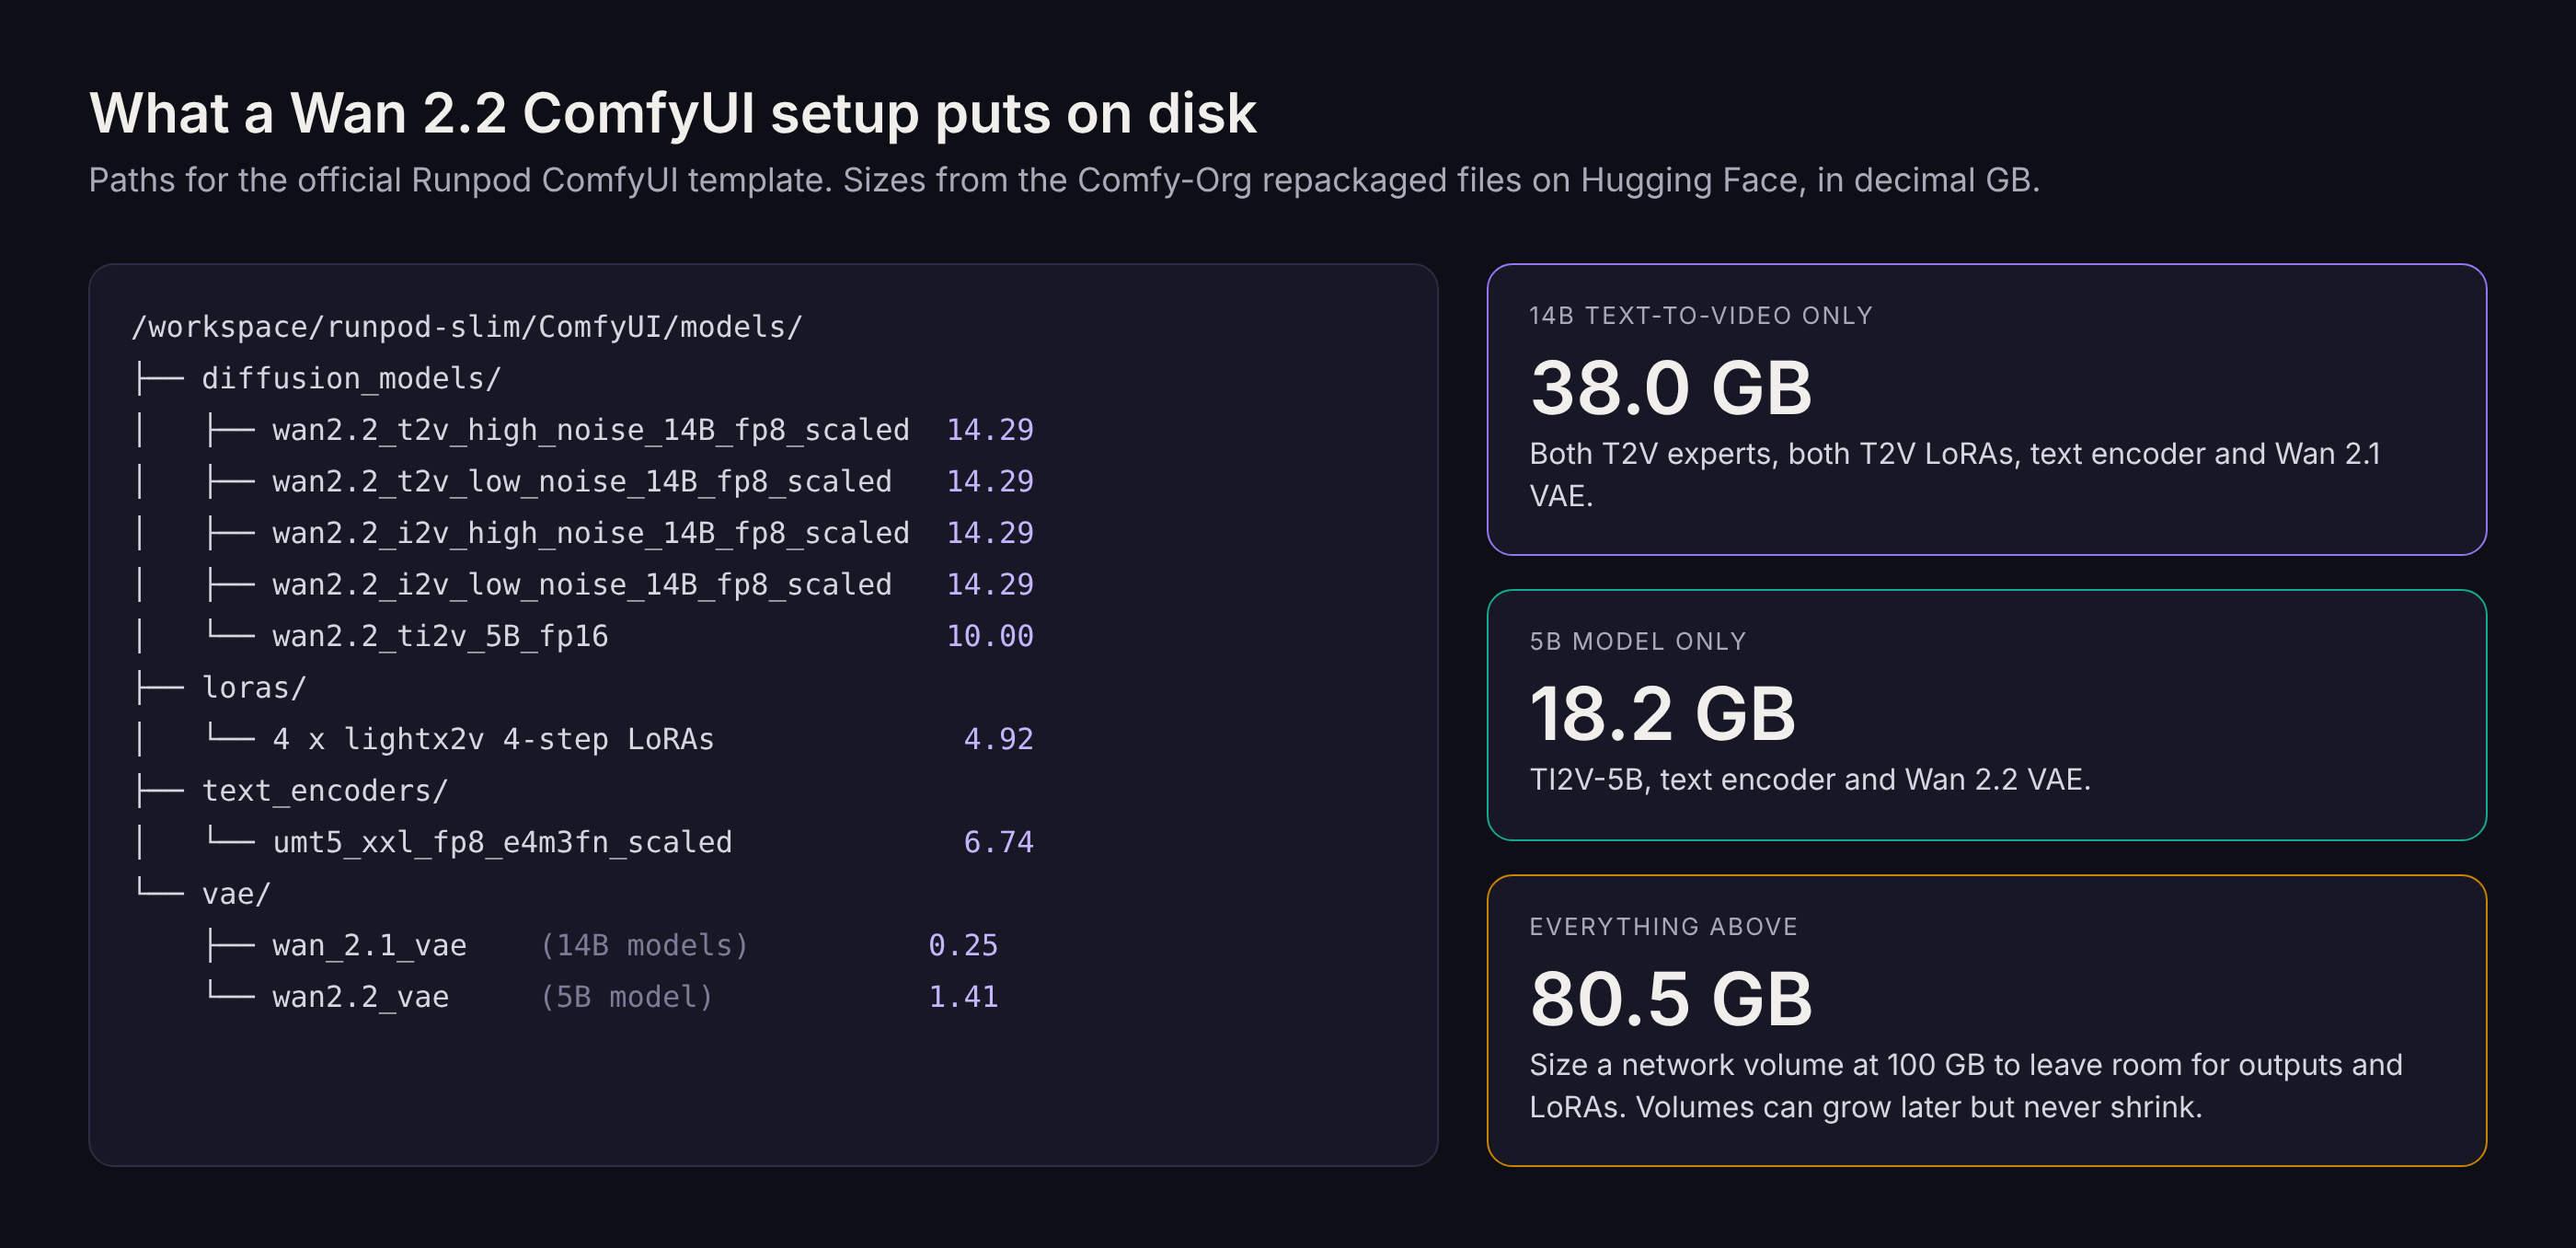
Size the volume from Figure 5. A 100 GB volume holds every Wan 2.2 file the official templates use, and at the standard tier's $0.07/GB/month for the first 1 TB as of October 2026 it costs about $7 a month. The volume bills whether or not a pod is attached. You can increase its size later but never decrease it. Create it in a Secure Cloud datacenter that offers the GPU you plan to use, because later pods must deploy in the same datacenter to mount it.
3. Deploy the official ComfyUI template
In the Runpod console, start a new pod, choose your GPU and select the ComfyUI template, which Runpod maintains. Attach the network volume, which mounts at /workspace, and deploy on Secure Cloud. The template ships the current ComfyUI build on CUDA 12.8 with ComfyUI-Manager, ComfyUI-KJNodes, Civicomfy and ComfyUI-RunpodDirect installed. For Blackwell GPUs such as the B200, Runpod's documentation points to a separate ComfyUI template for Blackwell GPUs.
If you want the models downloaded for you, use the One Click - ComfyUI Wan2.1 - Wan 2.2 template on the Runpod Hub, published by HearmemanAI. It downloads models and workflows on first boot according to flags you set under Edit Template before you deploy, and every flag defaults to false. Set download_wan22 to true for Wan 2.2, and add download_wan21 or download_wan_animate if you want those workflows too. A pod with no flag set boots an empty ComfyUI whose workflows show blank model dropdowns. Three more settings matter before you deploy:
- As of October 19, 2026 the template is built for CUDA 13.0 and above, so filter for GPUs whose host supports CUDA 13 when you choose the card. A host on an older driver may fail to start the container.
- The template defaults to a 300 GB volume and a 300 GB container disk. Both bill at $0.10/GB/month while the pod runs, so the pair costs about $60 a month before any GPU time. Lower both if you only need Wan 2.2.
- First boot takes 5 to 20 minutes depending on the flags. ComfyUI opens on port 8188 while models are still downloading, and the boot log is at
/workspace/comfyui.log.
The author supports the template through a Discord server rather than Runpod support, so check its description for changes before you rely on these settings.
On first boot the official template copies ComfyUI into your workspace, which can take several minutes, and Runpod's documentation allows up to 30 minutes for a first start. ComfyUI is ready when the pod logs show this line:
[ComfyUI-Manager] All startup tasks have been completed.4. Download the Wan 2.2 model files
Download models directly on the pod, because a datacenter connection is far faster than uploading from your machine. Open JupyterLab on port 8888 or the web terminal from the Connect panel and run the block below. It downloads the umT5 text encoder and the Wan 2.1 VAE that every 14B workflow shares, then both experts and both Lightning LoRAs for text-to-video and for image-to-video. Delete the two i2v lines if you only need text-to-video. The URLs point at the Comfy-Org repackaged files that ComfyUI's official templates load. The Wan 2.1 repository name ends in a lowercase repackaged and the Wan 2.2 repository name in a capitalized Repackaged, and both spellings are correct.
cd /workspace/runpod-slim/ComfyUI/models
HF=https://huggingface.co/Comfy-Org
wget -P text_encoders $HF/Wan_2.1_ComfyUI_repackaged/resolve/main/split_files/text_encoders/umt5_xxl_fp8_e4m3fn_scaled.safetensors
wget -P vae $HF/Wan_2.1_ComfyUI_repackaged/resolve/main/split_files/vae/wan_2.1_vae.safetensors
for f in high low; do
  wget -P diffusion_models $HF/Wan_2.2_ComfyUI_Repackaged/resolve/main/split_files/diffusion_models/wan2.2_t2v_${f}_noise_14B_fp8_scaled.safetensors
  wget -P loras $HF/Wan_2.2_ComfyUI_Repackaged/resolve/main/split_files/loras/wan2.2_t2v_lightx2v_4steps_lora_v1.1_${f}_noise.safetensors
  wget -P diffusion_models $HF/Wan_2.2_ComfyUI_Repackaged/resolve/main/split_files/diffusion_models/wan2.2_i2v_${f}_noise_14B_fp8_scaled.safetensors
  wget -P loras $HF/Wan_2.2_ComfyUI_Repackaged/resolve/main/split_files/loras/wan2.2_i2v_lightx2v_4steps_lora_v1_${f}_noise.safetensors
done
For TI2V-5B, download wan2.2_ti2v_5B_fp16.safetensors into diffusion_models and wan2.2_vae.safetensors into vae from the same Wan 2.2 repository. It uses the same text encoder. Each template also lists its files, with links and target folders, in a note on the canvas, so you can check names there.
5. Open ComfyUI and load the Wan 2.2 template
Open the pod's Connect panel and select the HTTP service on port 8188. Runpod serves it through a proxy URL of the form https://<pod-id>-8188.proxy.runpod.net. If the page returns a Bad Gateway error, ComfyUI is still starting, so wait two or three minutes and refresh. In ComfyUI, open Templates in the left sidebar and search for Wan 2.2, then select the 14B text-to-video or 14B image-to-video template.
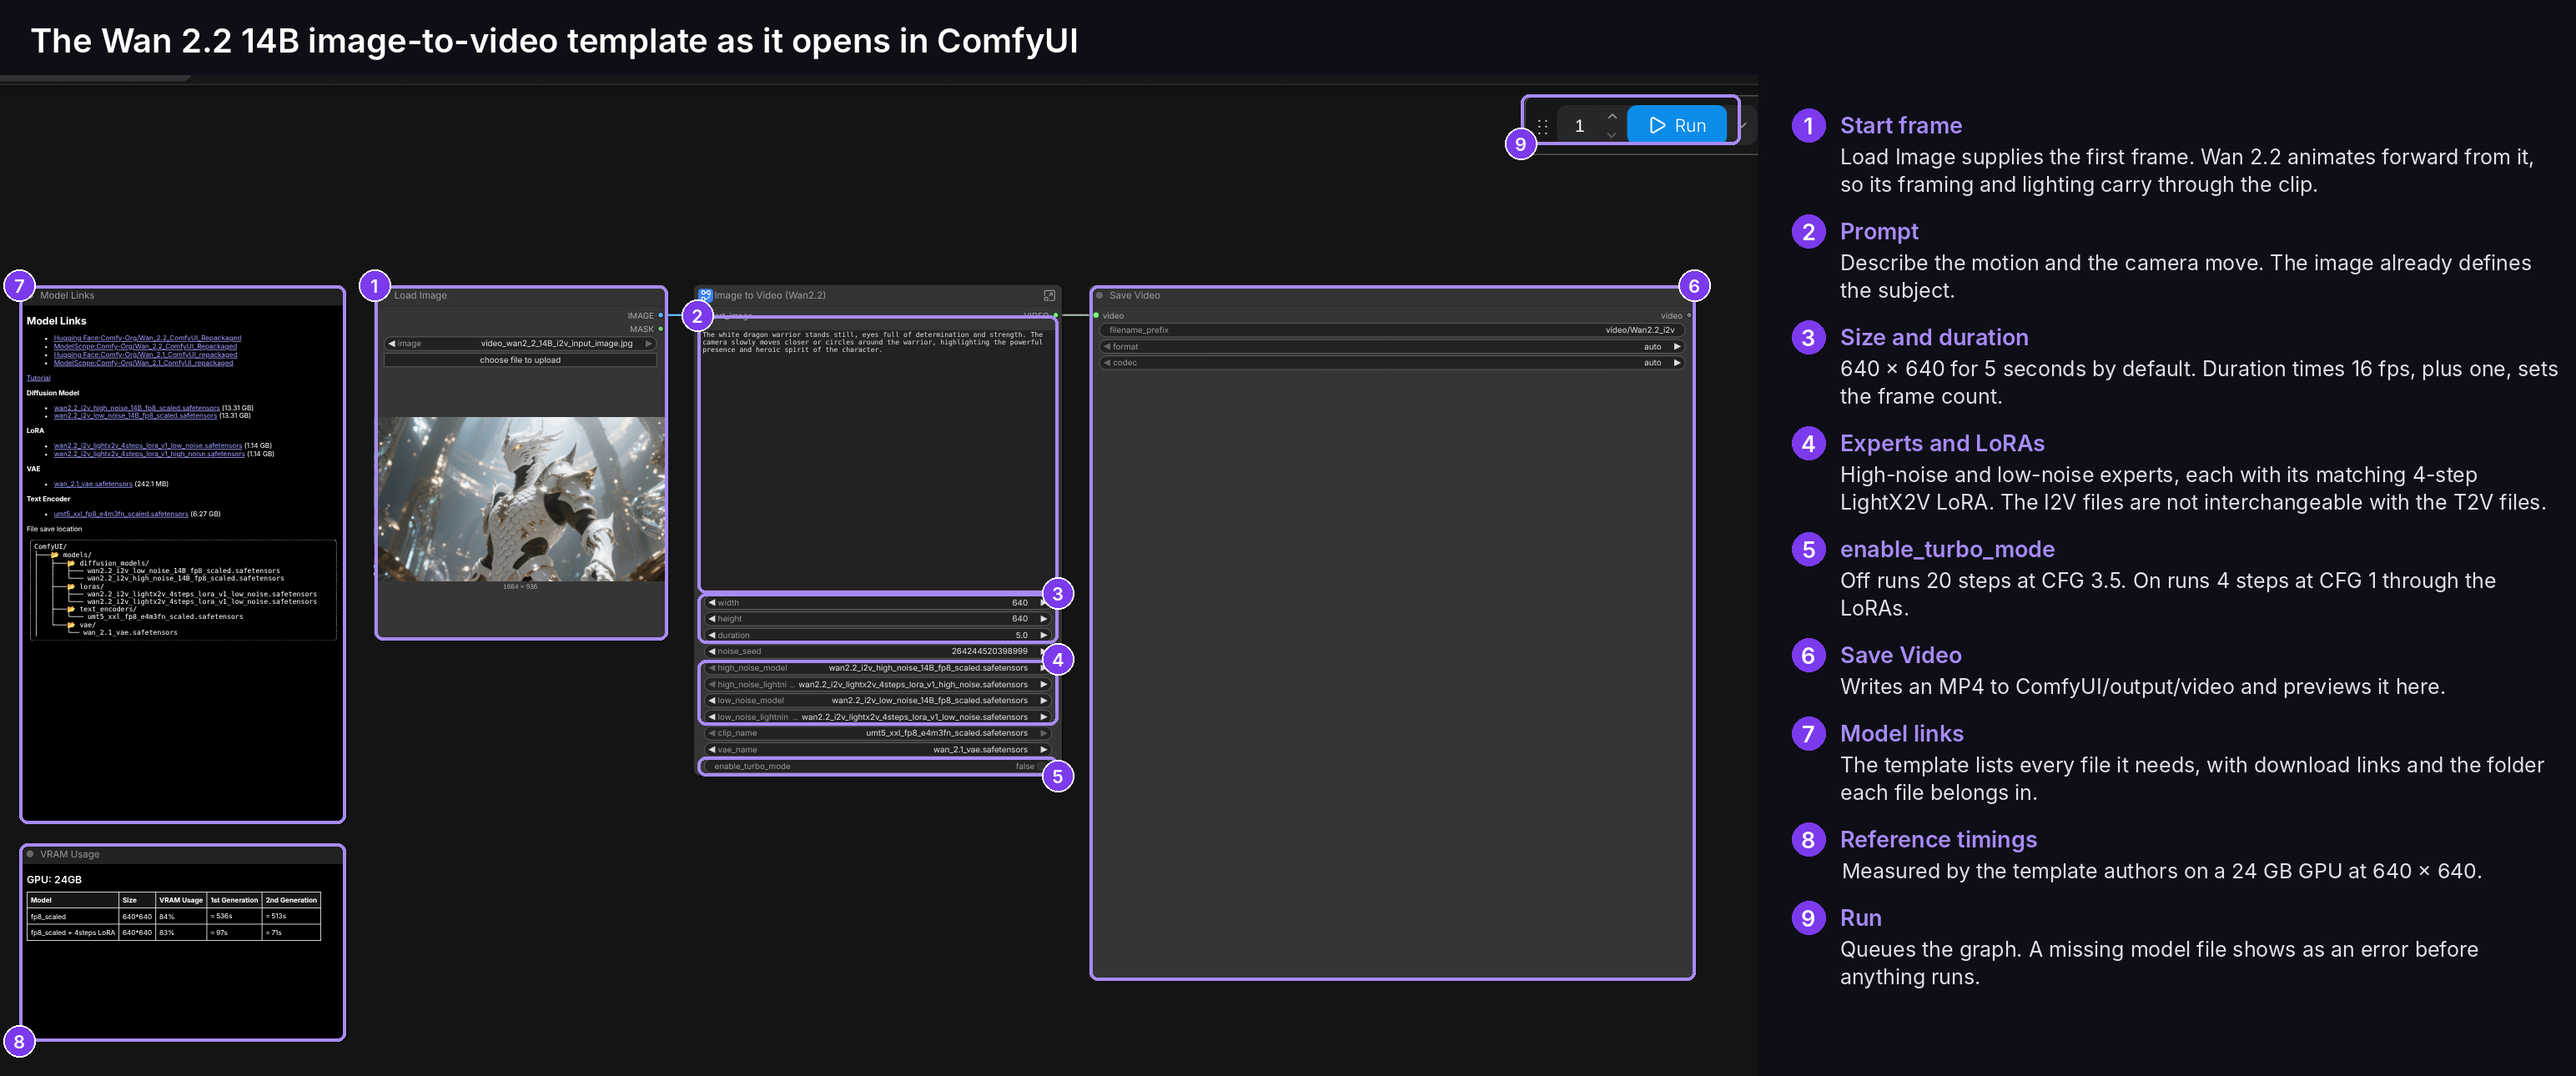
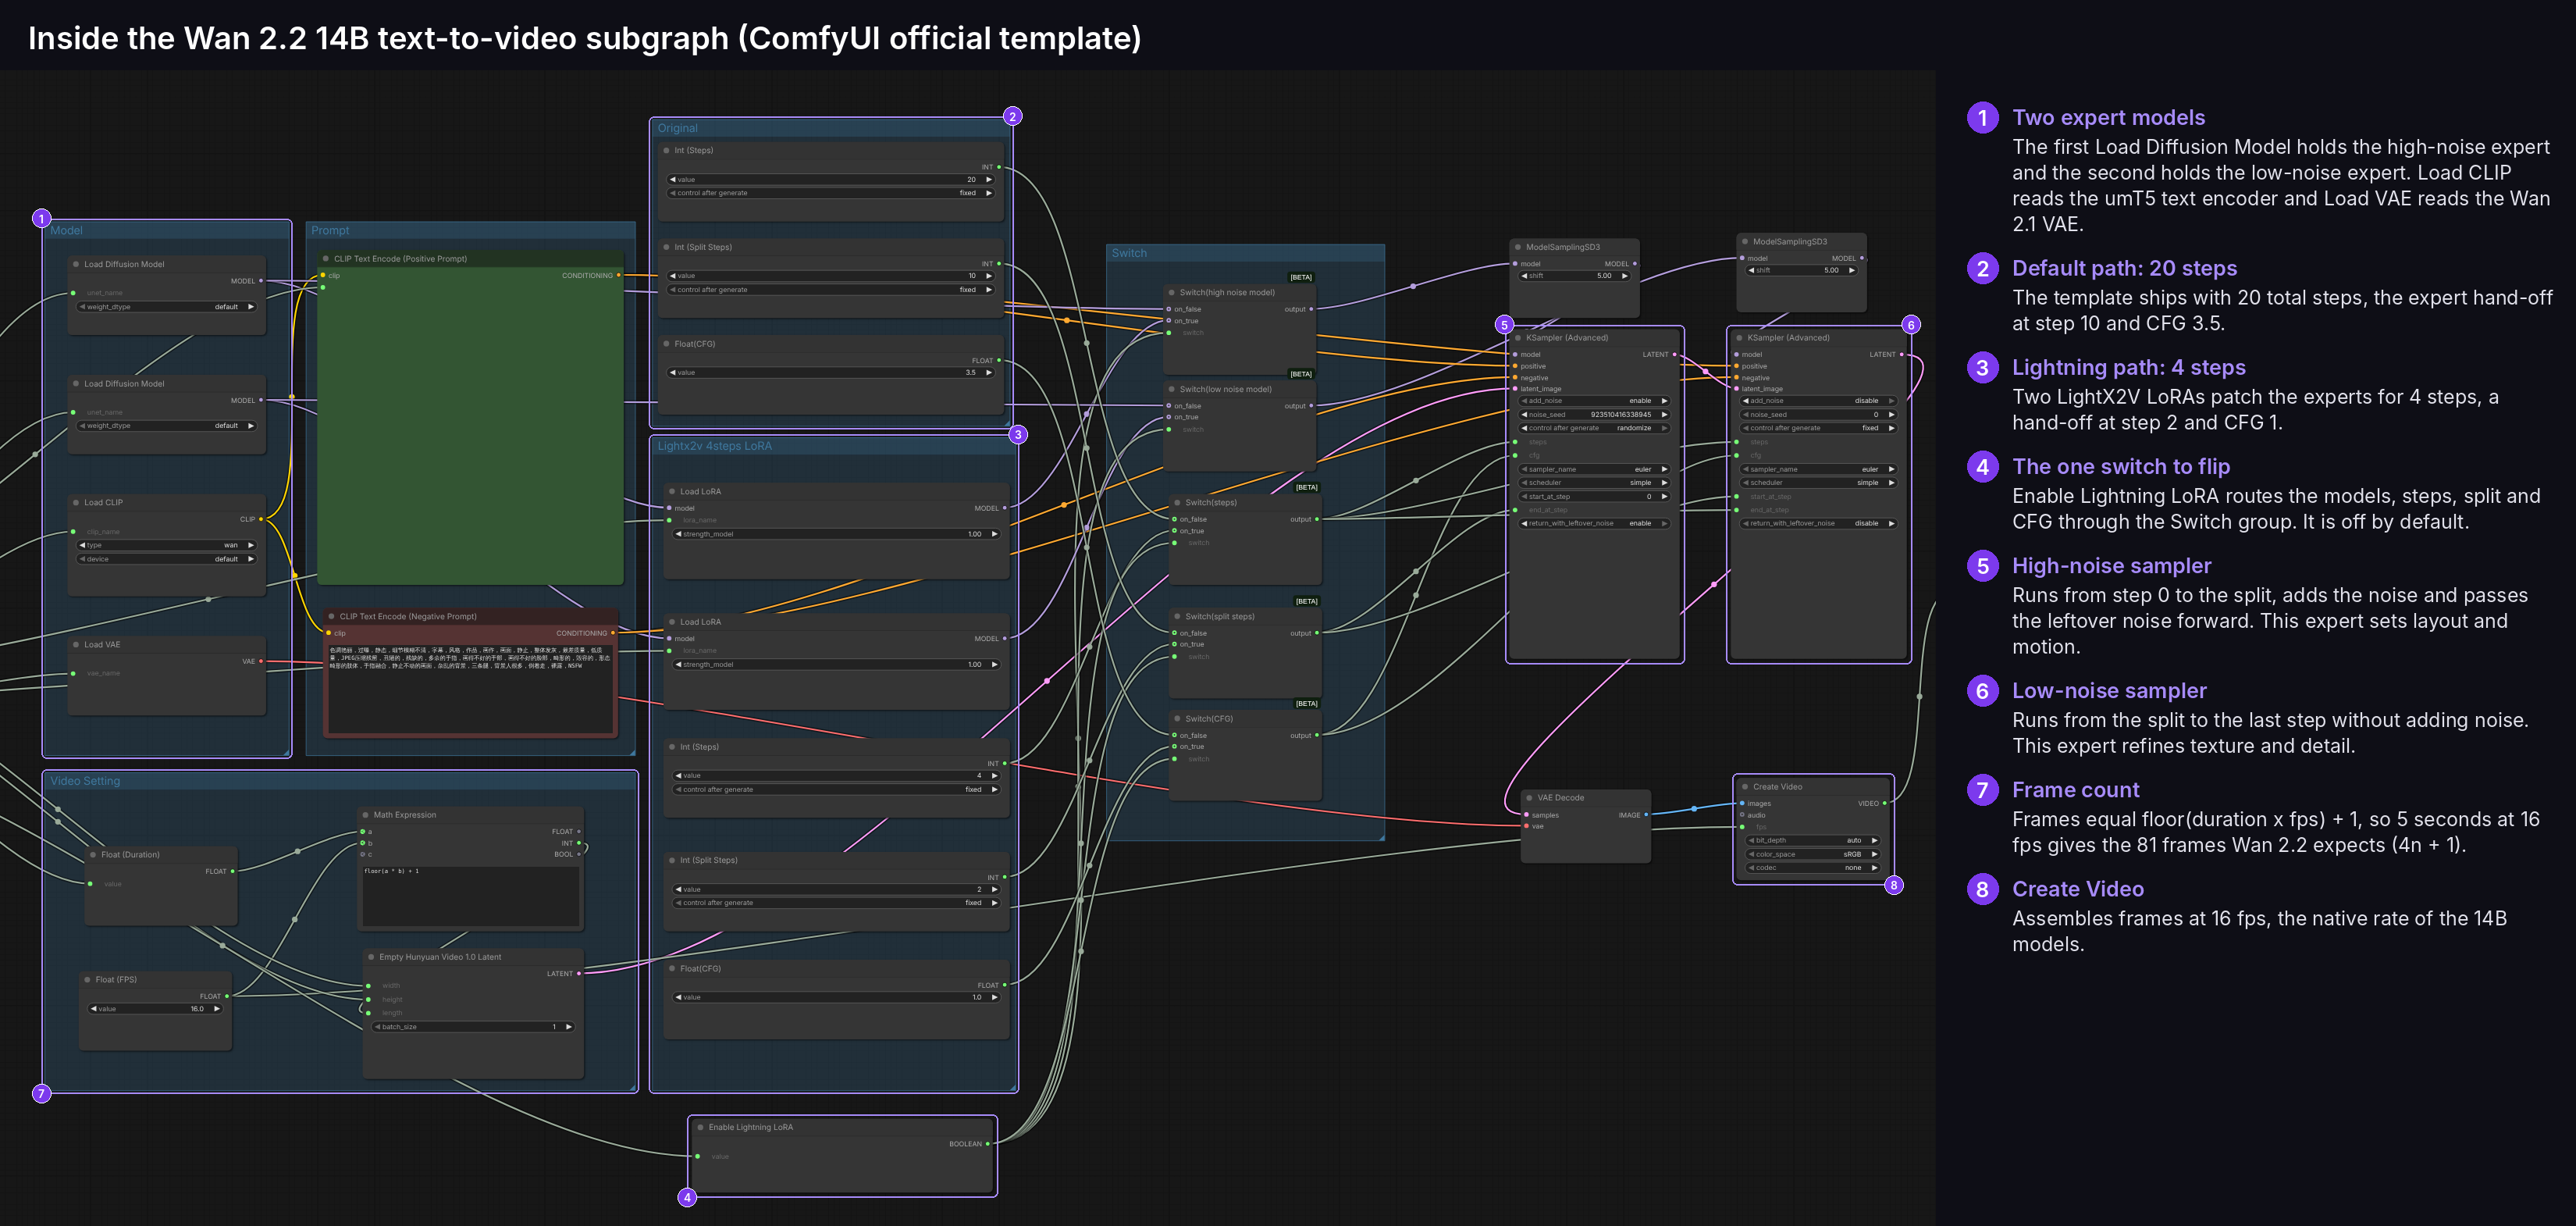
The template collapses the pipeline into a single subgraph node. Its face exposes the prompt, width, height, duration, the four model and LoRA selectors and one toggle, enable_turbo_mode, which switches between the 20-step path and the 4-step Lightning path. Double-click the node to see the pipeline inside.
6. Generate a clip and retrieve it
Write the prompt, keep 640x640 and 5 seconds for the first run, and click Run. The first run is slower because ComfyUI reads both experts from disk. Save Video writes an MP4 under /workspace/runpod-slim/ComfyUI/output/video and previews it on the canvas.
Set FILEBROWSER_PASSWORD in the template's environment variables before you deploy. The pod's proxy URL is reachable by anyone who has it, and the default credentials are public.
To download outputs, open FileBrowser on port 8080 or JupyterLab on port 8888 from the Connect panel. The FileBrowser user is admin, and the password is the value of FILEBROWSER_PASSWORD, which defaults to adminadmin12 if you did not set it.
Stop the pod when you finish a session. Stopping halts GPU billing and keeps everything on the network volume. Terminate the pod when you no longer need that machine, and the volume remains for the next one.
Settings that change the result
Steps, CFG and the Lightning LoRA
The Lightning LoRAs from the LightX2V project are distilled adapters, one for each expert, that let Wan 2.2 14B generate in 4 steps without classifier-free guidance (CFG). The template authors measured the effect on a 24 GB GPU at 640x640.
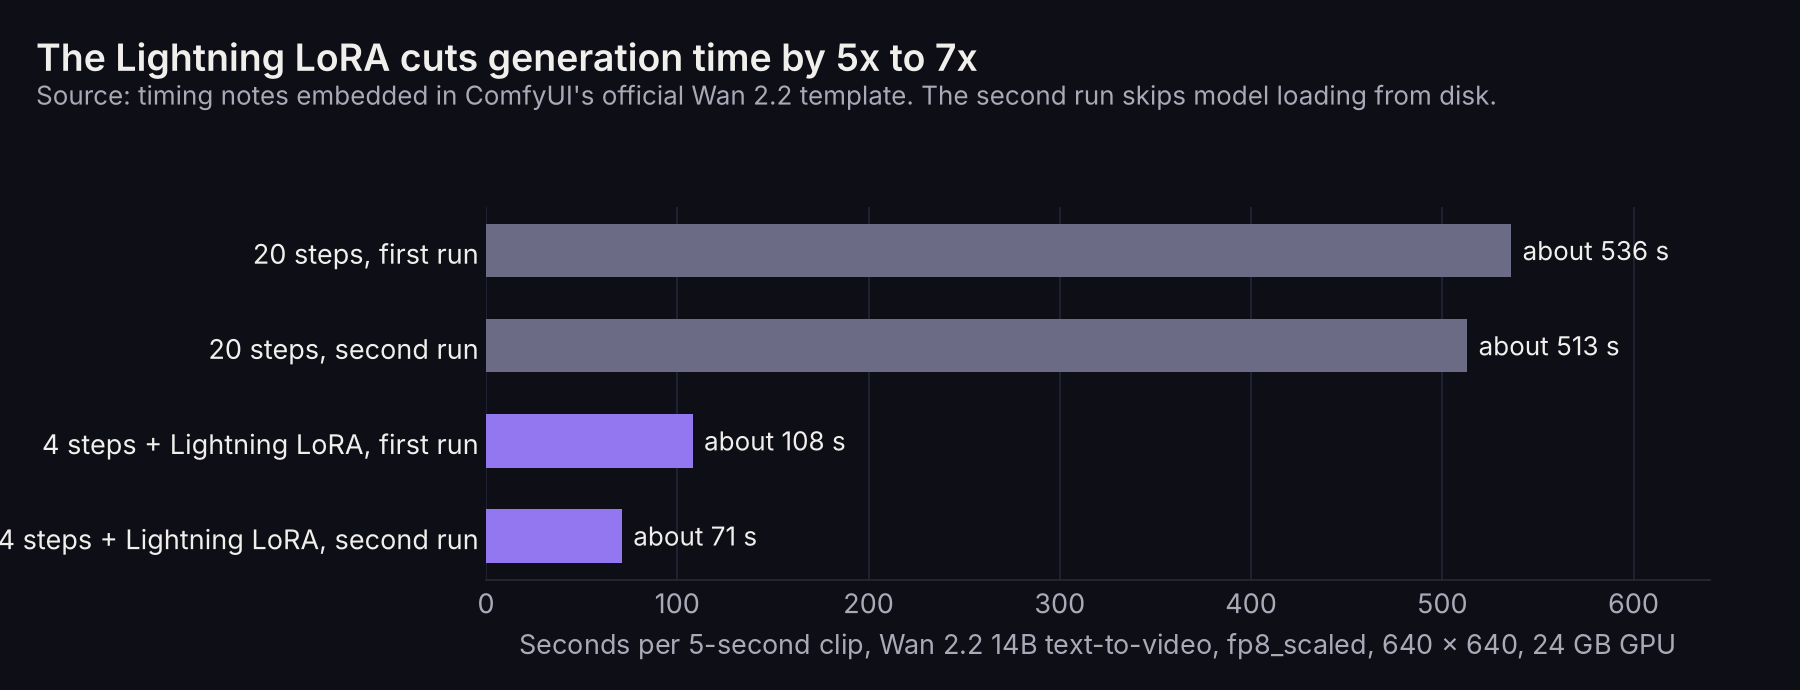
The trade is control for speed. With CFG fixed at 1 the negative prompt has no effect, and a distilled 4-step run gives you less control over prompt detail than the full 20-step run, so compare both on your own prompts. Use Lightning to explore prompts, seeds and framing, then re-render the keepers with the 20-step path. The arithmetic makes the case: at about 71 seconds a clip, the template authors' 24 GB GPU renders about 50 Lightning clips per GPU-hour, against about seven clips per hour on the 20-step path. Those clip rates are derived from the template timings, not measured on Runpod, and a slower card renders fewer.
The LightX2V project has not released a 4-step LoRA for TI2V-5B, and the 4-step LoRA was not trained for S2V. ComfyUI's documentation warns that using it with S2V causes significant loss of motion and quality.
Resolution, frame count and frame rate
Wan 2.2 14B is trained at 832x480 and 1280x720 in landscape and portrait, and the official template defaults to 640x640. Width and height should be multiples of 16. Frame counts must take the form 4n+1, and the template enforces this by computing frames as duration multiplied by frame rate, plus one, so 5 seconds at 16 fps gives 81 frames. Keep the 14B models at 16 fps and TI2V-5B at 24 fps, the rates they were trained at.
Frame count and resolution both scale the latent the model denoises. Linear activations scale with the total token count either way, but attention cost grows faster than linearly, so cutting frames and cutting resolution are not exactly interchangeable once you are near the memory limit. Measure both on your own clip. If you downloaded fp16 experts instead of the fp8_scaled files in step 4, switch to fp8 first, because it halves each expert's footprint without changing the output size.
Prompts
Alibaba's prompt guide for Wan describes a prompt as subject, scene and motion, extended with aesthetic control and style. For image-to-video, the image already fixes the subject and scene, so the prompt should describe motion and camera movement. Wan 2.2 was trained with labels for lighting, composition, lens, shot size, camera angle and color tone, so terms such as rim light, golden hour, low angle, close-up, push in, orbit and tilt up steer it reliably. Keep orbits under about 45 degrees of arc, which Alibaba's guide recommends.
Low-angle close-up of a cyclist cresting a hill at golden hour, warm rim light,
shallow depth of field. The camera pushes in slowly as dust drifts across the frame.
Run Wan 2.2 Animate in ComfyUI
Wan 2.2 Animate-14B takes a reference image of a character and a driving video of a performer. It runs in two modes. Move transfers the performer's body movement and facial expressions onto the character in your image. Mix replaces the performer in the video with your character and keeps the video's background, with a relighting LoRA that matches the character to the scene's light and color tone. Unlike the text-to-video and image-to-video models, Animate is a single 14B network rather than an expert pair, so it loads one diffusion model file.
Animate model files and custom nodes
ComfyUI's official Wan 2.2 Animate template loads these files. The fp8 model from Kijai's repository is the template default, and the bf16 file is the full-precision alternative.
| Folder under models/ | File | Size | Source |
|---|---|---|---|
| diffusion_models | Wan2_2-Animate-14B_fp8_e4m3fn_scaled_KJ.safetensors | 18.4 GB | Kijai/WanVideo_comfy_fp8_scaled |
| diffusion_models (alternative) | wan2.2_animate_14B_bf16.safetensors | 34.6 GB | Comfy-Org Wan 2.2 repackaged |
| loras | lightx2v_I2V_14B_480p_cfg_step_distill_rank64_bf16.safetensors | 0.74 GB | Kijai/WanVideo_comfy |
| loras | WanAnimate_relight_lora_fp16.safetensors | 1.44 GB | Kijai/WanVideo_comfy |
| clip_vision | clip_vision_h.safetensors | 1.26 GB | Comfy-Org Wan 2.1 repackaged |
| text_encoders | umt5_xxl_fp8_e4m3fn_scaled.safetensors | 6.74 GB | Shared with the 14B workflows |
| vae | wan_2.1_vae.safetensors | 0.25 GB | Shared with the 14B workflows |
The fp8 set totals about 28.8 GB on disk, so it fits on the same 100 GB network volume as the rest of Wan 2.2. The template also needs three custom node packs. ComfyUI-KJNodes, which provides the Points Editor, is preinstalled on the official Runpod template. Install comfyui_controlnet_aux, which provides the DWPose Estimator, and ComfyUI-segment-anything-2 through ComfyUI-Manager, then restart ComfyUI. If you deploy the HearmemanAI template instead, set download_wan_animate to true and it fetches the Animate workflows and models for you.
Generate an Animate clip
- Open Templates, search for Wan 2.2 Animate and load it. Replace the sample reference image and driving video with your own.
- Run the workflow once with the defaults. The DWPose Estimator converts the driving video into pose and face control videos, and the first run also loads the video's first frame into the Points Editor.
- For Mix, mark the performer in the Points Editor. Shift and left-click adds green points on the area to detect, and shift and right-click adds red points on areas to exclude. Segment Anything 2 turns those points into the character mask.
- For Move, disconnect the
background_videoandcharacter_maskinputs from the WanAnimateToVideo node. Bypassing those nodes is not enough, because a bypassed node still passes the driving video through. - Generate. The template renders 640x640 at 16 fps in 6 steps at CFG 1, using the Wan 2.1 LightX2V distillation LoRA. Each segment is 77 frames, about 4.8 seconds, and each copy of the Video Extend group adds another 77 frames.
Width and height must be multiples of 16, and the template defaults to a small size because Animate runs out of memory faster than the other 14B workflows. The fp8 model alone is 18.4 GB, which leaves about 5.6 GB on a 24 GB card for the CLIP vision encoder, the pose videos and activations. That estimate is derived from file sizes rather than measured, and it makes a 48 GB L40S at $1.09/hr or RTX A6000 at $0.69/hr on Secure Cloud the practical starting point for Animate. Keep driving videos short and downscaled, because preprocessing a large video takes a long time before sampling even starts.
Wan2.2-Animate-2-14B, released on August 7, 2026, replaces the separate motion extractor with end-to-end animation and adds text-driven viewpoint control. It ships as Base and Distilled versions, and the Distilled version runs in 10 steps without CFG. As of October 19, 2026, ComfyUI's official Animate template still loads Animate-14B, so check the Animate-2 model card for its ComfyUI workflow before you switch.
Use your own LoRAs
Style and character LoRAs for Wan 2.2 14B usually come in pairs, one for each expert, because each expert is a separate network. Load the high-noise LoRA on the high-noise model path and the low-noise LoRA on the low-noise path with LoraLoaderModelOnly nodes, and place the files in models/loras. LoRAs trained for Wan 2.1 were trained against a single network, so how well they transfer to either Wan 2.2 expert varies by LoRA. Test them on a fixed seed before you rely on them.
Civicomfy, preinstalled in the official Runpod template, downloads models and LoRAs from Civitai into the right ComfyUI folders from inside the interface.
Fit Wan 2.2 on a smaller card with GGUF
GGUF is a quantized weight format that ComfyUI loads through the ComfyUI-GGUF custom nodes. QuantStack publishes GGUF builds of the T2V, I2V, TI2V-5B, S2V and Animate models. The Q4_K_M build of one 14B expert is 9.7 GB, against 14.3 GB for fp8, which leaves more room for activations on a 24 GB card. Install ComfyUI-GGUF through ComfyUI-Manager, put the .gguf files in models/unet as the ComfyUI-GGUF README instructs, and replace each Load Diffusion Model node with Unet Loader (GGUF). Lower quantization levels cost detail, so compare Q4 and Q8 output on the same seed before you commit to one. Current ComfyUI treats unet as an alias of diffusion_models, so either folder works.
Run Wan 2.2 locally or on Runpod
Wan 2.2 runs locally if your GPU can hold the variant you want. TI2V-5B fits on 8 GB with ComfyUI's offloading, and Alibaba's reference script runs it on a single 24 GB GPU. The 14B models run in ComfyUI on 24 GB with fp8 weights and need system RAM to hold the idle expert. Without ComfyUI's offloading, Alibaba's script needs a GPU with at least 80 GB for the 14B models.
The local installation follows the same steps as the pod: install ComfyUI, download the files in step 4 into its models folders and load the template. Run locally when your card has the memory and you generate often enough that the hardware pays for itself. Rent a pod when you need more than 24 GB, want the faster H100 class for 720p, or generate in bursts. A Runpod pod also saves the setup itself, because the official template arrives with ComfyUI, its Manager and a matching CUDA build already installed.
Generate without setup through Public Endpoints
Public Endpoints are models that Runpod hosts and operates. You call them with an API key and pay per output, with no pod or worker to manage, and the Public Endpoints overview states that failed generations are not charged. The Wan 2.2 I2V 720p endpoint takes a prompt and a start image URL.
curl -X POST https://api.runpod.ai/v2/wan-2-2-i2v-720/runsync \
  -H "Authorization: Bearer $RUNPOD_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"input": {
        "prompt": "The camera slowly orbits the lighthouse as waves break below",
        "image": "https://example.com/lighthouse.jpg",
        "size": "1280*720",
        "duration": 5,
        "seed": -1}}'
The response returns output.video_url, which expires after seven days, and output.cost in US dollars. As of October 2026 the endpoint costs $0.06 per second of output, from $0.30 at 5 seconds to $0.90 at 15 seconds, so you can price any duration.
| Public Endpoint | Input | Price as of October 2026 |
|---|---|---|
| Wan 2.2 I2V 720p | Prompt and start image | $0.30 per 5 seconds |
Wan 2.2 I2V 720p LoRA (the endpoint path reads wan-2-2-t2v-720-lora, which is correct) | Prompt, start image and high-noise and low-noise LoRA lists | $0.35 for 5 seconds, $0.56 for 8 seconds |
| Wan 2.5 | Prompt and start image, 480p to 1080p | $0.25 to $0.75 per 5 seconds by resolution |
| Wan 2.6 T2V | Prompt, 720p or 1080p, single or multi-shot | $0.50 or $0.75 per 5 seconds by resolution |
| Wan 2.6 I2V | Prompt, start image and optional audio, 720p or 1080p, 5 to 15 seconds | $0.50 or $0.75 per 5 seconds by resolution |
Public Endpoints suit prototyping and low volume. Once you need your own workflow, a fine-tuned LoRA outside the endpoint's inputs or a cost per clip below the per-output price, move to a pod or Serverless. Current prices for every model are on the Public Endpoints page.
Serve your workflow through Runpod Serverless
Runpod Serverless runs your container as workers that start when requests arrive and scale back to zero when the queue empties. The worker-comfyui image runs any ComfyUI workflow as an API, so the Wan 2.2 workflow you tuned on a pod becomes the request body.
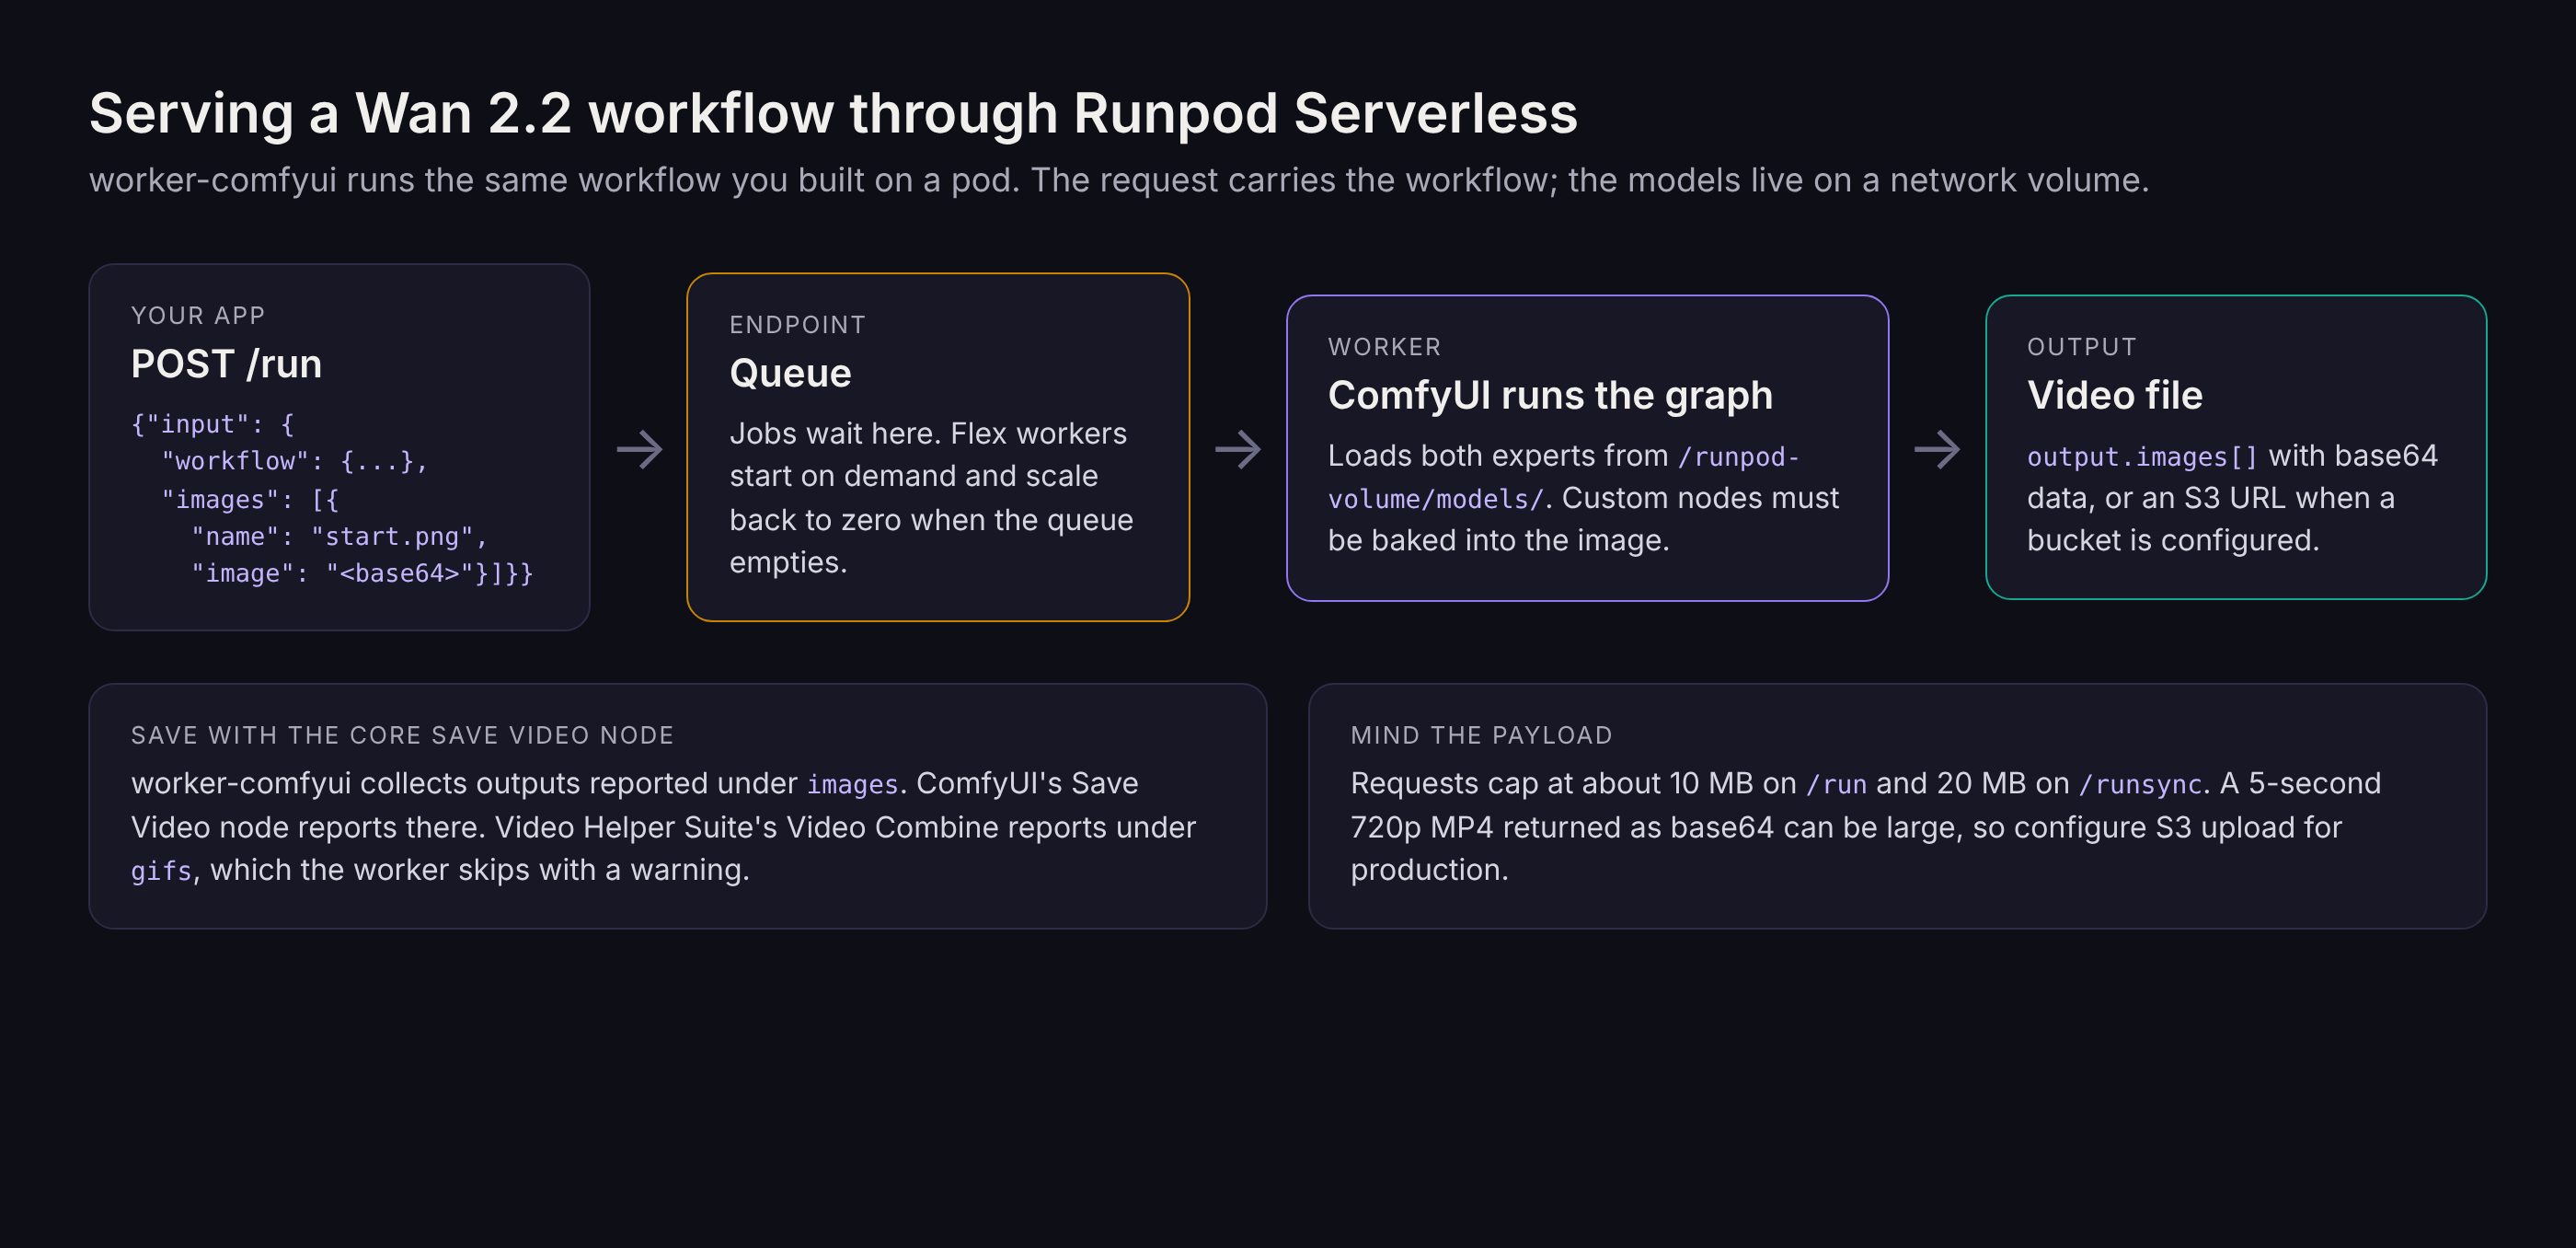
- Export the workflow from ComfyUI with Workflow, then Export (API). The worker accepts only the API format.
- Attach a network volume that holds the models. On Serverless it mounts at
/runpod-volume, and the worker's path map uses the older ComfyUI folder names: put the experts in/runpod-volume/models/unet, the text encoder inmodels/clip, and the VAE and LoRAs inmodels/vaeandmodels/loras. A volume laid out for the pod template, withdiffusion_modelsandtext_encodersunder/workspace/runpod-slim/ComfyUI/models, will not be found. - Build an image from
runpod/worker-comfyui:<version>-baseif the workflow uses custom nodes, because custom nodes cannot load from the volume. Install them in the Dockerfile withcomfy-node-install. - Send the workflow in
input.workflowand any start image as base64 ininput.images, then read the result fromoutput.images.
{
  "input": {
    "workflow": { "...": "API-format export of your Wan 2.2 workflow" },
    "images": [{ "name": "start.png", "image": "" }]
  }
}
Two details decide whether the video comes back. The worker collects outputs that ComfyUI reports under images, and the core Save Video node reports there, so keep it as the output node. Video Helper Suite's Video Combine node reports under a different key, and the worker skips it with a warning. Request payloads cap at about 10 MB on /run and 20 MB on /runsync, and results come back base64-encoded by default, so configure an S3-compatible bucket through the worker's BUCKET_ENDPOINT_URL, BUCKET_ACCESS_KEY_ID and BUCKET_SECRET_ACCESS_KEY variables before you serve 720p clips.
Flex workers scale to zero, so an idle endpoint costs nothing, and FlashBoot delivers sub-200ms cold starts by reviving a worker's retained state. A worker starting fresh still has to read both 14 GB experts from the volume before its first job, so the first request after a long idle period waits for that load. Keep a minimum of one active worker only if your application cannot tolerate that delay, because an active worker bills around the clock. On the 24 GB card group that covers the L4 and RTX A5000, Flex workers run $0.75/hr. The 14B workflow at 720p needs a 48 GB or 80 GB group, which the Serverless pricing docs list.
Fix common Wan 2.2 problems
| Symptom | Likely cause | Fix |
|---|---|---|
| Model files show as missing when the template loads | Files are in the wrong folder or under a different name | Compare names against the template's model note and place them under /workspace/runpod-slim/ComfyUI/models |
| CUDA out-of-memory at the start of sampling | fp16 experts, or resolution and frame count too high for the card | Switch to fp8_scaled or GGUF experts, cut frames or resolution, or move to a 48 GB card |
| Bad Gateway when opening port 8188 | ComfyUI is still copying or starting | Watch the logs for the startup-complete line, then refresh |
| Image-to-video errors or ignores the start image | The text-to-video experts are loaded in the image-to-video workflow | Load the wan2.2_i2v expert pair and its matching LoRAs |
| Good motion but soft, smeared detail | The low-noise expert gets too few steps | Move the split step earlier, or render the final clip on the 20-step path |
| Negative prompt has no effect | The Lightning path runs at CFG 1 | Turn off enable_turbo_mode for that render |
| HearmemanAI template opens with blank model dropdowns | No download flag was set before deploying, so no models were fetched | Set download_wan22 to true under Edit Template and redeploy |
| Serverless worker cannot find the Wan models | Models are in diffusion_models or text_encoders, which the worker does not map | Move experts to models/unet and the text encoder to models/clip on the volume |
| Serverless job succeeds with no video | The output node is Video Combine, not Save Video | Save with the core Save Video node |
| Models gone after terminating the pod | Files were on the pod's volume disk, not a network volume | Attach a network volume at deployment and keep models on it |
Get started
Pick the path that matches Figure 1:
- To try Wan 2.2 with no setup, open the Wan 2.2 I2V 720p Public Endpoint in the Runpod console and send a prompt and a start image.
- To build a workflow, create a 100 GB network volume on Secure Cloud, deploy the official ComfyUI template on an RTX A5000 with the volume attached, download the files from step 4 and load the Wan 2.2 template.
- To serve the workflow, export it in API format and deploy worker-comfyui on a Serverless endpoint with the same volume attached.
The Runpod ComfyUI tutorial and network volume documentation cover the platform steps in more detail.
FAQs
What is Wan 2.2?
Wan 2.2 is Alibaba's open-weight video generation model family, released in July 2025 under the Apache 2.0 license. It includes 14B mixture-of-experts models for text-to-video and image-to-video, a 5B model that handles both, and later speech-to-video and character animation models.
What GPU do I need for Wan 2.2?
TI2V-5B fits on 8 GB with ComfyUI's offloading and runs comfortably on 24 GB. The 14B models need 24 GB with fp8 weights at 640x640 or 480p, 48 GB for fp8 at 720p or fp16 weights at 640x640, and 80 GB for 720p without offloading. An RTX A5000 on Runpod Secure Cloud costs $0.27/hr.
How much VRAM does Wan 2.2 14B use?
One 14B expert is 14.3 GB in fp8 and 28.6 GB in fp16, and each model has two experts. ComfyUI keeps only the active expert on the GPU when memory is tight, so a 24 GB card runs the fp8 pair at 640x640 at about 83% to 89% VRAM use according to the template authors' measurements.
Can I run Wan 2.2 locally?
Yes, if your GPU holds the variant you choose. Install ComfyUI, download the model files into its models folders and load the Wan 2.2 template. TI2V-5B runs on 8 GB to 24 GB cards, and the 14B models need 24 GB with fp8 weights plus enough system RAM for the idle expert.
How long does Wan 2.2 take to generate a video?
On the template authors' 24 GB GPU at 640x640, the 14B template takes about 513 seconds for a 5-second clip at 20 steps and about 71 seconds with the 4-step Lightning LoRA, after the first run. Alibaba's benchmark puts a 720p clip at 17.4 minutes on one H100 with its reference script.
What is the Wan 2.2 Lightning LoRA?
It is a pair of distilled LoRAs from the LightX2V project, one per expert, that let Wan 2.2 14B generate in 4 steps without classifier-free guidance. The official ComfyUI templates include it behind the enable_turbo_mode toggle. It cuts generation time by 5x to 7x, and with CFG at 1 the negative prompt stops having an effect.
What is the difference between Wan 2.1 and Wan 2.2?
Wan 2.2 splits the 14B model into a high-noise and a low-noise expert, trains on 65.6% more images and 83.2% more videos than Wan 2.1, and adds aesthetic labels for lighting, composition and color. The 14B models reuse the Wan 2.1 VAE, while the new 5B model uses a higher-compression Wan 2.2 VAE. Wan 2.2 14B workflows need two model loaders and two samplers, so Wan 2.1 workflows do not load it unchanged.
What is Wan 2.2 Animate?
Wan 2.2 Animate-14B, released in September 2025, animates a character image with the movement and expressions of a performer in a driving video, or replaces the performer with your character. ComfyUI ships an official Animate template that needs about 28.8 GB of model files with fp8 weights and a 48 GB GPU in practice. Animate-2-14B followed in August 2026 with end-to-end animation and text-driven viewpoint control.
Is Wan 2.5 or Wan 2.6 available as open weights?
No. As of October 2026, Wan 2.5, 2.6 and 2.7 are available only through Alibaba's Model Studio API, and Wan 2.2 is the newest open-weight Wan release. Runpod offers Wan 2.5 and Wan 2.6 as Public Endpoints.
Is Wan 2.2 or Wan 2.5 better?
They answer different needs. Wan 2.2 has open weights, so you run it on your own GPU with your own LoRAs, workflow and settings, and you pay only for GPU time. Wan 2.5 is API-only: on Runpod's Public Endpoint it renders 480p to 1080p clips of 5 or 10 seconds per call with nothing to deploy, and you pay per output. Choose Wan 2.2 for control and volume, and Wan 2.5 for higher resolution without managing a pod.
Is Wan 2.2 free?
The model weights are free. Wan 2.2 is released under the Apache 2.0 license, which permits commercial use. The GPU that runs it is not free: on Runpod you pay per second for a pod, or per 5 seconds of output on a Public Endpoint.
How much does it cost to run Wan 2.2 on Runpod?
On a pod you pay for GPU time per second, such as $0.27/hr for an RTX A5000 on Secure Cloud, plus network volume storage at the standard tier's $0.07/GB/month for the first 1 TB as of October 2026. The Wan 2.2 I2V 720p Public Endpoint costs $0.30 per 5 seconds of output.
Where does ComfyUI save Wan 2.2 videos on Runpod?
On the official Runpod ComfyUI template, Save Video writes MP4 files under /workspace/runpod-slim/ComfyUI/output/video. Download them through FileBrowser on port 8080 or JupyterLab on port 8888.
What is the Runpod FileBrowser login?
On the official ComfyUI template, the FileBrowser user is admin and the password is the value of the FILEBROWSER_PASSWORD environment variable, which defaults to adminadmin12. Change it before you deploy.
Can I use Wan 2.2 as an API?
Yes. For hosted models with no setup, call the Wan 2.2 Public Endpoints. For your own workflow, export it from ComfyUI in API format and deploy worker-comfyui on Runpod Serverless, where workers scale to zero when idle.