The NVIDIA RTX A5000 is a 24 GB Ampere workstation GPU with 768 GB/s of memory bandwidth and 8,192 CUDA cores. It serves 8B models in BF16, 14B in INT8 and 32B in 4-bit, and fine-tunes 8B models with LoRA or QLoRA. It has no FP8 Tensor Cores. On Runpod it rents from {{gpu:rtx-a5000}}/hr.
On Runpod, the AI developer cloud, an RTX A5000 Pod on Secure Cloud is billed by the second, which suits development, fine-tuning and steady serving. For inference that should scale to zero, the same card is available through the 24 GB Serverless pool. The A5000 cannot fully fine-tune an 8B model, and at October 20, 2026 rates it had the lowest cost per generated token of any 24 GB or 48 GB card in the comparison below.
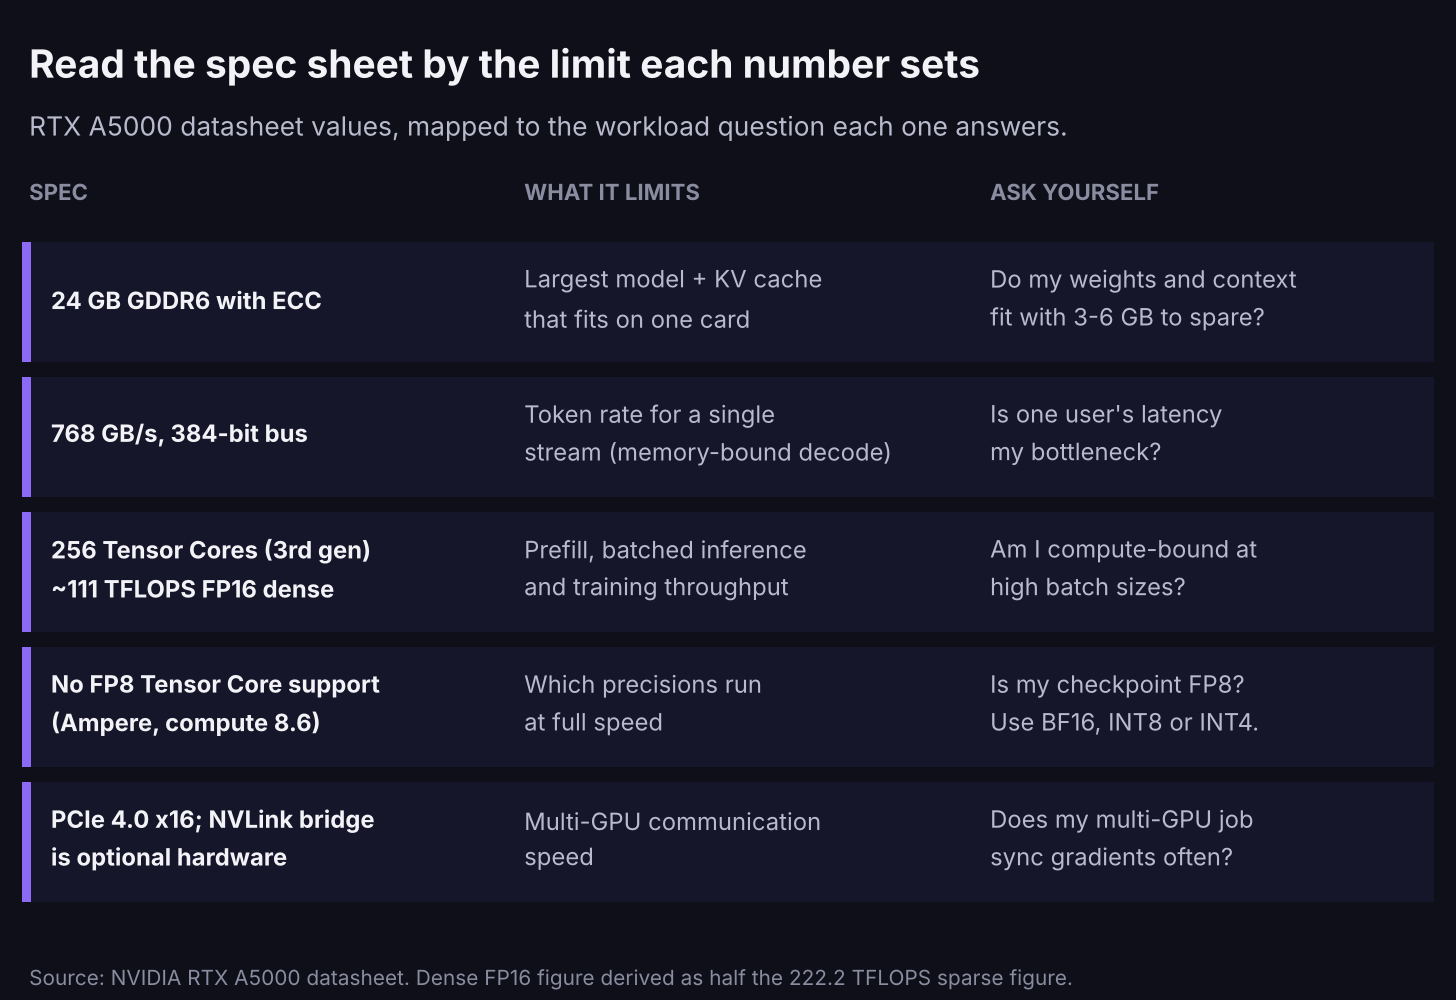
Most spec pages treat the A5000 as a smaller A6000 and stop there. That framing misses the useful part. The A5000 has exactly the same 768 GB/s memory bandwidth as the RTX A6000, so for single-user LLM decode it streams weights at the same speed. What you give up is half the memory. The decision you are making with this card is almost always a memory decision, and the sections below show how to make it with arithmetic rather than guesswork.
RTX A5000 specs at a glance
| Specification | RTX A5000 |
|---|---|
| Architecture and GPU | NVIDIA Ampere, GA102, compute capability 8.6 |
| CUDA cores | 8,192 |
| Tensor Cores | 256, third generation (FP16, BF16, TF32, INT8; no FP8) |
| RT Cores | 64, second generation |
| GPU memory | 24 GB GDDR6 with ECC, 384-bit interface |
| Memory bandwidth | 768 GB/s |
| FP32 performance | 27.8 TFLOPS |
| Tensor performance | 222.2 TFLOPS with sparsity; about 111 TFLOPS dense FP16 (derived) |
| RT Core performance | 54.2 TFLOPS |
| Total board power | 230 W |
| System interface | PCIe 4.0 x16 |
| NVLink | Optional two-way bridge, 112.5 GB/s bidirectional |
| Video engines | 1 encoder (NVENC), 2 decoders (NVDEC) with AV1 decode |
| Display outputs | 4x DisplayPort 1.4a |
| Form factor | Dual slot, full height, 4.4 in. x 10.5 in. |
| Virtualization | NVIDIA RTX Virtual Workstation, vPC and vApps |
Source: NVIDIA RTX A5000 datasheet; compute capability from NVIDIA's CUDA GPU list. The dense FP16 figure is half the published sparse figure.
The A5000 launched in 2021 as the successor to the Quadro RTX 5000, and NVIDIA dropped the Quadro name with this generation. Searches for "Quadro A5000" land on the same card.
Memory bandwidth and VRAM decide most AI workloads
Two numbers do most of the work when you size a GPU for language models. VRAM decides whether the model and its working memory fit at all. Memory bandwidth decides how fast the GPU can stream those weights through the cores, which sets the token rate for a single user. Core counts and TFLOPS matter once you batch many requests together or train, because that is when the GPU becomes compute-bound instead of memory-bound.
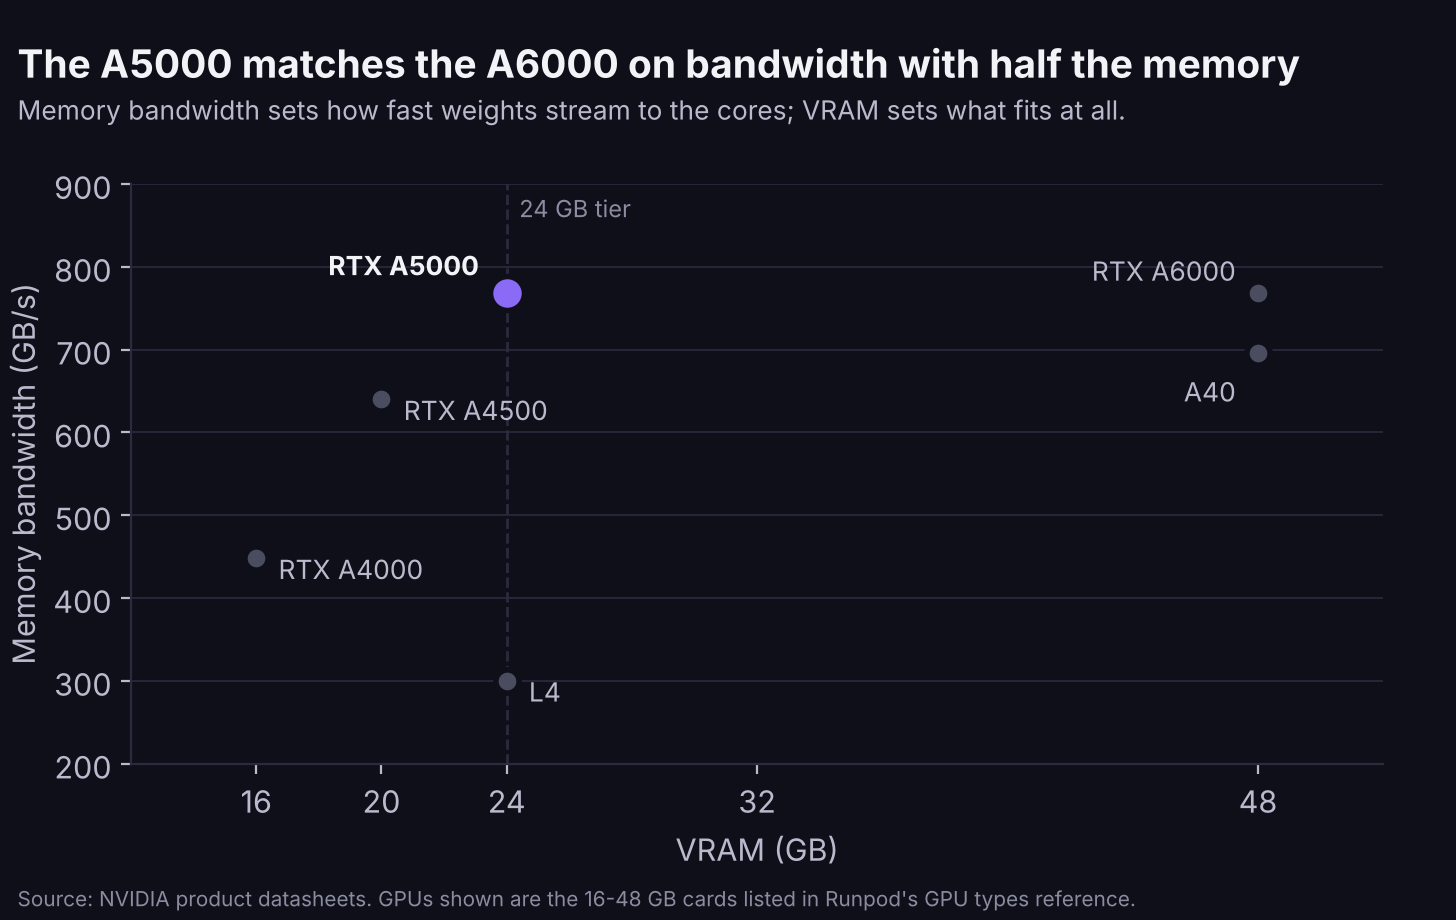
The chart also explains a common surprise. The L4 has the same 24 GB as the A5000 and a newer architecture, but at 300 GB/s it streams weights at less than half the A5000's rate. It draws 72 W against the A5000's 230 W, which is the trade the L4 makes.
How much model fits in 24 GB
Start every sizing decision with the weight math. Weight memory equals the parameter count times the bytes per parameter: 2 bytes for FP16 or BF16, 1 byte for INT8 and roughly half a byte for 4-bit formats such as AWQ or GPTQ.
weight_GB ≈ params_in_billions × bytes_per_param
8B  × 2.0 (BF16) = 16 GB
14B × 1.0 (INT8) = 14 GB
32B × 0.5 (INT4) = 16 GB
70B × 0.5 (INT4) = 35 GB
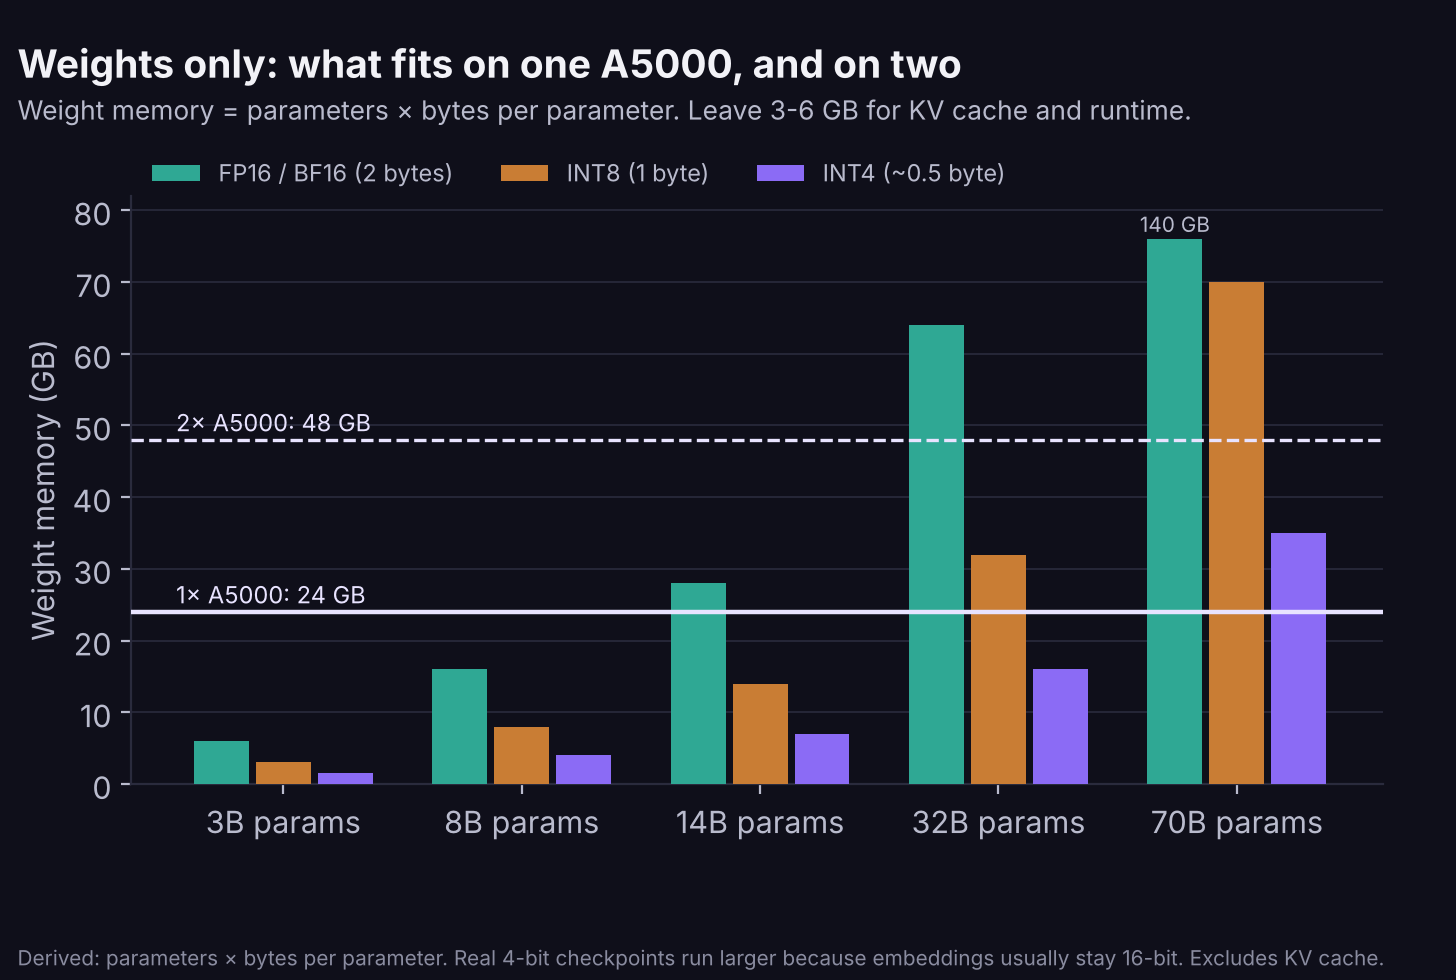
Treat roughly 20 GB as your practical weight budget on one A5000. Real 4-bit checkpoints come in larger than the half-byte estimate because most quantization schemes leave the embedding and output layers in 16-bit, which adds almost 2 GB on a model with a large vocabulary. A 4-bit AWQ build of Llama 3.1 8B is 5.7 GB on disk, not the 4 GB the half-byte rule predicts.
The KV cache is the part people forget
Every token in every active sequence keeps a key and a value vector for every layer. That cache grows with context length and with the number of concurrent requests, and it competes with the weights for the same 24 GB.
kv_bytes_per_token = 2 (K and V) × layers × kv_heads × head_dim × bytes_per_value

Llama 3.1 8B: 2 × 32 × 8 × 128 × 2 bytes = 131,072 bytes = 128 KiB per token
8,192-token sequence: 128 KiB × 8,192 ≈ 1 GiB
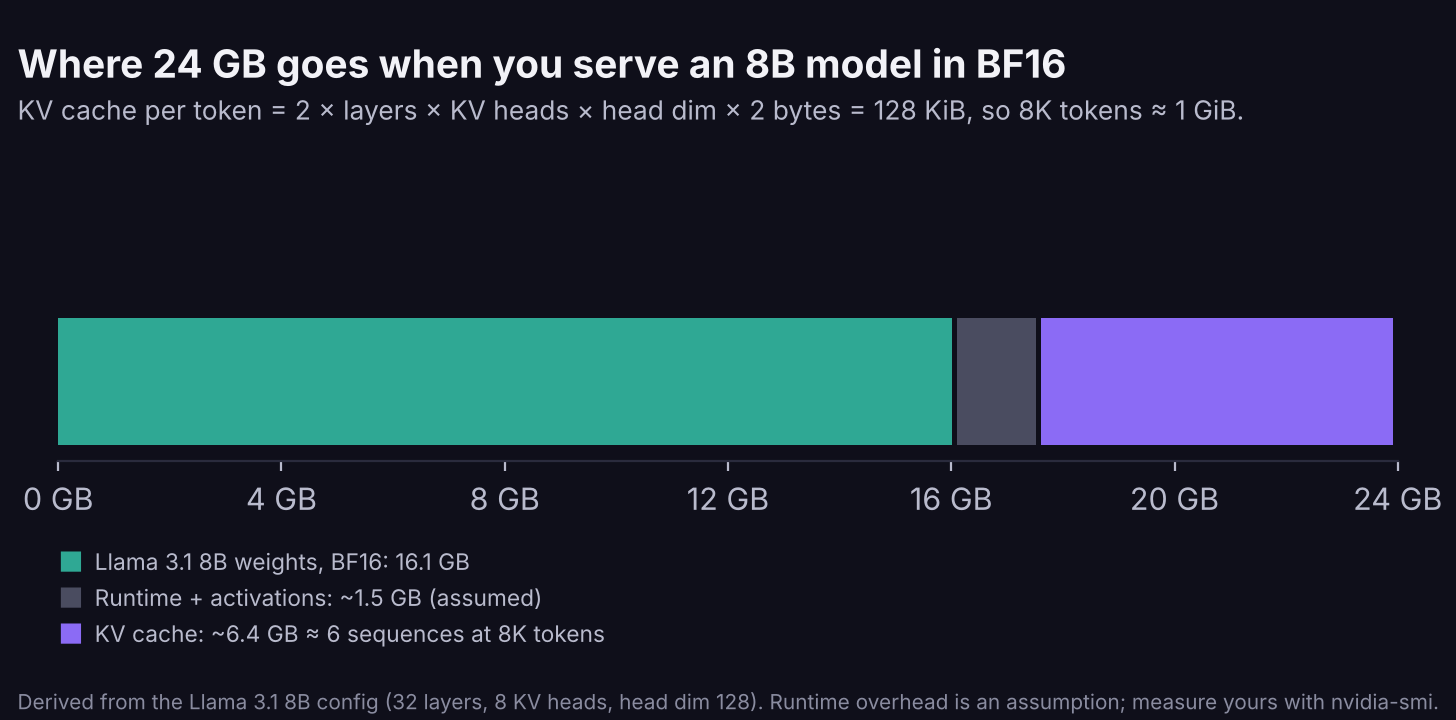
The worked example shows the trade in concrete terms. Serving Llama 3.1 8B in BF16 on one A5000 leaves about 6 GB of KV cache, which is enough for a handful of concurrent long-context users or many short chats. If you need more concurrency or longer context, quantize the weights to INT8 or 4-bit and give the reclaimed memory to the cache. Inference engines such as vLLM allocate the cache from whatever memory remains after the weights load, so lowering --max-model-len or raising --gpu-memory-utilization changes how many sequences fit. On a Runpod RTX A5000 Pod, vLLM 0.32.0 with --gpu-memory-utilization 0.90 reserved 4.54 GiB of KV cache, or 37,200 tokens: about four and a half 8K sequences. The same settings with the 4-bit AWQ build held 115,760 tokens.
Two A5000s hold a 70B model at 4-bit
The half-byte rule puts a 70B model at 35 GB in 4-bit, but the published 4-bit AWQ build of Llama 3.1 70B is 39.8 GB, which no 24 GB card holds. Split across two A5000s with tensor parallelism, it leaves about 8 GB for KV cache and runtime overhead. Each token of context in that model takes 320 KiB of KV cache (80 layers, 8 KV heads, head dimension 128), so an 8K-token sequence needs about 2.5 GiB and the pair holds only a few long conversations at once. Tensor parallelism exchanges activations between GPUs on every layer, so the interconnect matters. An NVLink bridge carries 112.5 GB/s between a pair of A5000s; without one, traffic crosses PCIe 4.0. Check what your Pod actually has before you plan around it:
nvidia-smi topo -m
An NV# entry between GPU0 and GPU1 means NVLink is present. PHB, PXB or SYS means the cards talk over PCIe, which still works for inference but costs throughput. If you need 48 GB on a single device, the RTX A6000 or A40 avoids the split entirely.
Inference speed is a bandwidth problem
When one user is generating tokens, the GPU reads every weight once per token. That makes single-stream decode memory-bound, and it gives you a ceiling you can compute before you rent anything:
max_tokens_per_second (batch 1) ≈ memory_bandwidth ÷ weight_bytes

RTX A5000, Llama 3.1 8B in BF16:    768 GB/s ÷ 16.1 GB ≈ 48 tokens/s
RTX A5000, same model in 4-bit AWQ: 768 GB/s ÷ 5.7 GB ≈ 134 tokens/s
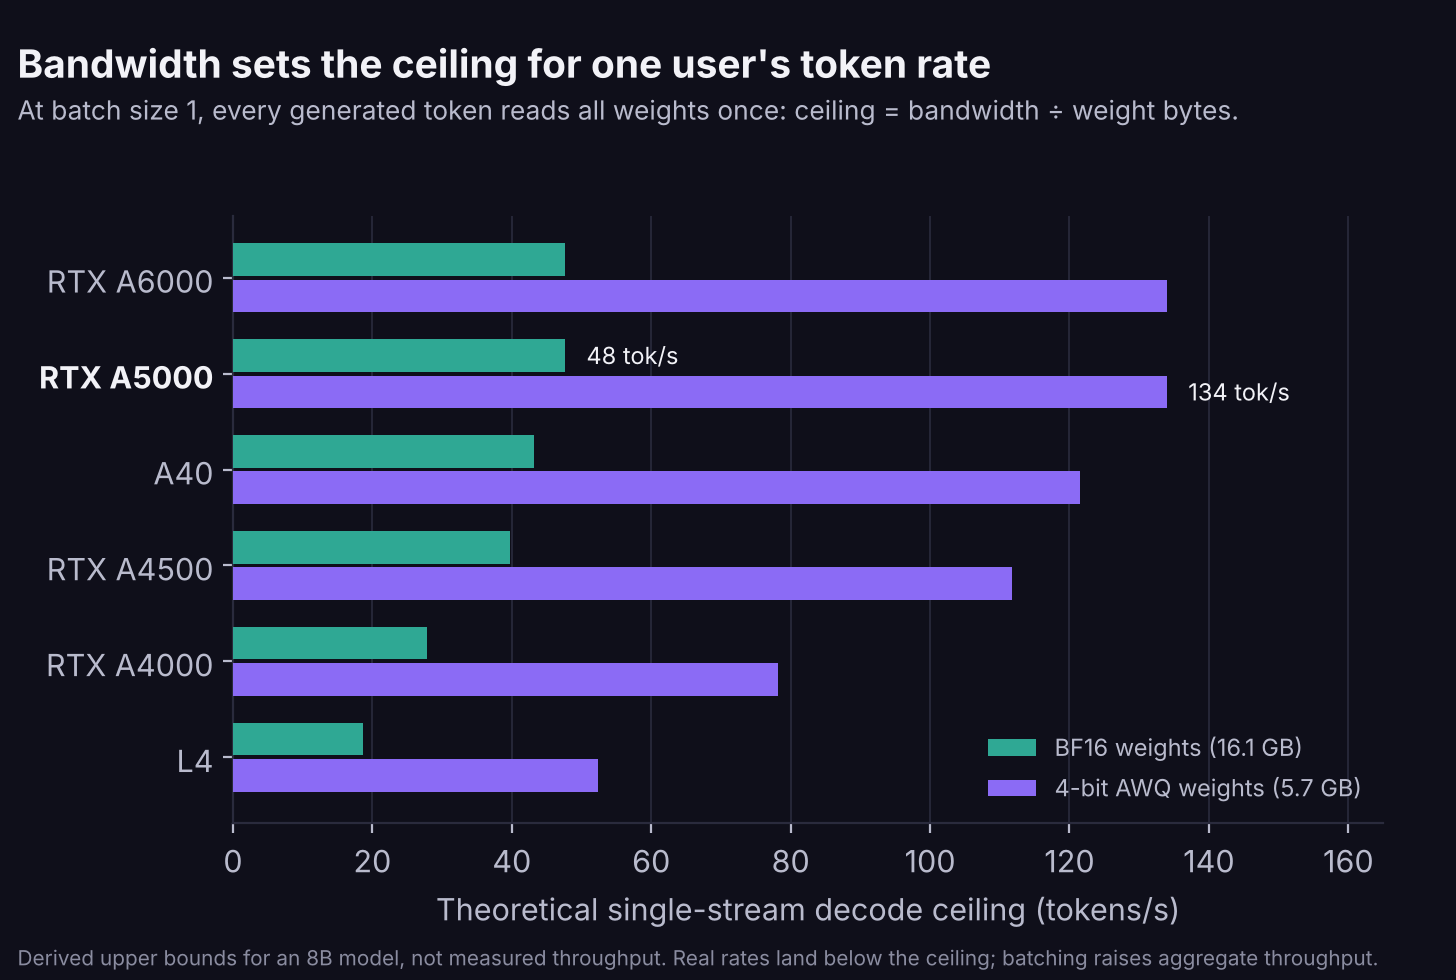
Real single-stream throughput lands below this ceiling because of kernel overhead, attention over the KV cache and sampling. On a Runpod RTX A5000 Pod with vLLM 0.32.0, Llama 3.1 8B generated 42 tokens per second in BF16 and 119 in 4-bit AWQ for a single user, about 88% of each ceiling. The ranking holds, and the chart answers two practical questions. First, quantizing to 4-bit roughly triples the single-user token rate on the same card. Second, the A5000 and A6000 decode at the same speed for any model that fits on both, so pay for the A6000 only when you need its memory.
Batching changes the picture. Serving many requests at once reuses each weight read across every sequence in the batch, so aggregate throughput climbs until the Tensor Cores saturate. That is where the A5000's roughly 111 dense FP16 TFLOPS start to matter, and where a continuous-batching engine such as vLLM earns its place.
Cost per token favors the A5000
A decode ceiling and an hourly rate together give you a cost floor per generated token. Divide the hourly rate by the number of tokens the card can produce in an hour at its ceiling:
cost_per_million_tokens = hourly_rate ÷ (tokens_per_second × 3,600 ÷ 1,000,000)

RTX A5000, Llama 3.1 8B in BF16: 47.7 tok/s × 3,600 = 171,720 tokens per hour

The result runs against the usual instinct to rent the bigger card. The RTX A6000 decodes at the same speed as the A5000 for any model that fits in 24 GB, but at October 20, 2026 Secure Cloud rates each BF16 token cost about 2.2x as much on the A6000. The L4 costs more per hour than the A5000 and streams weights at less than half the speed, so it lands at more than 5x the A5000's cost per token. When single-user latency at the A5000's ceiling is acceptable, the A5000 is the cheapest way on Runpod to generate tokens from a model that fits in 24 GB.
Treat these figures as floors. Real single-stream throughput falls below the ceiling, which raises the cost per token. Batching works in the other direction: an engine serving 16 concurrent requests reuses each weight read 16 times, so aggregate tokens per hour rise and cost per token falls well below the batch-1 floor. Measure your own workload before you commit to a fleet size, and recompute with the live rates in the table below.
Fine-tuning on an A5000 means LoRA or QLoRA
Full fine-tuning is the folklore that sinks most 24 GB plans. Mixed-precision training with the Adam optimizer holds about 16 bytes per parameter: 2 for BF16 weights, 2 for gradients, 4 for an FP32 master copy and 8 for Adam's two moment estimates. For an 8B model that is about 128 GB before a single activation is stored.
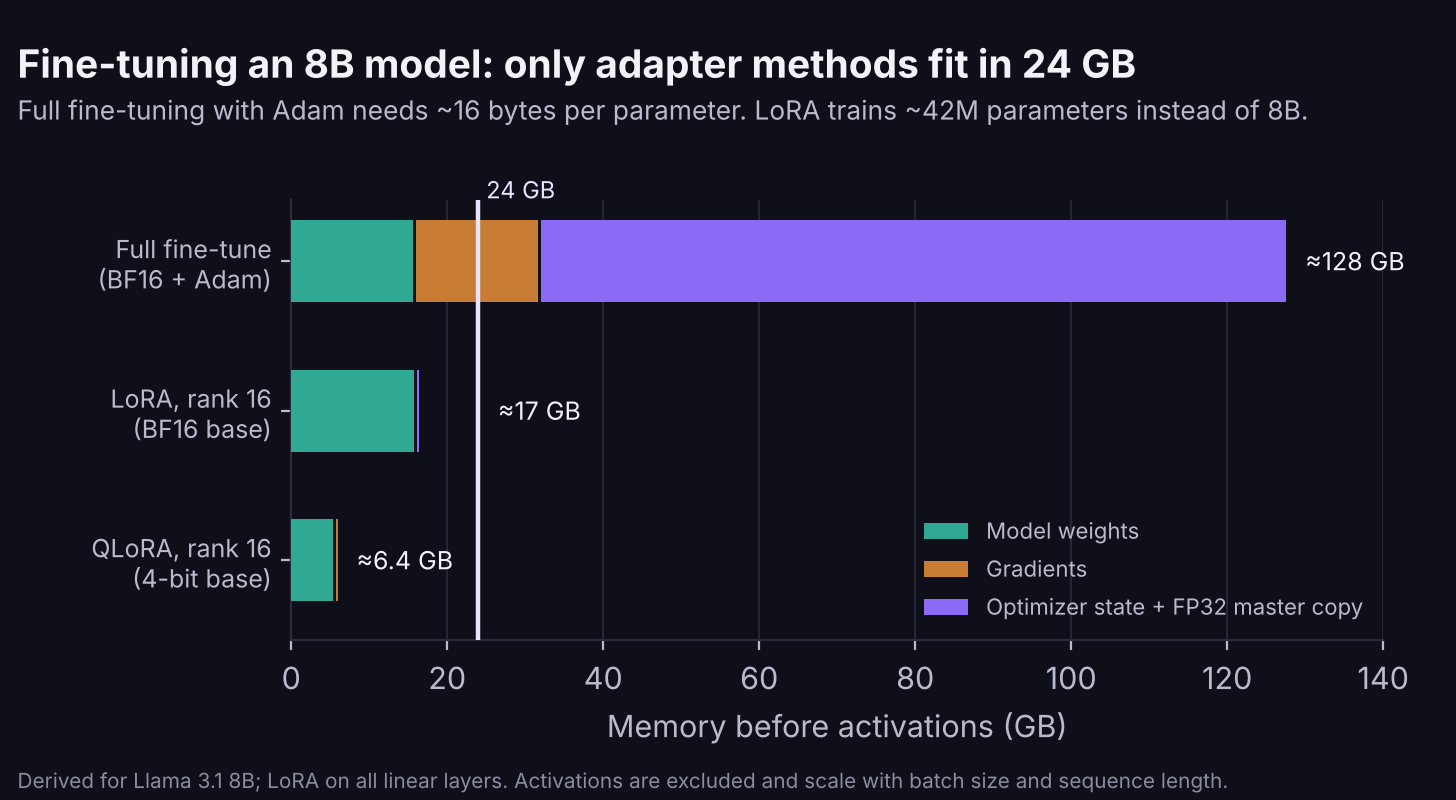
LoRA freezes the base weights and trains low-rank adapter matrices instead. At rank 16 on every linear layer of Llama 3.1 8B, that is about 42 million trainable parameters, which carry well under 1 GB of gradient and optimizer state. The base model in BF16 still takes about 16 GB, which leaves roughly 6-7 GB for activations once the runtime loads. Use gradient checkpointing and a small per-device batch with gradient accumulation to stay inside it.
QLoRA loads the frozen base in 4-bit, which drops the base to roughly 6 GB and leaves most of the card for activations, longer sequences or a larger model. The cost is speed: dequantizing weights on every forward and backward pass makes each step slower than LoRA on a 16-bit base. As a rule of thumb you can check against the chart, an A5000 fine-tunes 8B models comfortably with either method and reaches 14B models with QLoRA.
The A5000 runs BF16 but not FP8
The A5000's third-generation Tensor Cores accelerate FP16, BF16, TF32 and INT8. BF16 is the default you want for both training and inference because it keeps FP32's exponent range and rarely needs loss scaling. The card has compute capability 8.6, which means it lacks the FP8 Tensor Cores that arrived with Ada (compute capability 8.9) and Hopper. Some inference engines can still load FP8 checkpoints on Ampere through weight-only kernels, but you get the memory savings without FP8 compute speedups. If your model ships as an FP8 checkpoint, prefer a BF16, INT8 or 4-bit AWQ/GPTQ build on the A5000, or move to an Ada or Hopper card. You can confirm what the runtime sees in a few lines of Python:
import torch
print(torch.cuda.get_device_name(0))          # NVIDIA RTX A5000
print(torch.cuda.get_device_capability(0))    # (8, 6)
print(torch.cuda.is_bf16_supported())         # True
Rendering and creative work on a cloud A5000
In a workstation, the A5000's four DisplayPort outputs, VR headset support and ISV-certified drivers serve interactive design work in tools such as Maya and CATIA. None of those features carry over to a Pod. A Pod has no display or VR headset attached, runs Linux containers rather than Windows and is reached over SSH, JupyterLab, VS Code or a web proxy, so VR development and interactive viewport work stay on a local machine. The A5000 workloads that move well to a Pod are the headless ones: GPU path tracing with Blender Cycles, diffusion pipelines such as ComfyUI, batch video transcoding with NVENC and point-cloud or simulation jobs that write files rather than frames to a screen.
A Blender render on an A5000 Pod runs from the command line with the OptiX backend, which uses the RT Cores:
blender -b scene.blend -E CYCLES -o /workspace/renders/frame_#### -a -- --cycles-device OPTIX
Write outputs to /workspace or a network volume so they survive the Pod stopping. If your pipeline depends on a Windows-only application, keep that step on a local workstation and send the final renders to the cloud.
RTX A5000 vs A4000, A4500, A6000, A40 and L4
| GPU | Architecture | VRAM | Bandwidth | Board power | FP8 | Secure Cloud Pod price | Derived $/M tokens |
|---|---|---|---|---|---|---|---|
| RTX A4000 | Ampere | 16 GB | 448 GB/s | 140 W | No | Console only | Not listed |
| RTX A4500 | Ampere | 20 GB | 640 GB/s | 200 W | No | Console only | Not listed |
| RTX A5000 | Ampere | 24 GB | 768 GB/s | 230 W | No | {{gpu:rtx-a5000}}/hr | $1.57 |
| L4 | Ada | 24 GB | 300 GB/s | 72 W | Yes | {{gpu:l4}}/hr | $8.80 |
| RTX A6000 | Ampere | 48 GB | 768 GB/s | 300 W | No | {{gpu:rtx-a6000}}/hr | $3.44 |
| A40 | Ampere | 48 GB | 696 GB/s | 300 W | No | {{gpu:a40}}/hr | $3.79 |
Hardware specs: NVIDIA datasheets for the RTX A4000, A4500, A5000, A6000, A40 and L4. Derived $/M tokens: cost floor per million output tokens for Llama 3.1 8B in BF16 at batch size 1, computed from each card's decode ceiling and its Secure Cloud rate on runpod.io/pricing on October 20, 2026. The RTX A4000 and A4500 are listed as Runpod GPU types but do not appear on the public Pods pricing table, so check the console for current rates. Availability varies by region and time.
RTX A5000 vs RTX A6000
The A6000 has 10,752 CUDA cores to the A5000's 8,192 and 38.7 FP32 TFLOPS to its 27.8, about 1.4x the compute. Both cards have 768 GB/s of bandwidth, so single-stream decode runs at the same speed on either. Choose the A6000 when the model, its KV cache or your training batch needs more than 24 GB on one device. Choose the A5000 when the workload fits, because the extra compute only pays off in large-batch serving and training.
RTX A5000 vs RTX A4000 and A4500
The A4000 has 16 GB, 448 GB/s and a single-slot 140 W design. The A5000 gives you 1.5x the memory, 1.7x the bandwidth and 1.45x the FP32 throughput. The extra 8 GB is the difference between serving an 8B model in BF16 and having to quantize it. The A4500 sits between them at 20 GB and 640 GB/s, which is enough for 8B models in BF16 with a tight KV cache.
RTX A5000 vs RTX 5000 Ada
The names are close, but these are different cards. The RTX 5000 Ada Generation has 32 GB of GDDR6, 12,800 CUDA cores and 576 GB/s of bandwidth at 250 W. It holds more than the A5000 but streams weights more slowly, so it suits larger models at moderate token rates.
Running an RTX A5000 on Runpod: Pods or Serverless
Runpod gives you two ways to run A5000-class work, and the right one depends on the shape of your traffic rather than the GPU. Pods are dedicated GPU instances you control end to end, billed by the second with no ingress or egress fees. Runpod Serverless runs your model behind a Serverless endpoint whose workers scale up with requests and back down to zero, with sub-200ms cold starts via FlashBoot. For a side-by-side view of other cards, see the Runpod GPU comparison, and for the full Pod lineup, see cloud GPUs on Runpod.
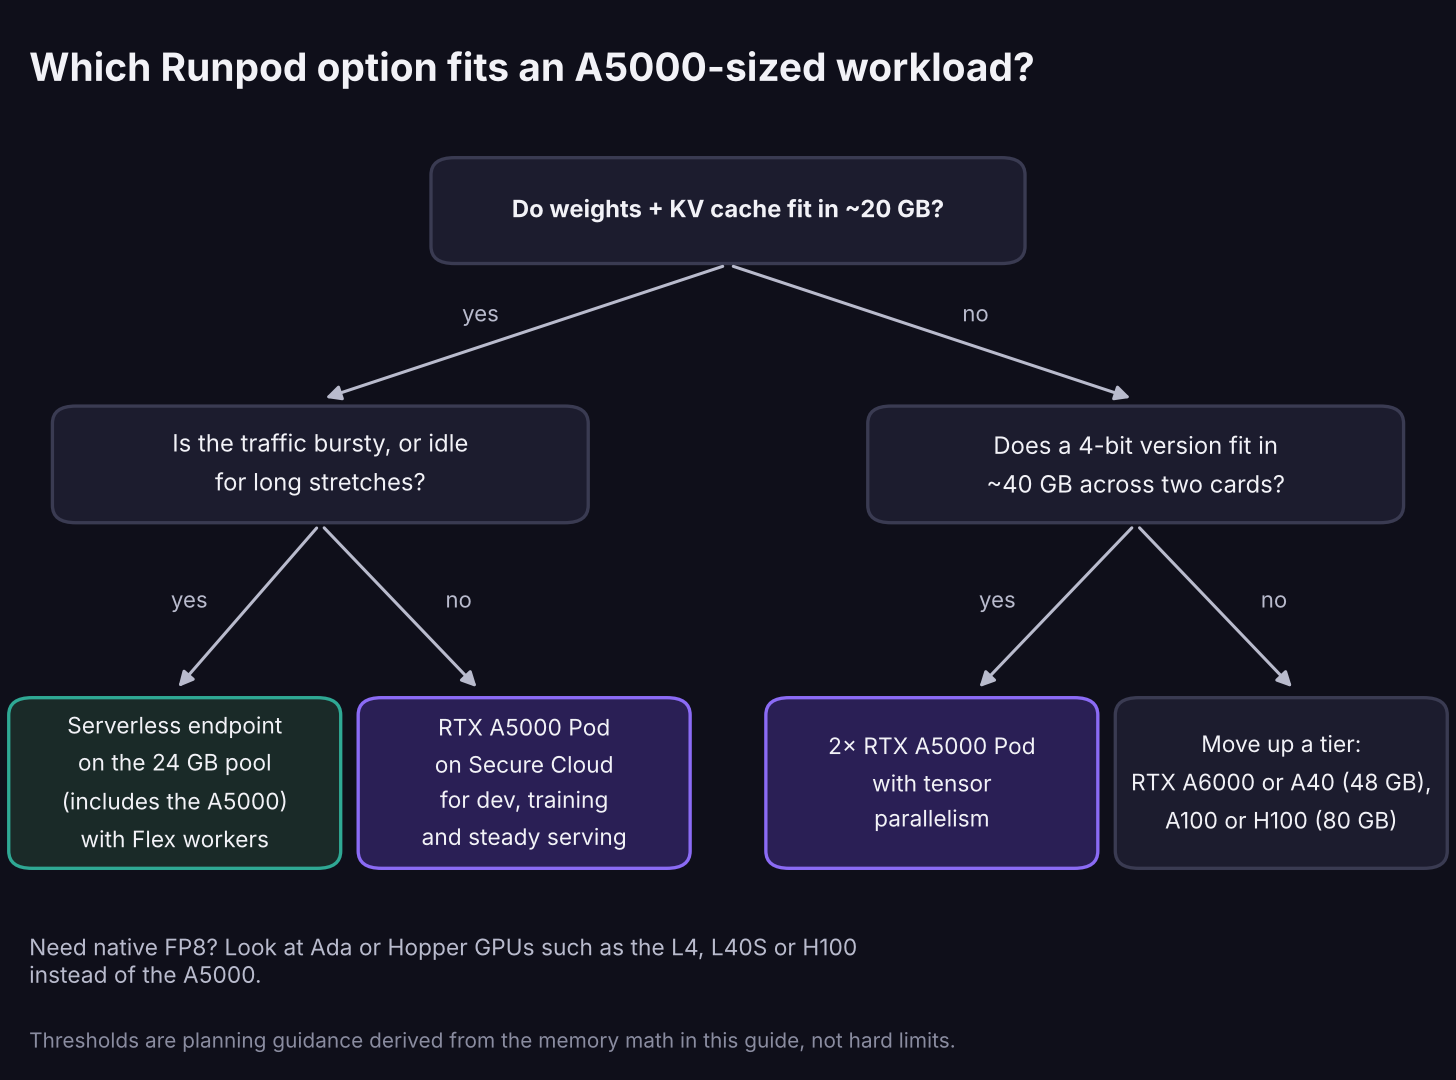
Deploy an RTX A5000 Pod
Use a Pod for notebooks, fine-tuning runs, rendering jobs and inference servers with steady traffic.
- Open Pods in the Runpod console and filter the GPU list to 24 GB.
- Select RTX A5000 and set the GPU count. Choose two if you are splitting a model with tensor parallelism.
- Pick a template. The official Runpod PyTorch template includes CUDA, PyTorch and JupyterLab.
- Attach a network volume if you want models and outputs to persist beyond the Pod's lifetime.
- Deploy, then connect through JupyterLab, SSH or VS Code.
Confirm the GPU, its memory, the driver and the compute capability before you load anything:
nvidia-smi --query-gpu=name,memory.total,memory.used,driver_version,compute_cap --format=csv
On the test Pod used for this guide, the output was:
name, memory.total [MiB], memory.used [MiB], driver_version, compute_cap
NVIDIA RTX A5000, 24564 MiB, 1 MiB, 595.91.07, 8.6
Install vLLM in a virtual environment. On the Runpod PyTorch 2.13.0 template, a plain pip install vllm into the system Python fails because some packages were installed by the operating system and pip cannot replace them.
python -m venv /root/vllm-env
/root/vllm-env/bin/pip install -U pip vllm
export PATH=/root/vllm-env/bin:$PATH
To serve an 8B model from the Pod with an OpenAI-compatible API, start vLLM with a context length that leaves room for the KV cache you sized earlier. Gated repositories such as meta-llama/Llama-3.1-8B-Instruct require an HF_TOKEN environment variable. The ungated unsloth/Meta-Llama-3.1-8B-Instruct mirror used for this guide's test does not.
vllm serve meta-llama/Llama-3.1-8B-Instruct \
  --dtype bfloat16 \
  --max-model-len 16384 \
  --gpu-memory-utilization 0.90
When the engine finishes loading, it logs how much KV cache it reserved. On the test Pod, vLLM 0.32.0 printed:
GPU KV cache size: 37,200 tokens, Maximum concurrency for 16,384 tokens per request: 2.27x
That line tells you how many full-length requests fit at once. If it is too low for your traffic, lower --max-model-len or switch to a 4-bit build.
For a 70B model at 4-bit on a two-GPU Pod, point vLLM at an AWQ checkpoint and split it:
vllm serve <your-70b-awq-checkpoint> \
  --quantization awq \
  --tensor-parallel-size 2 \
  --max-model-len 8192
Serve a model on the 24 GB Serverless pool
Use Serverless when requests arrive in bursts or the endpoint sits idle for long stretches, because Flex workers stop billing once they scale down. Serverless groups GPUs into pools by memory, and the A5000 sits in a 24 GB group that also includes the L4. Selecting the pool lets the scheduler place workers on whichever of those cards has capacity, which improves availability compared with pinning a single GPU type. Your model sees 24 GB on any of them, but token rates vary widely across the pool: the L4 streams weights at 300 GB/s against the A5000's 768 GB/s. Size your latency budget against the slowest card in the pool, not the fastest.
- Open Serverless in the Runpod console, create a new endpoint and choose Deploy LLM API.
- Search for your Hugging Face model, select it and choose Deploy with vLLM.
- In the vLLM settings, open Advanced and set Max Model Length to the context length you sized for, such as 16384. The same settings take a quantization type for AWQ or GPTQ checkpoints. Gated models also need a Hugging Face token. Then click Next.
- Under GPU configuration, select the 24 GB group, which includes the RTX A5000, and clear the groups you don't want.
- Click Create Endpoint. Keep active workers at zero unless you need an always-warm instance, and set max workers in the endpoint's settings to match your peak traffic.
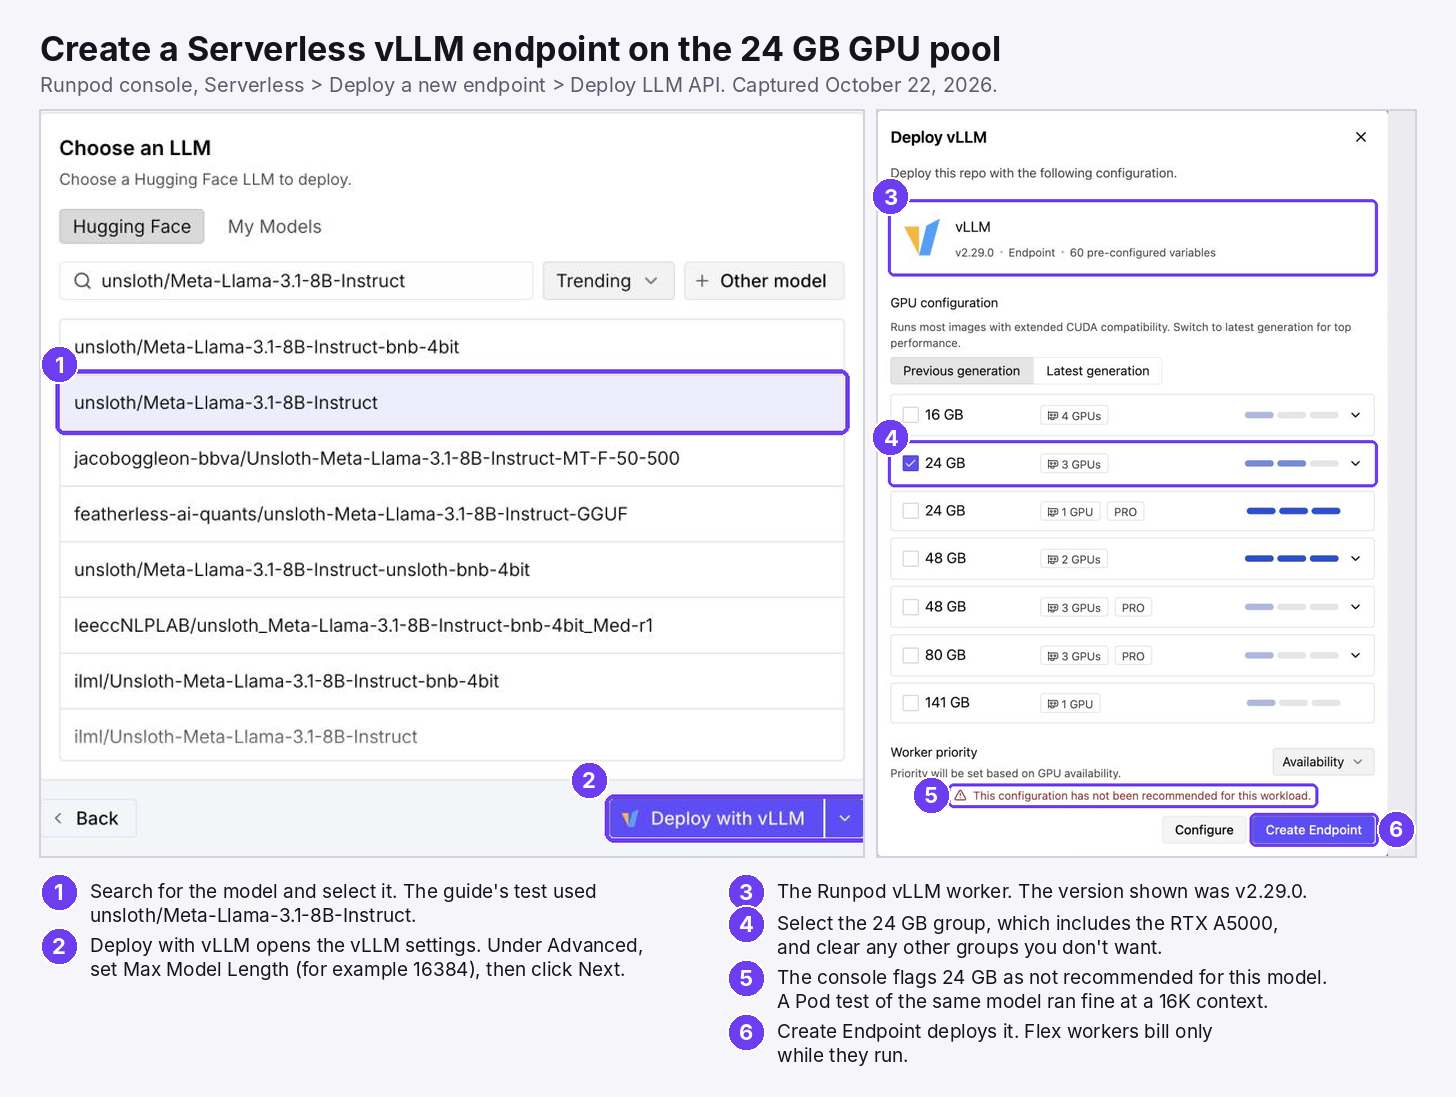
If you create endpoints with the API instead of the console, the vLLM worker reads the same settings from environment variables: MODEL_NAME, MAX_MODEL_LEN, QUANTIZATION and HF_TOKEN.
Serverless bills each worker from start until it fully stops, rounded up to the nearest second. After its last job, a worker waits for the idle timeout (5 seconds by default) before scaling down. The Serverless pricing docs break down which phases are billed.
What an A5000 costs on Runpod
An RTX A5000 Pod on Secure Cloud costs {{gpu:rtx-a5000}}/hr on demand, billed by the second. On Serverless, the 24 GB pool that includes the A5000 runs {{sls:l4-a5000-3090}}/hr on Flex workers. Active workers stay on around the clock, and discounted Active and reserved rates are arranged through sales. Long-running Pods can use savings plans; see the pricing page for current terms.
Estimate a job the same way for either product:
pod_cost        = hourly_rate × GPU_count × hours_running
serverless_cost = hourly_rate × (sum of worker seconds ÷ 3,600)
For a fine-tune that runs for six hours, the Pod math is the whole bill apart from storage. For an API that handles a few thousand requests a day, Serverless usually costs less because you pay only for the seconds workers are up. Compare the two with your own request volume before you commit.
How the numbers in this guide were produced
Most figures in this guide are calculated from published specifications and model files, using the formulas shown in each section, so you can rerun the math for your own model. The speed ceilings, cost floors and memory charts are derived, not benchmarked. A small set of figures was measured on a Runpod RTX A5000 Pod to check the math: single-user decode speed and vLLM's KV cache allocation for Llama 3.1 8B in BF16 and 4-bit AWQ. Both measured speeds landed at about 88% of the derived ceilings.
- Hardware figures come from NVIDIA's datasheets for each card and NVIDIA's CUDA compute capability list.
- Model figures come from the Llama 3.1 Instruct files on Hugging Face. For 8B: 32 layers, 8 KV heads and a head dimension of 128 in
config.json, a 16.1 GB BF16 checkpoint and a 5.7 GB 4-bit AWQ checkpoint. For 70B: 80 layers and 8 KV heads inconfig.jsonand a 39.8 GB 4-bit AWQ checkpoint. - Prices are Runpod Secure Cloud on-demand Pod rates from runpod.io/pricing on October 20, 2026.
- Three inputs are assumptions rather than measurements: about 1.5 GB of runtime overhead in the 24 GB budget (vLLM measured 1.43 GiB of peak activations on the test Pod), LoRA at rank 16 on every linear layer and 16 bytes per parameter for mixed-precision training with Adam.
Measured throughput depends on the inference engine and its version, the attention kernels, batch size and context length, so real token rates land below the ceilings shown here. The single-GPU commands in this guide were tested on a Runpod RTX A5000 Pod on October 20, 2026, using the Runpod PyTorch 2.13.0 template on Ubuntu 24.04.5 with NVIDIA driver 595.91.07 (CUDA 13.2), vLLM 0.32.0 with PyTorch 2.13.0 (CUDA 13.0 build) and Blender 4.2.23 LTS. The Blender test rendered the default scene with -f 1 instead of -a. The two-GPU 70B command has not been tested, because only one A5000 was available on that date.
Frequently asked questions
What are the NVIDIA RTX A5000's specs?
The RTX A5000 has 8,192 CUDA cores, 256 third-generation Tensor Cores and 64 second-generation RT Cores on NVIDIA's Ampere GA102 GPU. It carries 24 GB of GDDR6 memory with ECC on a 384-bit bus, delivering 768 GB/s of bandwidth. It is rated at 27.8 TFLOPS FP32, draws 230 W and connects over PCIe 4.0 x16.
How much VRAM does the RTX A5000 have? Is there a 16 GB version?
The desktop RTX A5000 has 24 GB of GDDR6 with ECC. The 16 GB figure belongs to the RTX A5000 Laptop GPU, a different chip (GA104) with 6,144 CUDA cores, 16 GB of GDDR6 on a 256-bit bus and a power range of roughly 80-165 W. Cloud A5000s, including those on Runpod, are the 24 GB desktop card.
Is the RTX A5000 good for AI and deep learning?
Yes, for models and methods that fit in 24 GB. It serves 7B-8B LLMs in BF16, 14B in INT8 and 32B in 4-bit, and it fine-tunes 8B models with LoRA or QLoRA. It cannot fully fine-tune an 8B model, and it has no FP8 Tensor Cores, so FP8-first workflows belong on Ada or Hopper GPUs.
How much does an RTX A5000 cost?
On Runpod, an RTX A5000 Pod on Secure Cloud costs {{gpu:rtx-a5000}}/hr, billed by the second, and the 24 GB Serverless pool runs {{sls:l4-a5000-3090}}/hr on Flex workers. This guide covers cloud rental. Purchase prices for new and used cards change with the market, so check current retailer listings if you plan to buy one.
Can two RTX A5000s give you 48 GB?
Two A5000s give you 48 GB in aggregate, but not one 48 GB memory space. Frameworks split a model across them with tensor or pipeline parallelism, which is how a 4-bit 70B model runs on a pair. An NVLink bridge carries 112.5 GB/s between the two cards; without one, they communicate over PCIe. Run nvidia-smi topo -m to see which link your system has.
Is the RTX A5000 good for gaming?
It runs games, but it is a workstation card tuned for sustained professional loads at 230 W rather than peak game clocks, and its drivers prioritize certified professional applications. Buy the A5000 for ECC memory, certified drivers and multi-display professional work, not for gaming alone.
Is the RTX A5000 the same as the RTX 5000 Ada?
No. The RTX 5000 Ada Generation is a newer Ada Lovelace card with 32 GB of GDDR6, 12,800 CUDA cores, 576 GB/s of bandwidth and FP8 support. The RTX A5000 is the earlier Ampere card with 24 GB and 768 GB/s.
How do I rent an RTX A5000 in the cloud?
On Runpod, deploy an RTX A5000 Pod on Secure Cloud from the console for dedicated use, billed by the second. For inference that should scale to zero, create a Serverless endpoint on the 24 GB pool, which includes the A5000.
Start building on an RTX A5000
If your model fits the 24 GB math above, deploy an RTX A5000 Pod for development and fine-tuning, or create a Serverless endpoint on the 24 GB pool for production inference. Learn more about Runpod Serverless, or compare the A5000 with a data center card in the NVIDIA A100 guide. If you need reserved capacity or volume pricing for a larger fleet, talk to sales.
Sources
- NVIDIA RTX A5000 datasheet
- NVIDIA RTX A6000 datasheet
- NVIDIA RTX A4500 datasheet
- NVIDIA A40 datasheet
- NVIDIA CUDA GPU compute capability list
- Runpod GPU types and Serverless GPU pools
- Runpod Pods overview
- Runpod Serverless pricing
- Runpod vLLM worker environment variables
- Llama 3.1 8B Instruct config and BF16 checkpoint on Hugging Face
- Llama 3.1 8B Instruct AWQ INT4 checkpoint on Hugging Face
- Llama 3.1 70B Instruct AWQ INT4 checkpoint on Hugging Face
- Runpod pricing (Secure Cloud Pod and Serverless rates used for derived costs, October 20, 2026)
- Runpod Serverless product page
NVIDIA, RTX and Quadro are trademarks of NVIDIA Corporation.
Related guides
- NVIDIA A100 GPU: Specs, Clusters, MIG, and Cloud Rental
- Artificial Intelligence and Cloud Computing Guide
- Serverless GPUs for API Hosting: How They Power AI APIs–A Runpod Guide
- Maximize AI Workloads with Runpod’s Secure GPU as a Service
- LLM Training with Runpod GPU Pods: Scale Performance, Reduce Overhead
- Unlock Efficient Model Fine-Tuning With Pod GPUs Built for AI Workloads
Author profile: Matt Sarrel