PyTorch 2.4 with CUDA 12.4 is a pinned deep learning environment: PyTorch 2.4.1, the CUDA 12.4.1 runtime, cuDNN 9, Python 3.11 and Ubuntu 22.04. It runs on every Ampere, Ada and Hopper GPU on Runpod Secure Cloud, including the A100, H100, H200 and L40S, but not on Blackwell. Use it to reproduce a 2.4 result, satisfy a dependency pin or debug a 2.4 production model.
Runpod packages it as the official template image runpod/pytorch:2.4.0-py3.11-cuda12.4.1-devel-ubuntu22.04 (the tag says 2.4.0, but the image reports PyTorch 2.4.1). PyTorch released 2.4 on July 24, 2024, and it was the first release to publish prebuilt CUDA 12.4 wheels. The current stable release is PyTorch 2.15, so 2.4 is no longer the default choice for new work.
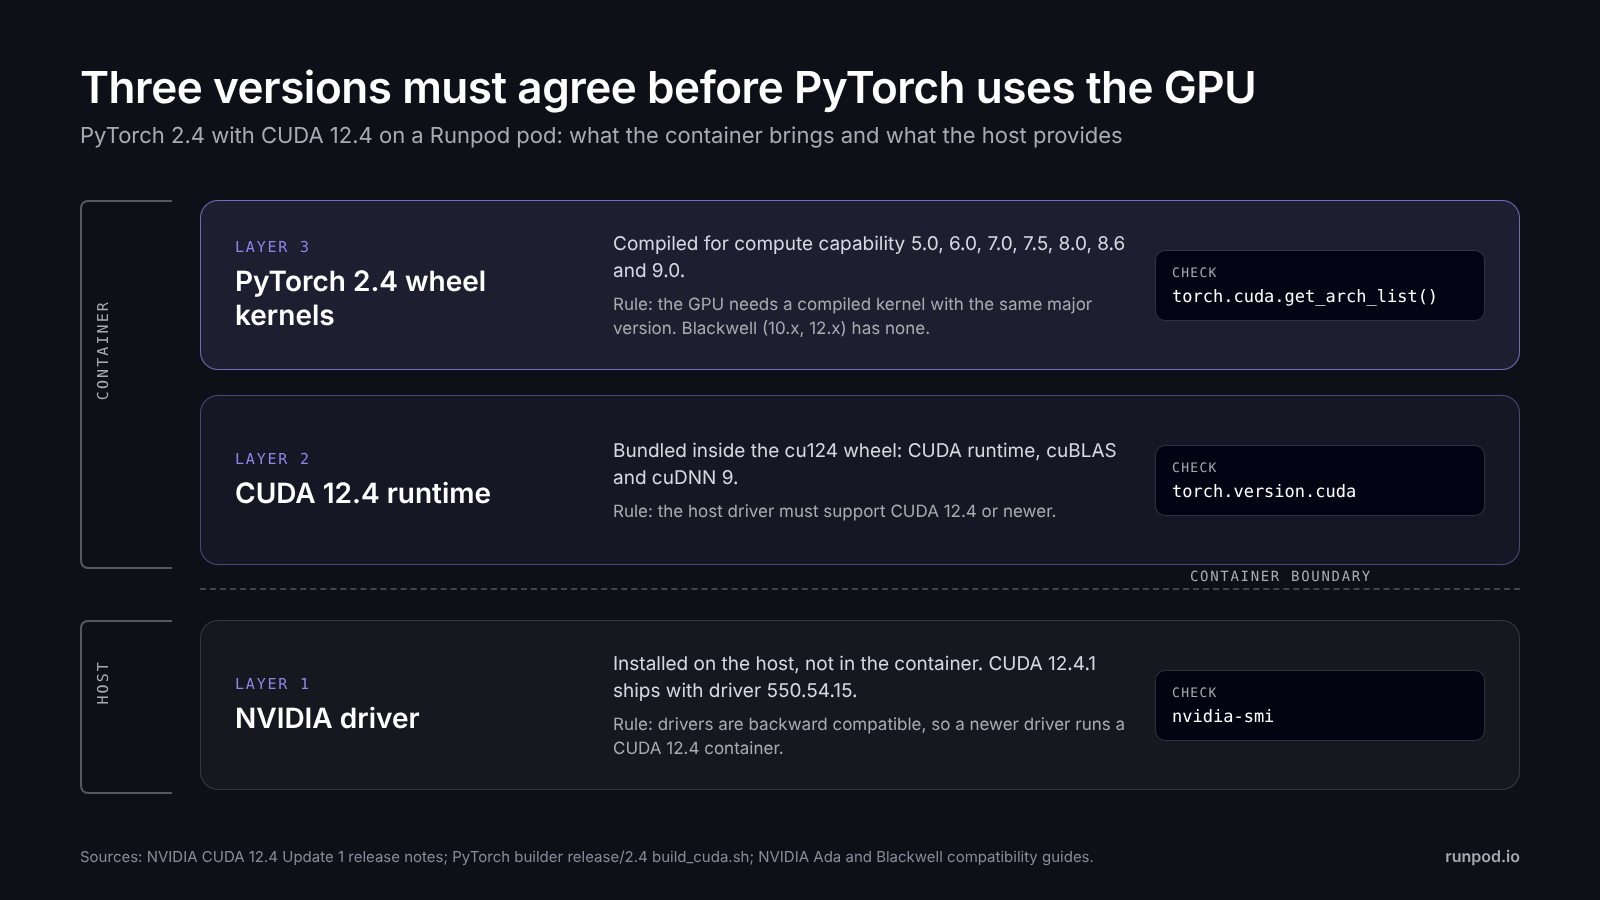
"CUDA 12.4" in this guide means the CUDA runtime libraries that ship inside the container. The NVIDIA driver on the host has its own version, and the PyTorch wheel adds a third constraint: a fixed list of GPU architectures it contains compiled kernels for. The host driver must support the container's CUDA runtime, and the wheel must include kernels compatible with your GPU.
Use PyTorch 2.4 with CUDA 12.4 only when one of these applies:
- You are reproducing a paper, benchmark or checkpoint that was produced on PyTorch 2.4.
- A dependency in your stack pins torch==2.4.* and you cannot upgrade it yet.
- You maintain a model in production on 2.4 and need a matching environment for debugging.
For new training and fine-tuning projects, use the current PyTorch template. Blackwell GPUs (B200, B300, RTX PRO 6000 and RTX PRO 4500) cannot run PyTorch 2.4 and need PyTorch 2.7 or later with a CUDA 12.8 or newer build. Multi-node training starts from the PyTorch template built for Clusters.
| Your situation | Use | Why |
|---|---|---|
| New project, any GPU | Current PyTorch template | Newest kernels, Blackwell support and current torch.compile |
| Reproducing a 2.4 result on A100, H100, H200, L40S or RTX A6000 | PyTorch 2.4 + CUDA 12.4 | Matches the PyTorch and CUDA versions of the original run |
| A dependency pins torch 2.4 | PyTorch 2.4 in a venv on a current template | Keeps the pin without fighting host filters |
| Any Blackwell GPU | PyTorch 2.7 or later with CUDA 12.8+ | PyTorch 2.4 ships no Blackwell kernels |
| Multi-node training | PyTorch template for Clusters | Built for multi-node networking |
Note: Blackwell support arrived in PyTorch 2.7 (April 2025) with CUDA 12.8 wheels. Sources are listed at the end of the article.
Driver, CUDA runtime and PyTorch wheel compatibility
"CUDA version" refers to three separate numbers, and a mismatch in each one produces a different failure.
The first is the driver version on the host machine. You do not install it inside a container; the host provides it, and nvidia-smi reports it along with the highest CUDA version that driver supports. NVIDIA drivers are backward compatible, so a newer driver runs containers built for older CUDA releases. The CUDA 12.4.1 toolkit ships with driver 550.54.15, and CUDA 12.x applications can run on drivers as old as 525.60.13 through minor version compatibility, with some limitations described in NVIDIA's CUDA compatibility guide.
The second is the CUDA runtime inside the container. The PyTorch CUDA 12.4 wheels bundle their own copies of the CUDA runtime, cuBLAS and cuDNN 9, which is why pip install gives you a working GPU build without a system-wide CUDA toolkit. The Runpod image is a "devel" image, so it also includes nvcc for compiling custom CUDA extensions.
The third is the list of GPU architectures compiled into the wheel. NVIDIA identifies each GPU generation by a compute capability, such as 8.0 for the A100 or 9.0 for the H100. The PyTorch 2.4 CUDA 12.4 wheels were built for compute capabilities 5.0, 6.0, 7.0, 7.5, 8.0, 8.6 and 9.0. The wheels carry no PTX, so a newer GPU has no just-in-time compilation path either: torch.cuda.get_arch_list() on the 2.4.1 wheel lists only sm_ entries. A GPU outside that list has no kernels to run, and PyTorch reports "no kernel image is available for execution on the device" the first time it launches one.
Supported GPUs: which Runpod GPUs run PyTorch 2.4
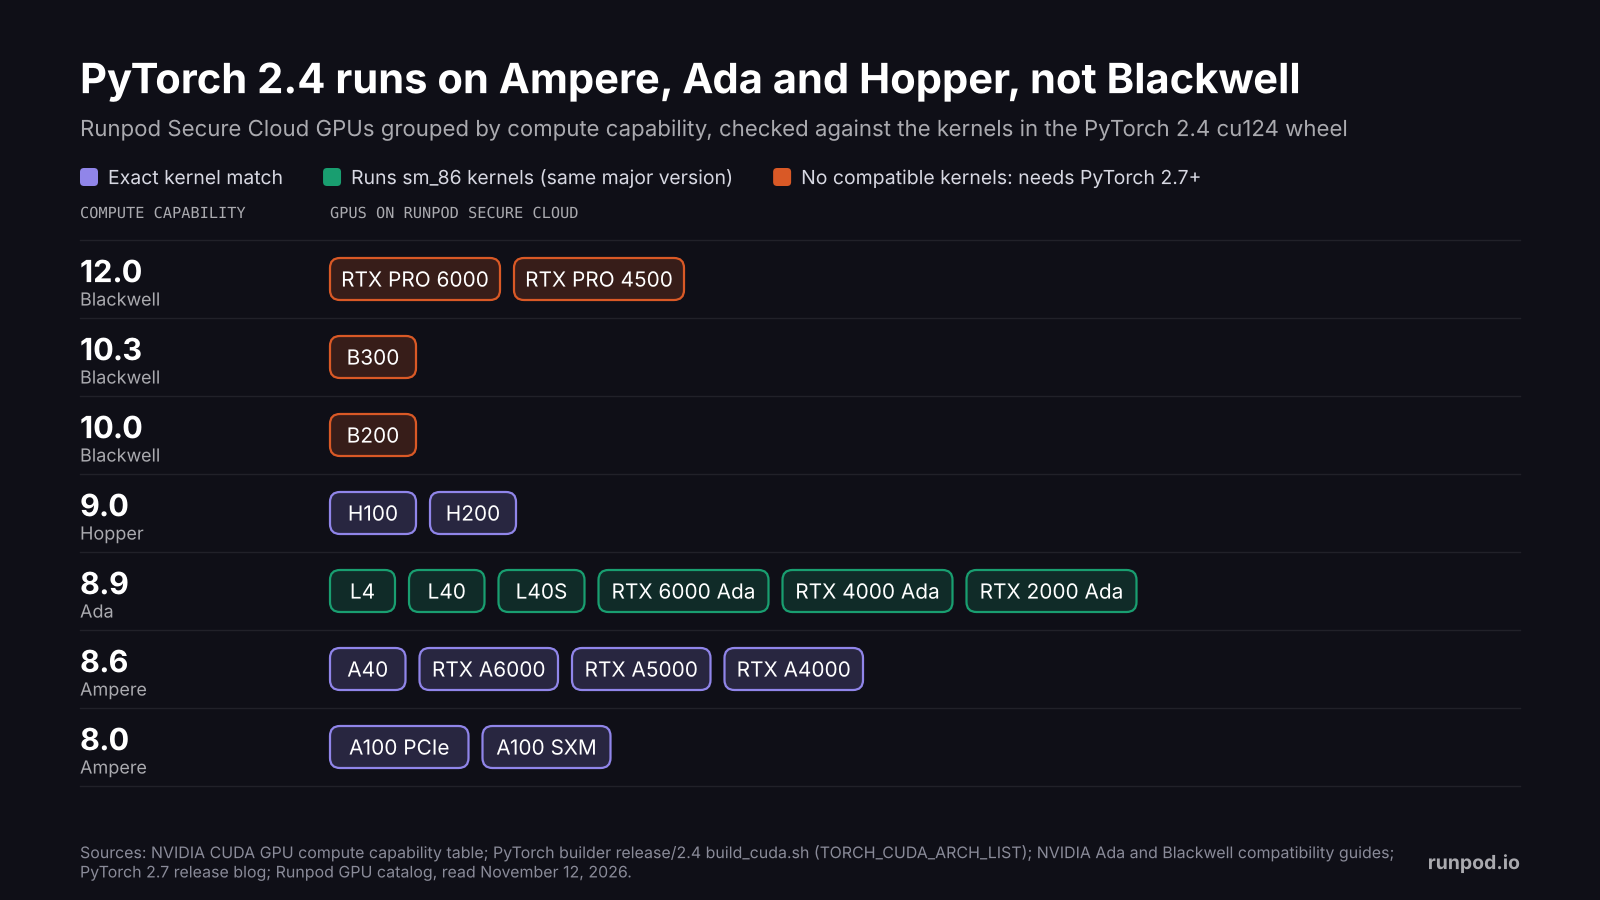
NVIDIA guarantees that a kernel compiled for one compute capability runs on any GPU with the same major version and an equal or higher minor version. A kernel compiled for 8.6 therefore runs on 8.9, but no kernel crosses a major version.
Here is how Runpod Secure Cloud GPUs match the kernels in the 2.4 wheel:
- The A100 (8.0) and the H100 and H200 (9.0) have exact matches in the wheel.
- The A40, RTX A6000, RTX A5000 and RTX A4000 (8.6) have exact matches.
- The L4, L40, L40S, RTX 6000 Ada, RTX 4000 Ada and RTX 2000 Ada (8.9) run the 8.6 kernels through same-major compatibility. They work, although they do not get kernels tuned for 8.9.
- The B200 (10.0), the B300 (10.3) and the RTX PRO 6000 and RTX PRO 4500 Blackwell cards (12.0) have no compatible kernels.
The motion diagram below shows the lookup PyTorch performs at the first kernel launch.
Diagram: PyTorch 2.4 looks up a compiled kernel for the GPU's compute capability. An H100 (sm_90) finds an exact match, an L40S (sm_89) runs the sm_86 kernels, and a B200 (sm_100) finds no kernel it can run.
Launch a PyTorch 2.4 pod on Runpod
Use the official template for a quicker setup when a supported GPU has capacity. A virtual environment on a current template works on any GPU that PyTorch 2.4 supports, because it does not depend on the 2.4 template's host filter.
Option 1: the official PyTorch 2.4.0 template
The official template lists CUDA 12.4 through 12.9 as its allowed host versions, while most Runpod hosts now report CUDA 13.x. The console shows a "Potential CUDA version mismatch" warning for those hosts but still deploys, and the newer driver runs the CUDA 12.4 runtime through backward compatibility. On November 16, 2026, this template ran on an A100 host reporting CUDA 13.2, and the verification script and BF16 loop below both passed. If no supported GPU has capacity, use Option 2.
- Open the Runpod console, go to Pods and select Deploy.
- Under Compute, choose a GPU from the supported list above. For single-GPU fine-tuning, the L40S is the default choice at {{gpu:l40s}}/hr on Secure Cloud.
- Under Template, select Runpod Pytorch 2.4.0. The image tag should read runpod/pytorch:2.4.0-py3.11-cuda12.4.1-devel-ubuntu22.04.
- Leave port 8888 (JupyterLab) and port 22 (SSH) exposed. The template starts JupyterLab and SSH automatically.
- Set the volume size for anything you want to keep. The template mounts persistent storage at /workspace, and only files under that path survive a stop.
- Select Deploy. Billing starts when the pod runs and is charged per second.
Option 2: pin PyTorch 2.4 in a virtual environment
This path starts from the current PyTorch template and installs the 2.4 wheels into a virtual environment on the persistent volume. The Runpod Pytorch 2.8.0 template only deploys to hosts that report CUDA 12.8 or later, so the host driver is new enough to run the CUDA 12.4 runtime that the wheel bundles.
Deploy a pod on a supported GPU with the Runpod Pytorch 2.8.0 template (image runpod/pytorch:1.0.2-cu1281-torch280-ubuntu2404, CUDA 12.8.1 on Ubuntu 24.04). Check the interpreter with python3 --version first. PyTorch 2.4.1 publishes CUDA 12.4 wheels for Python 3.8 through 3.12, so any of those versions works. Then open a terminal and run:
python3 -m venv /workspace/venv-torch24
source /workspace/venv-torch24/bin/activate
pip install --upgrade pip
pip install torch==2.4.1 torchvision==0.19.1 torchaudio==2.4.1 \
  --index-url https://download.pytorch.org/whl/cu124
Use torch==2.4.0 torchvision==0.19.0 torchaudio==2.4.0 instead when you need the exact 2.4.0 build. The venv lives on /workspace, so it survives a stop and a restart, and source /workspace/venv-torch24/bin/activate restores it. A stopped pod can only start again on the same host, though. If another user takes that host's GPU while the pod is stopped, the pod cannot start until the GPU frees up. To avoid that wait, create the venv on a network volume, which you can attach to a new pod in the same data center.
To use the venv in JupyterLab, register it as a kernel:
pip install ipykernel
python -m ipykernel install --user --name torch24 --display-name "PyTorch 2.4 (cu124)"
The kernel registration lives on the container disk, which is erased when the pod stops. After each stop, activate the venv and rerun the ipykernel install line, or put both in a /workspace/setup.sh that you run at startup. Without the activation, the line registers the template's own Python, which runs PyTorch 2.8, under the PyTorch 2.4 display name. Run the verification script below to check that the notebook is using PyTorch 2.4.
Build CUDA extensions against the 2.4 wheel
A codebase that compiles its own CUDA extensions needs one more check, because the extension is built with the system nvcc while PyTorch was built with CUDA 12.4. When you build with setup.py and BuildExtension, PyTorch's extension builder compares the two versions before it compiles. JIT builds through torch.utils.cpp_extension.load() and load_inline() skip this check.
In PyTorch 2.4, a different major version raises an error stating that the detected CUDA version mismatches the version used to compile PyTorch. A different minor version only prints a warning that the mismatch is most likely not a problem. The Runpod Pytorch 2.8.0 template ships nvcc from CUDA 12.8, so a build in the Option 2 venv proceeds with that warning.
Confirm which nvcc the build will use before you start a long compile:
nvcc --version
python -c "import torch; print(torch.version.cuda)"
When your project needs an exact toolchain match, build the extension in the official 2.4.0 devel image from Option 1, which ships nvcc from CUDA 12.4.1, and keep the built artifact on /workspace so later pods can reuse it.
Check the PyTorch CUDA version and GPU before you train
Run this check before any long job. It confirms the PyTorch build and its CUDA version, checks whether CUDA is available to PyTorch, reads the GPU's compute capability and tests whether the wheel contains a matching kernel.
import torch

print("torch:", torch.__version__)            # expect 2.4.x+cu124
print("CUDA runtime:", torch.version.cuda)     # expect 12.4
print("cuDNN:", torch.backends.cudnn.version())
print("CUDA available:", torch.cuda.is_available())

if torch.cuda.is_available():
    major, minor = torch.cuda.get_device_capability(0)
    print("GPU:", torch.cuda.get_device_name(0), f"(sm_{major}{minor})")
    arch_list = torch.cuda.get_arch_list()      # kernels compiled into this wheel
    print("Wheel kernels:", arch_list)
    caps = [int(a[3:]) for a in arch_list if a.startswith("sm_")]
    compatible = any(c // 10 == major and c % 10 <= minor for c in caps)
    print("Compatible kernel present:", compatible)

    # A real kernel launch is the definitive test.
    x = torch.randn(1024, 1024, device="cuda")
    print("Matmul OK:", (x @ x).sum().item() != 0)
On an H100, the arch list includes sm_90 and the matmul succeeds. On a Blackwell GPU, torch.cuda.is_available() can still return True. PyTorch 2.4 checks the compiled kernels when it initializes CUDA and prints a warning that the GPU "with CUDA capability sm_100 is not compatible with the current PyTorch installation" (the B200 case; the number changes with the card). The first kernel launch, the torch.randn line, then raises a RuntimeError with the no-kernel-image message. That is why the script launches a kernel instead of stopping at the availability check.
For a check from outside Python, run nvidia-smi. The "CUDA Version" in its header is the highest version the driver supports, not the version inside your container.
Train with mixed precision on PyTorch 2.4
Every GPU that PyTorch 2.4 supports on Runpod Secure Cloud is Ampere or newer, so every one of them supports bfloat16 (BF16). BF16 autocast cuts activation memory and uses Tensor Cores without the loss scaling that FP16 requires. The loop below defines its own small model, random data, loss and optimizer, so you can paste it into a notebook as written.
import torch
import torch.nn as nn

device = "cuda"
torch.manual_seed(0)

# Toy model and data. Replace with your model, DataLoader and loss.
model = nn.Sequential(nn.Linear(1024, 4096), nn.GELU(), nn.Linear(4096, 10)).to(device)
loss_fn = nn.CrossEntropyLoss()
optimizer = torch.optim.AdamW(model.parameters(), lr=1e-3)

# Optional: compile the model. Remove this line if a custom op does not compile.
model = torch.compile(model)

for step in range(100):
    inputs = torch.randn(256, 1024, device=device)
    targets = torch.randint(0, 10, (256,), device=device)

    optimizer.zero_grad(set_to_none=True)
    with torch.amp.autocast("cuda", dtype=torch.bfloat16):
        loss = loss_fn(model(inputs), targets)
    loss.backward()
    optimizer.step()

    if step % 20 == 0:
        print(f"step {step} loss {loss.item():.4f}")
PyTorch 2.4 deprecates the older torch.cuda.amp.autocast(...) and torch.cuda.amp.GradScaler(...) spellings in favor of torch.amp.autocast("cuda", ...) and torch.amp.GradScaler("cuda", ...). Code written for earlier releases still runs but emits a FutureWarning, so update the calls when you touch the file. If you must train in FP16, wrap the backward pass with torch.amp.GradScaler("cuda").
What changed in PyTorch 2.4
PyTorch 2.4 was an incremental release with the following additions:
- torch.compile gained Python 3.12 support (beta).
- A new higher-level Python custom operator API in torch.library made custom kernels compatible with torch.compile (beta).
- The TCPStore server used for distributed initialization switched to a libuv backend by default, which reduces startup time on large jobs (beta).
- FSDP2, a per-parameter sharding implementation built on DTensor, and torch.distributed.pipelining arrived as prototypes.
- AOTInductor freezing for CPU and several CPU and aarch64 performance improvements shipped as well.
FlexAttention, Blackwell support and the CUDA 12.8 wheels all arrived after 2.4, and many current tutorials assume them. If a tutorial or library calls an API you cannot find in 2.4, check its minimum PyTorch version before you debug your own code.
To measure the speed cost, we ran the same training script on one H100 SXM pod on Runpod Secure Cloud on November 16, 2026 under three PyTorch builds: 2.4.1 in a venv, 2.8.0 from the current template and 2.15.0, the latest stable release. The model is a 217.7M-parameter decoder-only transformer trained with BF16 autocast and fused AdamW at batch size 8 and sequence length 1024. PyTorch 2.15 on CUDA 13.2 delivered 16% more tokens per second than PyTorch 2.4.1 on CUDA 12.4 in eager mode and 11% more with torch.compile, with peak memory at about 10.4 GB in every run. The gap reflects the whole stack, including the CUDA and cuDNN versions, not the framework version alone.
| PyTorch build | Eager step time | Compiled step time | Compiled throughput |
|---|---|---|---|
| 2.4.1 (CUDA 12.4) | 38.7 ms | 32.8 ms | 249,541 tokens/s |
| 2.8.0 (CUDA 12.8) | 35.5 ms | 31.0 ms | 264,507 tokens/s |
| 2.15.0 (CUDA 13.2) | 33.3 ms | 29.6 ms | 276,671 tokens/s |
Note: each figure is the median of 60 timed steps after 15 warmup steps. A repeat run of the 2.4.1 and 2.15.0 configurations matched within 0.6%. All runs used driver 595.91.07 (host CUDA 13.2) on the Runpod Pytorch 2.8.0 template image, with 2.4.1 and 2.15.0 installed in virtual environments alongside the template's 2.8.0. These results cover one model on one GPU. The gap varies with the model and its kernels; benchmark your own workload before deciding whether to keep the 2.4 pin.
Pods are billed per second, so step time converts directly into GPU cost. On this model and GPU, keeping the 2.4 pin adds about 11% to the GPU bill for the same number of training steps with torch.compile and about 16% in eager mode.
Troubleshooting
torch.cuda.is_available() returns False
When PyTorch reports that CUDA is not available, either the container cannot see a GPU or the installed wheel has no CUDA support. Confirm the pod was deployed with a GPU rather than as a CPU pod, then run nvidia-smi. If nvidia-smi works but PyTorch still reports False, you most likely installed a CPU-only wheel. Reinstall with the --index-url https://download.pytorch.org/whl/cu124 flag shown above.
"no kernel image is available for execution on the device"
The wheel has no kernels for your GPU's compute capability, so the CUDA runtime finds nothing it can launch. Run torch.cuda.get_arch_list() and compare it with torch.cuda.get_device_capability(). If no entry shares the GPU's major version, this error follows. On Runpod, that almost always means a Blackwell GPU. Move to PyTorch 2.7 or later with a CUDA 12.8 or newer build, or redeploy on an Ampere, Ada or Hopper GPU.
"CUDA driver version is insufficient for CUDA runtime version"
The host driver is older than the runtime in your container. On Runpod, filter by CUDA version when you deploy so the scheduler places the pod on a host with a driver that supports CUDA 12.4 or later.
The template shows no available GPUs
The official 2.4.0 template lists CUDA 12.4 through 12.9 as its allowed host versions. On a host with a newer driver, the console warns about a CUDA version mismatch but still deploys, and the pod works. When no supported GPU has capacity, use Option 2 and install the 2.4 wheels into a venv on a current template.
Packages disappear after a stop or a pod edit
Anything installed outside /workspace lives on the container disk, which a stop or a pod edit resets. Keep the venv and your Hugging Face cache under /workspace.
Run it on Runpod
- Pods handle interactive development and single-node training. Use Option 1 or Option 2 above, and keep code, data and checkpoints on the volume.
- Clusters handle multi-node training. The Clusters templates are configured for multi-node networking, so start from the PyTorch template built for Clusters rather than the single-node 2.4.0 template.
- Serverless runs the trained model behind an API endpoint. Package the model and handler in a container that pins the same PyTorch version you trained on, and the endpoint scales from zero. FlashBoot brings worker cold starts to sub-200ms; loading your model's weights into GPU memory adds time that depends on model size.
Recommended GPUs for PyTorch 2.4
| Workload | GPU | Rate on Secure Cloud |
|---|---|---|
| Notebook exploration and small vision models (full fine-tuning up to about 1.5B parameters, derived) | RTX A5000 (24 GB) | {{gpu:rtx-a5000}}/hr |
| Single-GPU fine-tuning (full fine-tuning up to about 3B parameters, derived) | L40S (48 GB) | {{gpu:l40s}}/hr |
| Larger full fine-tuning (up to about 5B parameters, derived) | A100 SXM (80 GB) | {{gpu:a100-sxm}}/hr |
| Same 80 GB ceiling as the A100, with higher throughput (up to about 5B parameters, derived) | H100 SXM (80 GB) | {{gpu:h100-sxm}}/hr |
| Models that need more than 80 GB on one GPU (up to about 8.8B parameters, derived) | H200 (141 GB) | {{gpu:h200}}/hr |
Note: every GPU in this table runs PyTorch 2.4. Blackwell GPUs are excluded because PyTorch 2.4 has no kernels for them. The parameter figures are derived, not measured: full fine-tuning with AdamW in mixed precision holds at least 16 bytes per parameter (weights, gradients and two optimizer states), so the ceiling is GPU memory divided by 16 bytes, for example 80 GB ÷ 16 bytes = 5B parameters. Activations, batch size and sequence length lower the real limit, and LoRA or other parameter-efficient methods raise it substantially. Pods are billed per second. MI300X pods also run PyTorch, but on the ROCm builds rather than the cu124 wheels in this guide.
Frequently asked questions
What is PyTorch 2.4 with CUDA 12.4, and when do I need it?
It is the PyTorch 2.4 release built against the CUDA 12.4 runtime. You need it when you are reproducing work that was produced on PyTorch 2.4 or when a dependency pins torch 2.4. For new projects, start from the current PyTorch release.
Does PyTorch support CUDA 12.4?
Yes. PyTorch 2.4 was the first release to publish prebuilt CUDA 12.4 wheels. Install them with pip and --index-url https://download.pytorch.org/whl/cu124, and run them on any host with a CUDA 12.x driver or newer. The wheel bundles its own CUDA runtime, and minor version compatibility lets drivers as old as 525.60.13 run it, with some limitations.
What is the latest PyTorch version with CUDA 12.4 wheels?
PyTorch 2.6. It is the newest release on PyTorch's previous-versions page with a CUDA 12.4 wheel command. PyTorch 2.7 dropped the cu124 build in favor of CUDA 11.8, 12.6 and 12.8 builds.
Which GPUs does PyTorch 2.4 support on Runpod?
Every Ampere, Ada and Hopper GPU on Runpod Secure Cloud runs PyTorch 2.4. That includes the A100, A40, RTX A6000, RTX A5000, RTX A4000, L4, L40, L40S, RTX 6000 Ada, RTX 4000 Ada, RTX 2000 Ada, H100 and H200. Blackwell GPUs, which on Runpod are the B200, B300, RTX PRO 6000 and RTX PRO 4500, require PyTorch 2.7 or later.
How do I install PyTorch with the right CUDA version on a cloud GPU?
Pick the wheel index that matches the CUDA build you want, for example --index-url https://download.pytorch.org/whl/cu124 for CUDA 12.4. Then run nvidia-smi to confirm the host driver is in the CUDA 12 line or newer. The wheel bundles its own runtime, so the host only needs a driver that is new enough.
Is there a Docker image for PyTorch 2.4 with CUDA 12.4?
Yes. The official template runs the public image runpod/pytorch:2.4.0-py3.11-cuda12.4.1-devel-ubuntu22.04, which bundles PyTorch 2.4.1 (the tag says 2.4.0), the CUDA 12.4.1 toolkit and Python 3.11 on Ubuntu 22.04. You can use it as the base of your own Dockerfile and point a custom Runpod template at the result, which keeps your training and inference containers on the same PyTorch build.
Can I install PyTorch 2.4 with conda?
Yes, but pip is the better path. PyTorch's previous-versions page lists conda install pytorch==2.4.1 torchvision==0.19.1 torchaudio==2.4.1 pytorch-cuda=12.4 -c pytorch -c nvidia for CUDA 12.4. PyTorch stopped publishing conda packages with the 2.6 release, so that channel carries no newer versions, and the pip command in Option 2 also works inside a conda environment.
How do I check the CUDA version on Runpod?
Run python -c "import torch; print(torch.version.cuda)" for the runtime PyTorch uses, and run nvidia-smi for the driver version and the highest CUDA version it supports. The first number tells you what PyTorch was built against; the second tells you what the host can run.
Is CUDA 12.4 compatible with newer drivers?
Yes. NVIDIA drivers are backward compatible, so a driver that supports CUDA 13 runs a container built for CUDA 12.4. The reverse does not hold: a driver older than the CUDA 12 minimum cannot run a CUDA 12.4 container.
Should I upgrade from PyTorch 2.4?
Upgrade when nothing pins you to 2.4. In the H100 benchmark above, a 217.7M-parameter decoder trained in BF16 at batch size 8 and sequence length 1024, PyTorch 2.15 delivered 11% to 16% more tokens per second, and Blackwell GPUs need PyTorch 2.7 or later. Stay on 2.4 only to reproduce a 2.4 result, satisfy a dependency pin or debug a 2.4 production model.
Does code written for PyTorch 1.x run on PyTorch 2.4?
Most of it does, because PyTorch 2.x kept the eager-mode API. Some APIs have been deprecated or removed since 1.x, so run your test suite after the upgrade and read the warnings rather than assuming full compatibility.
How do I persist data and environments between sessions?
Keep everything under /workspace. The volume disk survives a stop, and a network volume survives even after you terminate the pod. A network volume must be attached when you create the pod, and it pins the pod to that volume's data center.
How does billing work for a PyTorch pod?
Pods are billed per second for compute and for container and volume disk. A stopped pod stops billing for compute but continues to bill for its volume disk at twice the running rate. Terminate the pod when you no longer need its data.
Choose the version your work depends on
PyTorch 2.4 with CUDA 12.4 still runs on every Ampere, Ada and Hopper GPU on Runpod Secure Cloud, through the official template or a venv on a current template. Before starting a job, run the verification script to confirm that the host driver supports the runtime and the wheel contains compatible GPU kernels. In the benchmark above, the 2.4 pin adds about 11 to 16% to GPU time. PyTorch 2.4 also cannot run on Blackwell. Move to the current PyTorch template once you no longer need 2.4 to reproduce results or satisfy a dependency.
Sources
- PyTorch 2.4 release blog, pytorch.org/blog/pytorch2-4
- PyTorch previous versions and install commands, pytorch.org/get-started/previous-versions
- PyTorch 2.4 wheel build script (TORCH_CUDA_ARCH_LIST for CUDA 12.4), github.com/pytorch/builder, branch release/2.4, manywheel/build_cuda.sh
- PyTorch 2.4 source for torch.cuda.amp deprecations, pytorch.org/docs/2.4
- PyTorch 2.4.1 source for the extension CUDA version check (torch/utils/cpp_extension.py) and the incompatible GPU warning (torch/cuda/__init__.py), github.com/pytorch/pytorch, tag v2.4.1
- PyTorch CUDA 12.4 wheel index (Python versions for torch 2.4.1), download.pytorch.org/whl/cu124
- PyTorch 2.7 release blog (Blackwell and CUDA 12.8 wheels), pytorch.org/blog/pytorch-2-7
- PyTorch 2.15 release blog, October 28, 2026, pytorch.org/blog/pytorch-2-15-release-blog
- NVIDIA CUDA 12.4 Update 1 release notes (driver versions), docs.nvidia.com
- NVIDIA CUDA GPU compute capability table, developer.nvidia.com/cuda-gpus
- NVIDIA Ada and Blackwell compatibility guides, docs.nvidia.com
- Runpod Pods pricing and billing documentation, docs.runpod.io
- Runpod official template catalog and GPU catalog, read November 12, 2026
- Runpod training benchmark, PyTorch 2.4.1, 2.8.0 and 2.15.0 on one H100 SXM pod, November 16, 2026
- PyTorch 2.6 release blog (end of conda publishing), pytorch.org/blog/pytorch2-6
- Runpod Serverless product page (FlashBoot cold starts), runpod.io/product/serverless
Related guides
- Train Cutting-Edge AI Models with PyTorch 2.8 + CUDA 12.8 on Runpod
- Deploy PyTorch 2.2 with CUDA 12.1 on Runpod for Stable, Scalable AI Workflows
- Train Any AI Model Fast with PyTorch 2.1 + CUDA 11.8 on Runpod: The Ultimate Guide
- Unpacking Serverless GPU Pricing for AI Deployments
- Using Runpod’s Serverless GPUs to Deploy Generative AI Models
- NVIDIA RTX A5000 GPU: Specs, VRAM, and AI Workloads
- NVIDIA A100 GPU: Specs, Clusters, MIG, and Cloud Rental
Author profile: The Runpod Team