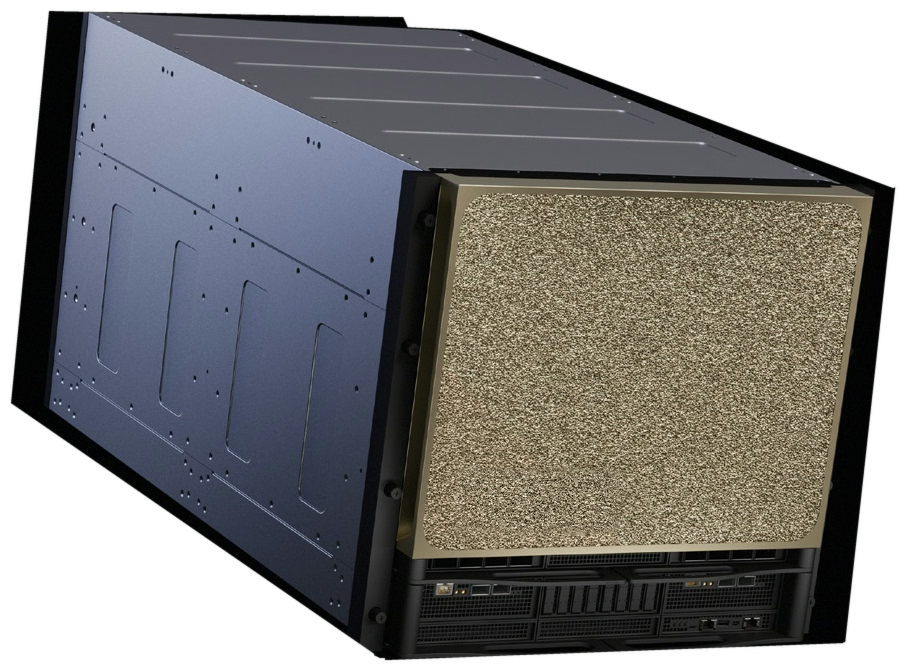
B300
Next-generation data center GPU based on NVIDIA Blackwell Ultra architecture with 288 GB HBM3e memory, delivering 1.5x FP4 performance and 2x attention performance over the B200 for AI reasoning and real-time inference workloads.
 Skip to main content
GPU Benchmarks
Compare performance across LLMs and image models to find the best GPU for your workload.

Runpod measured both GPUs in September 2026 on single-GPU Secure Cloud pods. LLM benchmarks used vLLM 0.28/0.29, and image benchmarks used Hugging Face Diffusers. These figures replace the earlier B300 estimates.
| Workload | B300 | H200 |
|---|---|---|
| Llama 3.1 8B, single user | 242.3 tok/s | 200.4 tok/s |
| Llama 3.1 8B, chat peak | 16,855 tok/s | 15,605 tok/s |
| Llama 3.1 8B, RAG peak | 13,624 tok/s | 5,924 tok/s |
| Llama 3.1 8B, long-generation observed peak | 23,582 tok/s* | 15,630 tok/s |
| Qwen2.5 7B, single user | 266.1 tok/s | 204.6 tok/s |
| Qwen2.5 7B, chat peak | 16,769 tok/s | 19,170 tok/s |
| Qwen2.5 7B, RAG peak | 17,157 tok/s | 9,851 tok/s |
| Qwen2.5 7B, long-generation peak | 24,411 tok/s | 20,560 tok/s |
*The request-rate ladder had not reached a verified plateau, so the marked result is a measured lower bound rather than a confirmed ceiling. Single-user rows use one request in flight. Peak rows report the highest sustained output rate observed on the workload ladder.
| Workload | B300 | H200 |
|---|---|---|
| FLUX.1-dev, 1024x1024, 28 steps, batch 1 | 4.01 sec/image | 5.66 sec/image |
| FLUX.1-dev, 1024x1024, 28 steps, batch 4 | 3.84 sec/image | 5.58 sec/image |
| SDXL, 1024x1024, 20 steps, batch 1 | 0.90 sec/image | 1.06 sec/image |
| SDXL, 1024x1024, 40 steps, batch 1 | 1.67 sec/image | 2.01 sec/image |
| SDXL, 1024x1024, 20 steps, batch 4 | 0.57 sec/image | 0.86 sec/image |
Lower time is better for image generation. B300 was faster than H200 on every 1024x1024 image row shown in this benchmark vintage.
B300 leads H200 on single-user throughput for both models, every Llama row shown, Qwen RAG and long generation, and all five image rows. H200 leads on the Qwen chat peak. The B300 Llama long-generation result remains a measured lower bound because the ladder had not reached a verified plateau.
Runpod benchmark measurements from September 2026, using vLLM.
Next-generation data center GPU based on NVIDIA Blackwell Ultra architecture with 288 GB HBM3e memory, delivering 1.5x FP4 performance and 2x attention performance over the B200 for AI reasoning and real-time inference workloads.
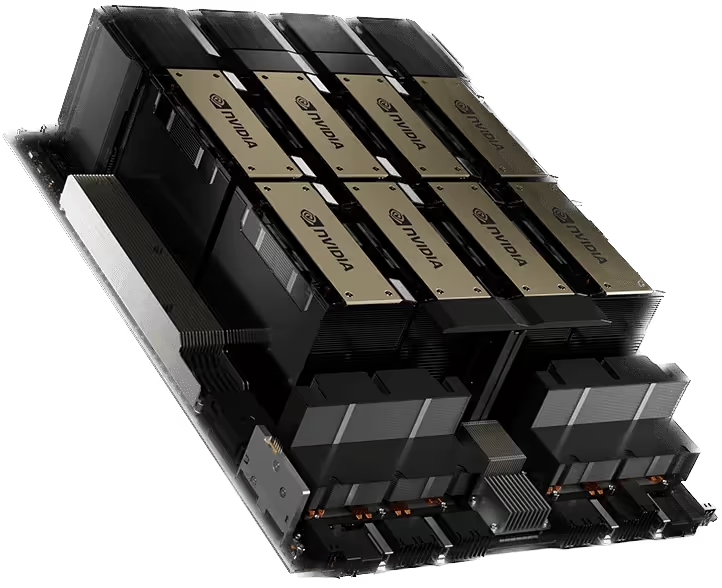
High-performance data center GPU based on Hopper architecture with 141GB HBM3e memory and 4.8TB/s bandwidth for accelerating generative AI and HPC workloads.
High-efficiency LLM processing at 90.98 tok/s.
Runpod benchmark measurements from September 2026, using Hugging Face Diffusers.
Unmatched image gen speed with 49.9 images per minute.
AI image processing at 40.3 images per minute.
Pro-grade performance with 36 images per minute.
Case Studies

"We didn't seriously evaluate other alternatives before committing to Runpod. We found their approach interesting from the beginning, particularly the ease of integration, and we haven't had a reason to switch since."

"AWS is very reliable and has everything we need, but it is way more expensive than Runpod. With Runpod, we can choose the right card for the job."
"Runpod is easily one of the most scalable tools that we use in our infrastructure."
"What's happened is, moving to Runpod, Botto has a better GPU, better graphic models and better resources, but it also costs less. That's something I didn't expect we were going to have."


"You guys have genuinely changed the scope of what we've been able to attempt."
"All of these projects, the renders for AMD, the Coca-Cola builds, that has to do with scalability. If we can't scale, we can't deliver. Runpod makes that possible."
"Runpod has changed the way we ship because we no longer have to wonder if we have access to GPUs. We've saved probably 90% on our infrastructure bill, mainly because we can use bursty compute whenever we need it."

"Runpod has allowed the team to focus more on the features that are core to our product and that are within our skill set, rather than spending time focusing on infrastructure, which can sometimes be a bit of a distraction.”

"Runpod helped us scale the part of our platform that drives creation. That’s what fuels the rest, image generation, sharing, remixing. It starts with training."

"Runpod allowed us to reliably handle scaling from zero to over 1,000 requests per second in our live application."

"Runpod has allowed us to focus entirely on growth and product development without us having to worry about the GPU infrastructure at all."

"We could stop worrying about infrastructure and go back to building. That’s the real win.”

“The main value proposition for us was the flexibility Runpod offered. We were able to scale up effortlessly to meet the demand at launch.”

"After migration, we were able to cut down our server costs from thousands of dollars per day to only hundreds."
Runpod’s scalable GPU infrastructure gave us the flexibility we needed to match customer traffic and model complexity, without overpaying for idle resources.